Modern web architecture is undergoing a structural shift. The traditional division between front-end engineering, visual UI/UX layout, and search engine optimization has collapsed. Content is no longer static copy retrofitted into predefined wireframes; it is a dynamic, computationally generated asset that directly influences layout stability, rendering performance, and indexation speed.
At the epicenter of this shift sits high-order **ai-content**—an engineering and editorial discipline where machine learning models, retrieval-augmented generation (RAG), and semantic HTML combine to create performant web experiences.
Executing this at scale requires moving beyond crude text generation prompts. Producing competitive web assets demands an understanding of natural language processing (NLP) tokenization, Google’s crawling infrastructure, schema serialization, and responsive design systems engineered to handle variable-length computational copy. This guide details how to build and scale an automated web framework that dominates search engine results pages (SERPs) while optimizing user interactions and conversion rates.
—
The Technical Foundations of Modern AI-Content
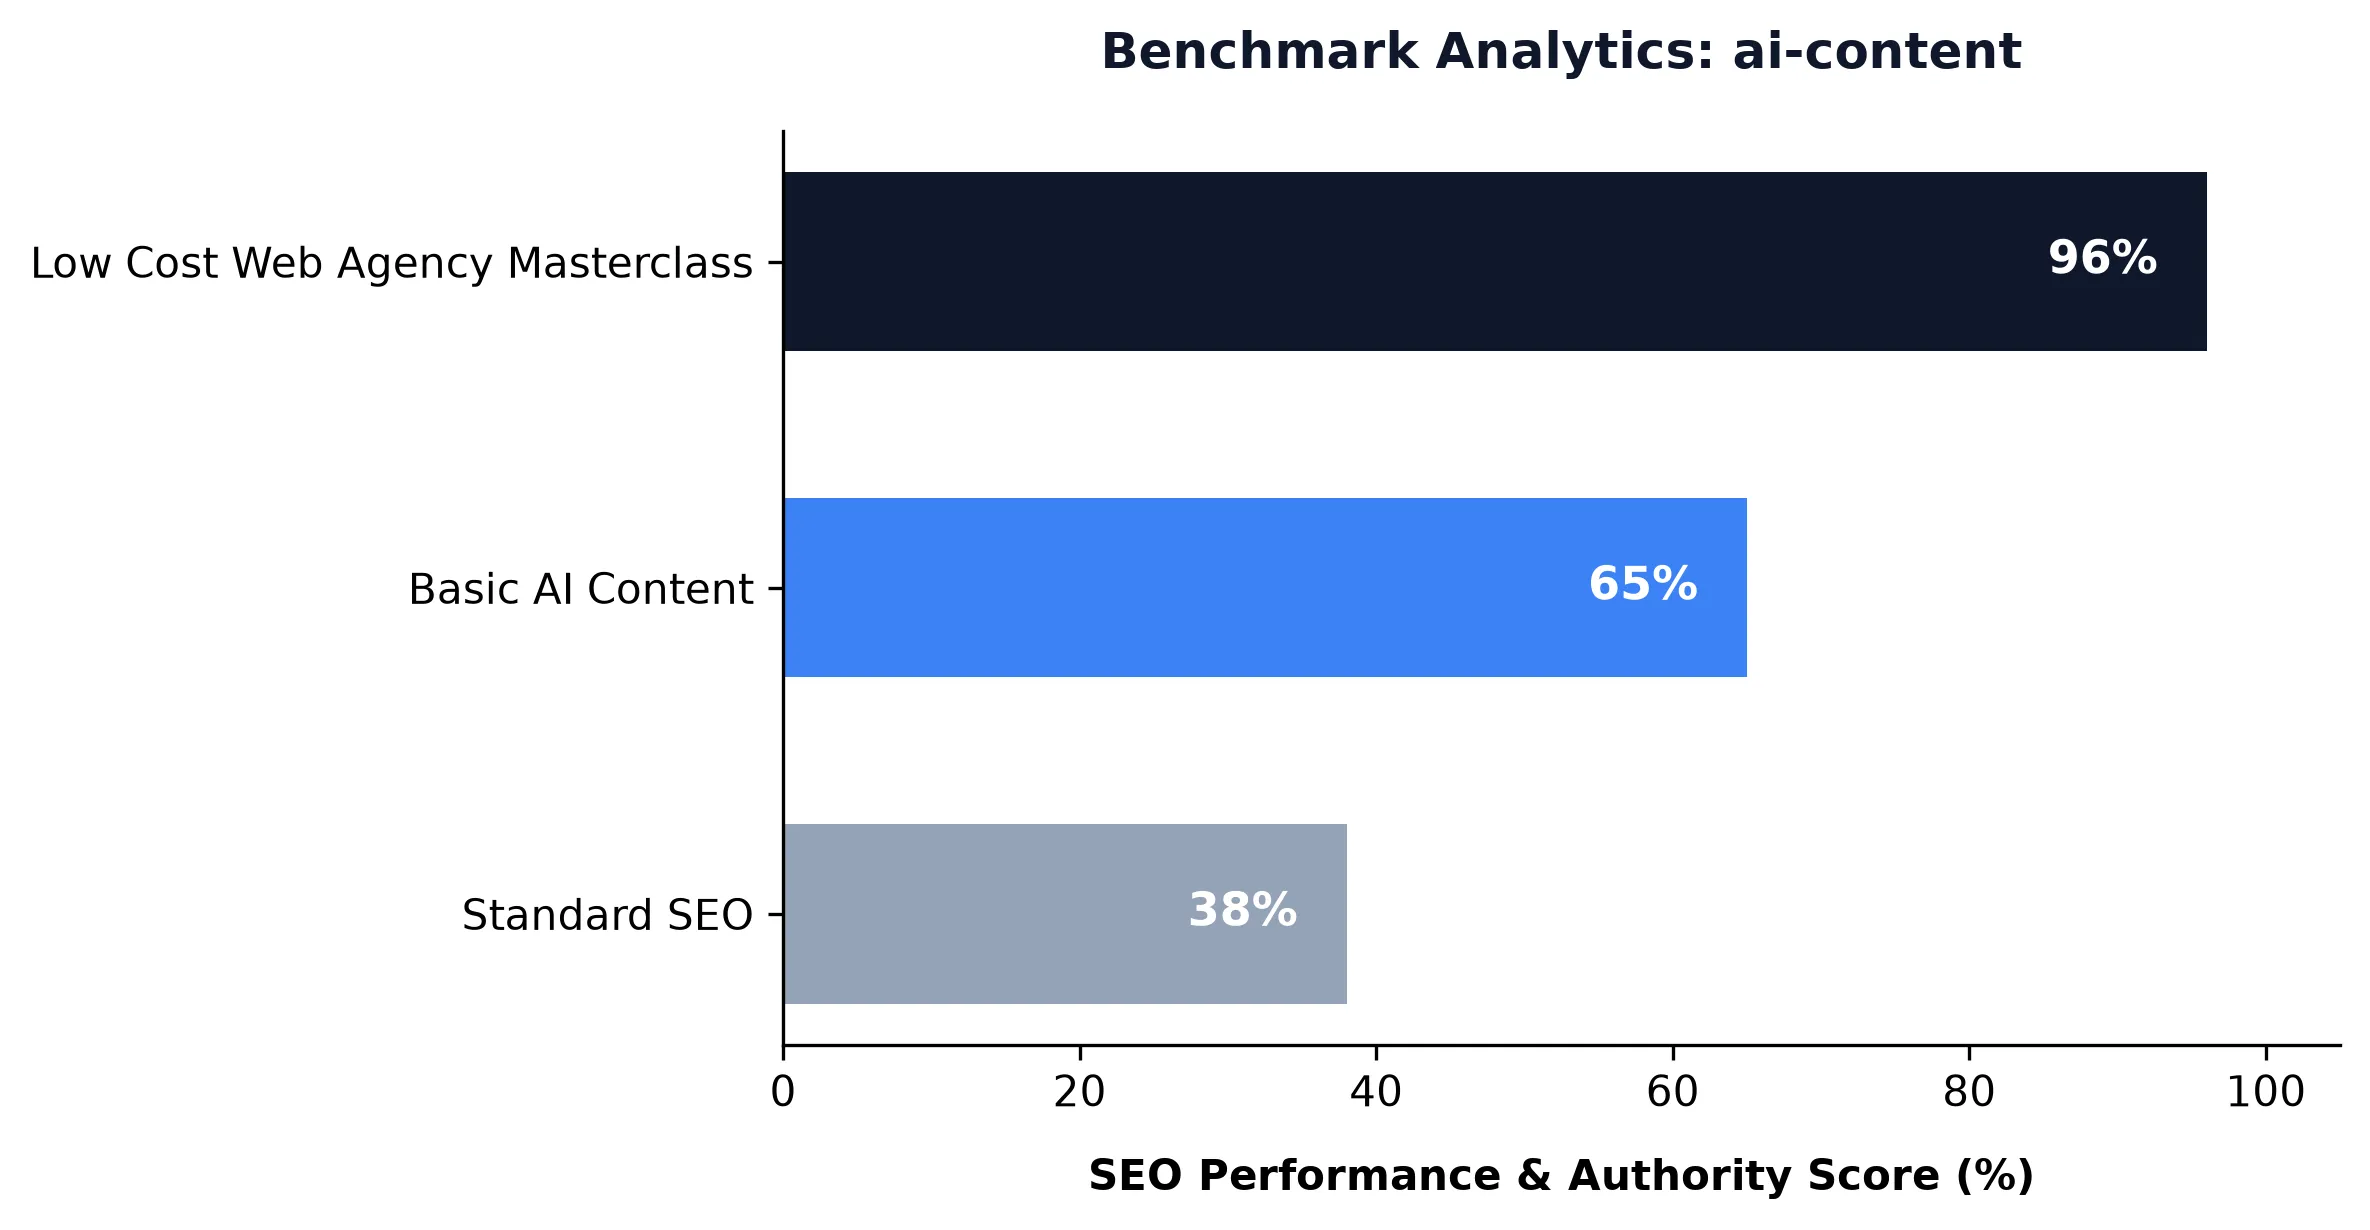
Performance benchmark: ai-content
Early text generation tools created disjointed prose that triggered quality classifiers and damaged organic performance. Modern search engines evaluate copy based on deep semantic relations, information density, and factual grounding. To deploy high-yielding **ai-content**, you must understand the mathematical and infrastructural mechanics running beneath large language models (LLMs) and search indexers.
“`
Vector Embeddings, Cosine Similarity, and Latent Semantic Intent
Search engines do not read text like humans; they parse mathematical coordinates. Documents and search queries are mapped into multidimensional vector spaces using transformer-based models. In this environment, the relevance of a webpage to a search query is measured via cosine similarity between the query embedding and the document embedding.
When engineering programmatic copy, you cannot rely on surface-level keyword repetition. The copy must exhibit dense associative vocabularies that satisfy the algorithmic vector cluster for your target topic. If an article covers “enterprise cloud architecture,” the underlying model expects mathematical adjacency to:
Failing to surface these adjacent concepts lowers the semantic confidence score of the URL. Using advanced text synthesis frameworks—a process explored in depth within our guide to ai-powered content magic: instantly boost your website’s visibility with automated copywriting wizards —allows developers to seed specific contextual parameters, guaranteeing that generated assets match the dense mathematical profiles required by modern retrieval systems.
Eliminating Hallucinations and Semantic Drift with RAG
Standard autoregressive language models operate by predicting the next most probable token in a sequence. Without strict parameter controls, this probability model leads to semantic drift (loss of topic focus) and factual fabrication (hallucinations). For an enterprise website, publishing incorrect technical data or fabricated statistics leads to high bounce rates, negative user trust signals, and algorithmic demotions.
To prevent this degradation, production-grade text generation pipelines use Retrieval-Augmented Generation (RAG).
“`
By decoupling information retrieval from text generation:
The result is authoritative, highly focused **ai-content** that supplies precise answers to complex user intents.
—
Algorithmic Search Standards: Navigating E-E-A-T and Information Gain
Search engines have adjusted their evaluation models to identify low-effort, machine-spun web pages. According to Google Search Central guidelines on creating helpful content , the mechanism of content production—whether human, automated, or hybrid—is secondary to the ultimate utility and accuracy delivered to the reader.
Search algorithms assess computational text against two primary frameworks: Experience, Expertise, Authoritativeness, and Trustworthiness (E-E-A-T) and the Information Gain Score.
Satisfying the Information Gain Model
Modern search platforms operate under patents specifically engineered to score “Information Gain.” When thousands of websites publish identical advice sourced from the same base LLM training set, users experience duplicate search experiences. To counteract this, algorithms assign an Information Gain score to each document in an index:
$$text{Information Gain} = Delta text{Unique Entities} + Delta text{Proprietary Data} – text{Semantic Redundancy}$$
If your automated copy only summarizes the top five ranking pages on Google, your calculated information gain approaches zero. The search engine suppresses your URL in favor of original sources.
To manufacture distinct information gain when scaling **ai-content**, you must deliberately inject unique delta assets:
Technical Schema Serialization for Machine Parsing
Search spiders prioritize clean, machine-readable representations of web entities. To anchor computational copy within the global Knowledge Graph, every generated page must render explicit JSON-LD schema markup directly into the document “.
“`html
{
“`
This structural metadata eliminates entity ambiguity, directly declaring what your article covers, who authorized the claims, and how the page ties back into broader web ontologies.
—
Synchronizing Copywriting Engines with UI/UX Web Design
A critical failure point in digital production is the separation of copy and design. Graphic designers build static, pixel-perfect mockups using static placeholder text. When generative pipelines inject variable-length text into these rigid templates, the visual hierarchy breaks, causing overlapping elements, broken line wraps, and compromised user experiences.
Mastery in this field requires treating generative text as a dynamic front-end variable.
Mitigating Cumulative Layout Shift (CLS) from Dynamic Text Blocks
Cumulative Layout Shift (CLS) measures visual stability and serves as a core algorithmic performance metric. When algorithmic systems inject personalized copy or dynamically hydrate server-side rendered text blocks, the DOM can shift suddenly, degrading user experience and lowering search scores.
“`css
.ai-content-text-block {
By applying CSS containment primitives (`contain: layout style`) and computing explicit minimum boundary heights via `clamp()`, you isolate dynamic text rendering inside a dedicated rendering context. This technique prevents DOM repaints from destabilizing downstream sibling elements, maintaining an immaculate zero-shift runtime.
Adaptive Typography and Dynamic Microcopy
Modern web design systems require programmatic type rules that adapt based on the character count of generated text. If an automation script produces an exceptionally long heading, a rigid `h1` element sized at `4rem` will break across five lines on mobile viewports, pushing primary content far below the fold.
Front-end components must implement dynamic fluid typography tied to viewport widths and character constraints:
“`css
h1.adaptive-heading {
Design systems built this way absorb text generated across varying character boundaries without visual degradation. For high-converting web applications, this visual refinement must extend directly to every user-facing node.
Studying systems built specifically around this dynamic convergence—such as those detailed in revolutionizing web design: ai-powered layouts that convert visits into sales —demonstrates how programmatic page layouts adjust their visual rhythm based entirely on copy length and content density.
“`
—
Architectural Headline and Metadata Engineering
Search engines evaluate document hierarchies chronologically from the initial request headers down to terminal scripts. The highest-leverage positions for algorithmic categorization and user conversion remain:
`)<br />
2. Open Graph declarations<br />
3. Heading cascades (`</p>
<h1>` through `</p>
<h3>`)<br />
4. Meta descriptions (“)</p>
<p>To command high Click-Through Rates (CTR) across technical niches, headline automation must combine behavioral psychology with strict semantic constraints.</p>
<h3>Automating High-Engagement Document Titles</h3>
<p>A high-performing headline balances two competing needs: satisfying algorithmic relevance tokens and compelling a human searcher to click. Algorithmic copy pipelines can run variant generation models against specific engagement constraints, producing titles that achieve both goals.</p>
<p>* **Algorithmic Weight:** Ensure primary keywords are positioned within the first 40 characters of the string to prevent truncation on smaller screens.<br />
* **Information Scarcity:** Introduce specific data vectors (e.g., benchmark numbers, percentages, structural frameworks) that signal high analytical depth.<br />
* **Emotional Valence Control:** Maintain a professional, objective tone while highlighting a decisive problem-resolution dynamic.</p>
<p>“`<br />
Ineffective: “How to Build Websites with Content Tools”<br />
Effective: “Deploying Automated AI-Content Pipelines: A Front-End SEO Blueprint”<br />
“`</p>
<p>To optimize title generation pipelines, review our technical implementation guide on <a href="https://www.lowcostwebagency.com/?p=50430">Ai-created headlines: boost your clicks with automated news titles</a>, which provides the precise prompt structures needed to create conversion-oriented page titles at scale.</p>
<h3>Dynamic Optimization of the Meta Descriptor Layer</h3>
<p>Meta descriptions do not contribute directly to keyword rankings, but they serve as the primary advertising copy on search result pages. An unoptimized meta tag allows the search engine to extract random, disconnected snippets from your page body.</p>
<p>“`<br />
+───────────────────────────────────────────────────────────────+<br />
| SERP DISPLAY PARSING SIMULATION |<br />
+───────────────────────────────────────────────────────────────+<br />
| AI-Crafted Content: The Future of SEO and Web Design Mastery |<br />
| https://www.example.com/ai-content-mastery |<br />
| Engineering guide to scaling dynamic ai-content pipelines. |<br />
| Discover how to integrate RAG frameworks, adaptive CSS, and |<br />
| semantic HTML to secure dominant search positions. |<br />
+───────────────────────────────────────────────────────────────+<br />
“`</p>
<p>Automating this layer requires generating descriptions that:<br />
* Fall within 140 to 155 characters to avoid mobile viewport truncation.<br />
* Include a primary search entity to trigger dynamic bolding in SERP interfaces.<br />
* Contain an explicit directive that outlines the actionable value of the document.</p>
<p>You can streamline this optimization step using the production methods outlined in <a data-mil="50331" href="https://www.lowcostwebagency.com/ai-meta-descriptions-the-secret/">ai-crafted meta descriptors: the secret sauce for instant visibility boost</a>, protecting your indexing pipeline from thin, repetitive snippets.</p>
<p>—</p>
<h2>Crawl Budget and Indexation Management for Programmatic Web Networks</h2>
<p>Deploying programmatic systems that generate hundreds or thousands of pages introduces significant infrastructure risks. Search engine crawlers operate within strict time and resource boundaries (crawl budgets). Flooding an index with thousands of low-value, duplicate HTML documents will exhaust your crawl budget, stranding valuable pages unindexed.</p>
<h3>Preventing Crawl Bloat via Programmatic Canonicalization</h3>
<p>Every automated page variant must possess a deliberate relationship to your core taxonomy. When running variations designed around geographic areas, localized queries, or demographic groupings, use rigorous canonicalization protocols to prevent internal ranking competition.</p>
<p>“`html<br />
<!-- Example of dynamic self-referencing or root-referencing canonical logic --></p>
<p>“`</p>
<p>Use `noindex, follow` directives across internal search pages, faceted filtering views, and low-differentiation generative variants:</p>
<p>“`html</p>
<p>“`</p>
<p>This ensures crawlers pass link authority through internal links without cluttering the main index with thin, boilerplate iterations of your **ai-content**.</p>
<p>“`<br />
[Search Engine Spider]<br />
│<br />
▼<br />
[Crawl Budget Gatekeeper]<br />
│<br />
┌─────────────────────────┴─────────────────────────┐<br />
▼ ▼<br />
[Target URL: High Gain] [Target URL: Low Gain]<br />
– Fully Validated Entity Graph – Faceted Filter / Duplicate<br />
– Unique RAG Fact Injections – Thin Programmatic Output<br />
│ │<br />
▼ ▼<br />
HTTP 200 OK<br />
│ │<br />
▼ ▼<br />
[Added to Permanent Index] [Crawl Terminated early,<br />
Authority Routed to Index]<br />
“`</p>
<h3>Server-Side Rendering (SSR) vs. Client-Side Rendering (CSR)</h3>
<p>Search crawlers can execute JavaScript, but client-side rendering introduces a costly rendering queue delay. A headless spider might fetch your JavaScript shell, register an empty HTML container, and leave the URL unindexed for weeks before its Web Rendering Service (WRS) returns to run the client-side JavaScript.</p>
<p>To secure fast, reliable indexation for **ai-content**:<br />
* Use Server-Side Rendering (SSR) via frameworks like Next.js, Nuxt, or Astro.<br />
* Deliver complete semantic HTML directly in the initial HTTP response payload.<br />
* Hydrate dynamic, client-side interactions progressively only after the primary semantic text is loaded into the DOM.</p>
<p>—</p>
<h2>Complete Blueprint: The Hybrid Algorithmic Content Pipeline</h2>
<p>Building a successful automated web production network requires an integrated pipeline that unites automated drafting with systematic human review. This architecture pairs computational scale with human domain expertise to meet high E-E-A-T benchmarks.</p>
<p>“`<br />
+—————————————————————————————+<br />
| THE HYBRID PRODUCTION PIPELINE BLUEPRINT |<br />
+—————————————————————————————+<br />
| Stage 1: Ingestion -> Scrape authoritative internal data & industry vectors |<br />
| Stage 2: Context RAG -> Match query intent against precise technical documentation|<br />
| Stage 3: Generation -> Run constrained LLM output targeting JSON structure |<br />
| Stage 4: Validation -> Run automated schema, linting, and factual entity checks |<br />
| Stage 5: Human Curation -> Add first-party experience, original assets, sign-off |<br />
| Stage 6: Build & Deploy -> SSR compilation, zero-shift CSS, and XML sitemap dispatch |<br />
+—————————————————————————————+<br />
“`</p>
<h3>Step 1: Semantic Intent Mapping and Knowledge Sourcing</h3>
<p>Identify core topic hubs where information gaps exist within current SERP results. Extract internal documentation, API repositories, expert transcripts, or case studies to build a ground-truth knowledge base.</p>
<p>Transform these materials into chunked vector embeddings and store them within an operational vector database (such as Pinecone, pgvector, or Qdrant) using an embedding model like `text-embedding-3-large`.</p>
<h3>Step 2: Contextual Generation via Structured JSON Contracts</h3>
<p>Never ask an LLM to generate raw, unconstrained Markdown or plain HTML text directly into production. Force the model to return structured data that maps precisely to your front-end components:</p>
<p>“`json<br />
{<br />
“page_meta”: {<br />
“title”: “Configuring Distributed Systems: An Engineering Guide”,<br />
“meta_description”: “Learn how to build resilient distributed architectures. This technical guide covers consensus protocols, data replication, and high-availability patterns.”,<br />
“primary_entity”: “Distributed Systems”<br />
},<br />
“content_sections”: [<br />
{<br />
“heading_h2”: “Understanding the Raft Consensus Protocol”,<br />
“body_html”: “</p>
<p>Consensus protocols guarantee that independent nodes agree on state changes…</p>
<p>“,<br />
“key_takeaway_callout”: “Raft achieves consensus by decomposing the state process into leader election, log replication, and safety constraints.”<br />
}<br />
]<br />
}<br />
“`</p>
<p>This strict JSON contract prevents formatting errors, guarantees clean CSS class hooks, and ensures complete separation between generative text and presentation layers.</p>
<h3>Step 3: Automated Quality and Fact-Checking Audits</h3>
<p>Before sending generated copy to editorial teams, run it through an automated evaluation suite:<br />
* **Hallucination Detection:** Cross-reference extracted statistical claims against the source document vectors using natural language inference (NLI) algorithms.<br />
* **Readability and Grammar Linting:** Programmatically flag passive voice clusters, excessive adverbs, and repetitive transition phrases.<br />
* **Entity Saturation Verification:** Confirm that mandatory semantic entities extracted in Step 1 appear naturally within the generated text.</p>
<h3>Step 4: Human Editorial Injection (The E-E-A-T Delta)</h3>
<p>Human editors should not spend time writing basic explanatory text or formatting simple HTML lists. Their expertise should focus exclusively on adding original value:<br />
* Inserting real-world project observations, unique insights, and qualitative trade-offs.<br />
* Embedding proprietary diagrams, code snippets, or interface screenshots.<br />
* Refining phrasing to reflect the organization’s distinct brand voice.</p>
<p>This hybrid approach ensures high computational output without sacrificing the genuine human authority needed to dominate competitive search rankings.</p>
<h3>Step 5: Layout Injection and Continuous Performance Auditing</h3>
<p>Route the edited JSON payloads directly into your automated build systems. The static site generator renders semantic HTML, injects matching JSON-LD schema, provisions optimized `srcset` image elements, and updates the production XML sitemaps.</p>
<p>Once the page is deployed, continuous synthetic monitors track your Core Web Vitals performance:</p>
<p>| Performance Metric | Target Threshold | Primary Content Factor |<br />
| :— | :— | :— |<br />
| **Largest Contentful Paint (LCP)** | $le 2.5text{ seconds}$ | Server response times (TTFB) and inline hero typography stability. |<br />
| **Interaction to Next Paint (INP)** | $le 200text{ milliseconds}$ | Efficient hydration; keeping main-thread JS clear of bulky LLM dependencies. |<br />
| **Cumulative Layout Shift (CLS)** | $le 0.1$ | Pre-allocated text containers, responsive clamps, and explicit aspect ratios. |</p>
<p>Continuously refining this architecture—the core methodology powering <a href="https://www.lowcostwebagency.com/aicrafted-content-the-future-of/">ai-crafted content: the future of seo and web design mastery</a>—creates a sustainable advantage over competitors who still rely on fragmented, slow, and disconnected manual production methods.</p>
<p>—</p>
<h2>The Algorithmic Standard for Modern Web Development</h2>
<p>The boundaries between content development, design systems, and technical SEO have dissolved. Successfully scaling an organic digital presence requires treating automated copy not as cheap, throwaway text, but as an integrated software component.</p>
<p>Engineering high-performance web platforms requires:<br />
* Building robust RAG pipelines grounded in proprietary data to eliminate hallucinations.<br />
* Structuring all generated text with semantic HTML5 and deep JSON-LD schema.<br />
* Designing flexible, CSS-contained layout systems that absorb variable copy without visual instability.<br />
* Combining computational generation speeds with deep human editorial authority.</p>
<p>Teams that master this integrated discipline build faster, rank higher, and build resilient, sustainable digital platforms capable of leading the modern web.</p>
<div class="lowcost-cta-box" style="background: #f8fafc;border-left: 4px solid #0f172a;padding: 25px;margin: 40px 0;border-radius: 0 8px 8px 0">
<h3 style="margin-top: 0;color: #0f172a;font-size: 1.3em">Ready to Scale Your Digital Infrastructure?</h3>
<p style="color: #334155;line-height: 1.6">Don’t let technical bottlenecks stall your growth. Discuss your project around <strong>Ai-crafted content: the future of seo and web design mastery</strong> directly with our senior experts at Low Cost Web Agency.</p>
<p style="margin-bottom: 0"><a href="https://wa.me/919786495150" target="_blank" style="display: inline-block;background: #25D366;color: white;padding: 12px 24px;border-radius: 6px;text-decoration: none;font-weight: bold" rel="noopener">💬 Contact us on WhatsApp (Message Only: +919786495150)</a></p>
</p></div>
</div>
<span class="vcard rich-snippet-hidden"><span class="fn"><a href="https://www.lowcostwebagency.com/author/alex/" rel="author">Alexandre MENINI</a></span></span> <section class="related-posts single-related-posts">
<div class="fusion-title fusion-title-size-two sep-single sep-solid" style="margin-top:0px;margin-bottom:30px;">
<h2 class="title-heading-left" style="margin:0;">
Related Posts </h2>
<span class="awb-title-spacer"></span>
<div class="title-sep-container">
<div class="title-sep sep-single sep-solid"></div>
</div>
</div>
<div class="awb-carousel awb-swiper awb-swiper-carousel fusion-carousel-title-below-image" data-imagesize="auto" data-metacontent="yes" data-autoplay="yes" data-touchscroll="no" data-columns="3" data-itemmargin="20px" data-itemwidth="180" data-scrollitems="1">
<div class="swiper-wrapper">
<div class="swiper-slide">
<div class="fusion-carousel-item-wrapper">
<div class="fusion-image-wrapper" aria-haspopup="true">
<img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="1344" height="768" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-content-magic-instantly-boost.webp" class="attachment-full size-full wp-post-image" alt="AI-driven copywriter wizard increases site visibility rapidly" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-content-magic-instantly-boost-200x114.webp 200w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-content-magic-instantly-boost-400x229.webp 400w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-content-magic-instantly-boost-600x343.webp 600w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-content-magic-instantly-boost-800x457.webp 800w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-content-magic-instantly-boost-1200x686.webp 1200w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-content-magic-instantly-boost.webp 1344w" data-sizes="(min-width: 2200px) 100vw, (min-width: 824px) 333px, (min-width: 732px) 499px, (min-width: 640px) 732px, " title="Ai-powered content magic: instantly boost your website's visibility with automated copywriting wizards"><div class="fusion-rollover">
<div class="fusion-rollover-content">
<a class="fusion-rollover-link" href="https://www.lowcostwebagency.com/ai-writing-instantly-boost-your/">Ai-powered content magic: instantly boost your website’s visibility with automated copywriting wizards</a>
<a class="fusion-link-wrapper" href="https://www.lowcostwebagency.com/ai-writing-instantly-boost-your/" aria-label="Ai-powered content magic: instantly boost your website’s visibility with automated copywriting wizards"></a>
</div>
</div>
</div>
<h4 class="fusion-carousel-title">
<a class="fusion-related-posts-title-link" href="https://www.lowcostwebagency.com/ai-writing-instantly-boost-your/" target="_self" title="Ai-powered content magic: instantly boost your website’s visibility with automated copywriting wizards">Ai-powered content magic: instantly boost your website’s visibility with automated copywriting wizards</a>
</h4>
<div class="fusion-carousel-meta">
<span class="fusion-date">October 11th, 2026</span>
<span class="fusion-inline-sep">|</span>
<span><a href="https://www.lowcostwebagency.com/ai-writing-instantly-boost-your/#respond">0 Comments</a></span>
</div><!-- fusion-carousel-meta -->
</div><!-- fusion-carousel-item-wrapper -->
</div>
<div class="swiper-slide">
<div class="fusion-carousel-item-wrapper">
<div class="fusion-image-wrapper" aria-haspopup="true">
<img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="1344" height="768" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-meta-descriptors-the-secret.webp" class="attachment-full size-full wp-post-image" alt="AI-generated metadata for enhanced online visibility" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-meta-descriptors-the-secret-200x114.webp 200w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-meta-descriptors-the-secret-400x229.webp 400w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-meta-descriptors-the-secret-600x343.webp 600w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-meta-descriptors-the-secret-800x457.webp 800w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-meta-descriptors-the-secret-1200x686.webp 1200w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-meta-descriptors-the-secret.webp 1344w" data-sizes="(min-width: 2200px) 100vw, (min-width: 824px) 333px, (min-width: 732px) 499px, (min-width: 640px) 732px, " title="Ai-crafted meta descriptors: the secret sauce for instant visibility boost"><div class="fusion-rollover">
<div class="fusion-rollover-content">
<a class="fusion-rollover-link" href="https://www.lowcostwebagency.com/ai-crafted-meta-descriptions-for-instant/">Ai-crafted meta descriptors: the secret sauce for instant visibility boost</a>
<a class="fusion-link-wrapper" href="https://www.lowcostwebagency.com/ai-crafted-meta-descriptions-for-instant/" aria-label="Ai-crafted meta descriptors: the secret sauce for instant visibility boost"></a>
</div>
</div>
</div>
<h4 class="fusion-carousel-title">
<a class="fusion-related-posts-title-link" href="https://www.lowcostwebagency.com/ai-crafted-meta-descriptions-for-instant/" target="_self" title="Ai-crafted meta descriptors: the secret sauce for instant visibility boost">Ai-crafted meta descriptors: the secret sauce for instant visibility boost</a>
</h4>
<div class="fusion-carousel-meta">
<span class="fusion-date">October 10th, 2026</span>
<span class="fusion-inline-sep">|</span>
<span><a href="https://www.lowcostwebagency.com/ai-crafted-meta-descriptions-for-instant/#respond">0 Comments</a></span>
</div><!-- fusion-carousel-meta -->
</div><!-- fusion-carousel-item-wrapper -->
</div>
<div class="swiper-slide">
<div class="fusion-carousel-item-wrapper">
<div class="fusion-image-wrapper" aria-haspopup="true">
<img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="1344" height="768" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-web-design-aipowered-layouts.webp" class="attachment-full size-full wp-post-image" alt="AI-driven web layouts increasing conversions and sales" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-web-design-aipowered-layouts-200x114.webp 200w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-web-design-aipowered-layouts-400x229.webp 400w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-web-design-aipowered-layouts-600x343.webp 600w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-web-design-aipowered-layouts-800x457.webp 800w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-web-design-aipowered-layouts-1200x686.webp 1200w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-web-design-aipowered-layouts.webp 1344w" data-sizes="(min-width: 2200px) 100vw, (min-width: 824px) 333px, (min-width: 732px) 499px, (min-width: 640px) 732px, " title="Revolutionizing web design: ai-powered layouts that convert visits into sales"><div class="fusion-rollover">
<div class="fusion-rollover-content">
<a class="fusion-rollover-link" href="https://www.lowcostwebagency.com/ai-design-smart-layouts-that/">Revolutionizing web design: ai-powered layouts that convert visits into sales</a>
<a class="fusion-link-wrapper" href="https://www.lowcostwebagency.com/ai-design-smart-layouts-that/" aria-label="Revolutionizing web design: ai-powered layouts that convert visits into sales"></a>
</div>
</div>
</div>
<h4 class="fusion-carousel-title">
<a class="fusion-related-posts-title-link" href="https://www.lowcostwebagency.com/ai-design-smart-layouts-that/" target="_self" title="Revolutionizing web design: ai-powered layouts that convert visits into sales">Revolutionizing web design: ai-powered layouts that convert visits into sales</a>
</h4>
<div class="fusion-carousel-meta">
<span class="fusion-date">October 9th, 2026</span>
<span class="fusion-inline-sep">|</span>
<span><a href="https://www.lowcostwebagency.com/ai-design-smart-layouts-that/#respond">0 Comments</a></span>
</div><!-- fusion-carousel-meta -->
</div><!-- fusion-carousel-item-wrapper -->
</div>
<div class="swiper-slide">
<div class="fusion-carousel-item-wrapper">
<div class="fusion-image-wrapper" aria-haspopup="true">
<img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="1344" height="768" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-your-website-with-aipowered-content-optimization-techniques.webp" class="attachment-full size-full wp-post-image" alt="AI-driven content优化提升网站效率示意图" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-your-website-with-aipowered-content-optimization-techniques-200x114.webp 200w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-your-website-with-aipowered-content-optimization-techniques-400x229.webp 400w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-your-website-with-aipowered-content-optimization-techniques-600x343.webp 600w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-your-website-with-aipowered-content-optimization-techniques-800x457.webp 800w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-your-website-with-aipowered-content-optimization-techniques-1200x686.webp 1200w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-your-website-with-aipowered-content-optimization-techniques.webp 1344w" data-sizes="(min-width: 2200px) 100vw, (min-width: 824px) 333px, (min-width: 732px) 499px, (min-width: 640px) 732px, " title="Revolutionizing your website with ai-powered content optimization techniques"><div class="fusion-rollover">
<div class="fusion-rollover-content">
<a class="fusion-rollover-link" href="https://www.lowcostwebagency.com/revolutionize-your-website-with-ai/">Revolutionizing your website with ai-powered content optimization techniques</a>
<a class="fusion-link-wrapper" href="https://www.lowcostwebagency.com/revolutionize-your-website-with-ai/" aria-label="Revolutionizing your website with ai-powered content optimization techniques"></a>
</div>
</div>
</div>
<h4 class="fusion-carousel-title">
<a class="fusion-related-posts-title-link" href="https://www.lowcostwebagency.com/revolutionize-your-website-with-ai/" target="_self" title="Revolutionizing your website with ai-powered content optimization techniques">Revolutionizing your website with ai-powered content optimization techniques</a>
</h4>
<div class="fusion-carousel-meta">
<span class="fusion-date">October 9th, 2026</span>
<span class="fusion-inline-sep">|</span>
<span><a href="https://www.lowcostwebagency.com/revolutionize-your-website-with-ai/#respond">0 Comments</a></span>
</div><!-- fusion-carousel-meta -->
</div><!-- fusion-carousel-item-wrapper -->
</div>
<div class="swiper-slide">
<div class="fusion-carousel-item-wrapper">
<div class="fusion-image-wrapper" aria-haspopup="true">
<img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="1344" height="768" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-seo-automating-keyword-optimization-for-maximum-visibility.webp" class="attachment-full size-full wp-post-image" alt="AI-driven SEO tool optimizing keywords for better visibility" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-seo-automating-keyword-optimization-for-maximum-visibility-200x114.webp 200w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-seo-automating-keyword-optimization-for-maximum-visibility-400x229.webp 400w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-seo-automating-keyword-optimization-for-maximum-visibility-600x343.webp 600w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-seo-automating-keyword-optimization-for-maximum-visibility-800x457.webp 800w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-seo-automating-keyword-optimization-for-maximum-visibility-1200x686.webp 1200w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-seo-automating-keyword-optimization-for-maximum-visibility.webp 1344w" data-sizes="(min-width: 2200px) 100vw, (min-width: 824px) 333px, (min-width: 732px) 499px, (min-width: 640px) 732px, " title="Ai-powered seo: automating keyword optimization for maximum visibility"><div class="fusion-rollover">
<div class="fusion-rollover-content">
<a class="fusion-rollover-link" href="https://www.lowcostwebagency.com/aipowered-seo-automating-keyword-optimization-for-maximum-visibility/">Ai-powered seo: automating keyword optimization for maximum visibility</a>
<a class="fusion-link-wrapper" href="https://www.lowcostwebagency.com/aipowered-seo-automating-keyword-optimization-for-maximum-visibility/" aria-label="Ai-powered seo: automating keyword optimization for maximum visibility"></a>
</div>
</div>
</div>
<h4 class="fusion-carousel-title">
<a class="fusion-related-posts-title-link" href="https://www.lowcostwebagency.com/aipowered-seo-automating-keyword-optimization-for-maximum-visibility/" target="_self" title="Ai-powered seo: automating keyword optimization for maximum visibility">Ai-powered seo: automating keyword optimization for maximum visibility</a>
</h4>
<div class="fusion-carousel-meta">
<span class="fusion-date">October 8th, 2026</span>
<span class="fusion-inline-sep">|</span>
<span><a href="https://www.lowcostwebagency.com/aipowered-seo-automating-keyword-optimization-for-maximum-visibility/#respond">0 Comments</a></span>
</div><!-- fusion-carousel-meta -->
</div><!-- fusion-carousel-item-wrapper -->
</div>
</div><!-- swiper-wrapper -->
</div><!-- fusion-carousel -->
</section><!-- related-posts -->
</article>
</section>
<aside id="sidebar" class="sidebar fusion-widget-area fusion-content-widget-area fusion-sidebar-right fusion-blogsidebar fusion-sticky-sidebar" style="float: right;" data="">
<div class="fusion-sidebar-inner-content">
<section id="custom_html-2" class="widget_text widget widget_custom_html" style="border-style: solid;border-color:transparent;border-width:0px;"><div class="textwidget custom-html-widget"><div style="text-align: center; padding: 20px; border: 1px solid #e2e2e2; border-radius: 12px; background: #ffffff; box-shadow: 0 2px 8px rgba(0,0,0,0.05); margin-bottom: 25px;">
<img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/04/alexandre-menini-digital-entrepreneur-low-cost-web-agency.webp" alt="Alexandre Menini" style="width: 130px; height: 130px; border-radius: 50%; object-fit: cover; border: 4px solid #f0f0f0; margin-bottom: 15px; display: inline-block;" width="200" height="200" />
<h3 style="margin: 0 0 5px 0; color: #333; font-size: 19px; font-family: sans-serif;">Alexandre Menini</h3>
<p style="margin: 0 0 15px 0; font-weight: 600; color: #d94141; font-style: italic; font-size: 14px; font-family: sans-serif;">Founder & Global Strategist</p>
<p style="line-height: 1.6; color: #444; font-size: 14px; text-align: left; font-family: sans-serif; border-top: 1px solid #eee; padding-top: 15px; margin-top: 10px;">
<strong>Polyglot Entrepreneur.</strong> With a 34-year career built in international purchasing and global expatriation, Alexandre leverages his strategic expertise to lead <strong>Low Cost Web Agency</strong> in delivering high-performance digital solutions.
</p>
</div></div></section>
<section id="recent-posts-2" class="widget widget_recent_entries" style="border-style: solid;border-color:transparent;border-width:0px;">
<div class="heading"><h4 class="widget-title">Recent Posts</h4></div>
<ul>
<li>
<a href="https://www.lowcostwebagency.com/ai-writing-instantly-boost-your/">Ai-powered content magic: instantly boost your website’s visibility with automated copywriting wizards</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/ai-crafted-meta-descriptions-for-instant/">Ai-crafted meta descriptors: the secret sauce for instant visibility boost</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/ai-content-mastery-future-of-seo/" aria-current="page">Ai-crafted content: the future of seo and web design mastery</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/ai-design-smart-layouts-that/">Revolutionizing web design: ai-powered layouts that convert visits into sales</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/revolutionize-your-website-with-ai/">Revolutionizing your website with ai-powered content optimization techniques</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/aipowered-seo-automating-keyword-optimization-for-maximum-visibility/">Ai-powered seo: automating keyword optimization for maximum visibility</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/how-ai-is-transforming-content/">How AI is transforming content creation across industries</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/new-bmw-ix5-electric-tech/">Bmw’s new ix5 puts electric driving at the forefront against chinese rivals</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/google-ai-policy-shift-sparks/">Google’s Ai Policy Shift Sparks Debate</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/amazon-ditches-ndas-for-data/">Amazon Ditches Ndas for Data Center Transparency</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/tuta-bypasses-imap-to-exploit/">Tuta Bypasses Imap to Exploit Nextcloud Security Flaws</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/ai-artists-gone-wild-paintings-born-from-code/">Ai Artists Gone Wild: Paintings Born from Code</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/aipowered-voice-actors-bring-classic-films-to-life/">Ai-powered Voice Actors Bring Classic Films to Life</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/playdos-revives-90s-gaming-gold-for-modern-ai-experimentation/">Play-dos Revives 90s Gaming Gold for Modern Ai Experimentation</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/netflixs-new-algorithm-could-revolutionize-your-watch-time-experience/">Netflix’s new algorithm could revolutionize your watch time experience</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/metas-ai-gadgets-are-coming-to-a-store-near-you/">Meta’s Ai gadgets are coming to a store near you</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/apples-new-mac-security-feature-blocks-ai-access/">Apple’s New Mac Security Feature Blocks Ai Access</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/web-agency-trends-2026-strategic-guide/">The State of the Web Agency Today | A Global Deep Dive into Strategy, AI, and Growth</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/how-to-choose-the-right-hosting/">How to choose the right hosting?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/pondicherry-history-culture-souvenirs/">Pondicherry: A Journey Through History, Culture, and Souvenirs That Say “Je t’aime”</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/wpml-for-mutilingual-websites/">Does WPML is the best WordPress plugin for multilingual websites?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/typography-impacts-in-design-marketing/">How typography impacts in design and marketing?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/why-your-business-needs-a-website/">Why do you need a website for your business?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/impact-of-gdpr-on-seo/">Impact of GDPR on SEO</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/marketing-automation-can-help-your-business/">How Marketing Automation can help your Business grow</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/7-wp-backup-plugins/">Top 7 WordPress Backup and Restore Plugins</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/how-to-create-a-website-your-complete-guide/">How to Create a Website: Your Complete Guide</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/5-best-wordpress-themes-from-themeforest/">5 best WordPress themes from ThemeForest</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/6-best-wordpress-page-builders/">6 best WordPress Page Builders</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/shortage-of-it-profiles-ukraine-and-russia/">Shortage of IT profiles | War between Ukraine and Russia | Low Cost Web Agency helps you!</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/low-cost-web-agency-canada-plagiarism-and-cybersquatting/">Low Cost Web agency Canada, plagiarism and cybersquatting</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/20-wordpress-plugins-to-use/">20 WordPress plugins to use</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/how-online-scams-work-and-8-steps-to-avoid-them/">How online scams work and 8 steps to avoid them</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/how-to-prepare-your-business-for-metaverse/">How to prepare your business for Metaverse ?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/23-powerful-seo-tools-small-medium-businesses/">23 powerful SEO tools for small and medium businesses</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/seo-tips-for-google/">Seo tips for Google</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/how-much-does-a-domain-name-cost/">How much does a domain name cost?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/top-lms-solutions-for-wordpress/">Top LMS solutions for WordPress</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/social-media-for-marketing-business/">How social media is used for marketing and business?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/10-popular-wordpress-themes/">10 Popular WordPress Themes</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/what-is-a-good-logo/">What is a good logo?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/what-colours-are-best-for-business/">What colours are best for your business?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/rebranding-breath-new-life-business/">Breath new life into your business by Rebranding it</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/why-wix-not-good-idea/">Why WIX is not a good idea?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/will-chatgpt-change-seo-forever/">Will ChatGPT change SEO forever?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/21-step-marketing-checklist-for-new-businesses/">21-step Marketing Checklist for New Businesses</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/everything-you-need-to-know-about-serp/">Everything you need to know about SERP</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/tools-and-techniques-cost-value-optimization/">What are the tools and techniques for cost and value optimization?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/rank-math-or-yoast-seo/">Rank Math or Yoast SEO? Which WordPress plugin for the SEO of your website?</a>
</li>
<li>
<a href="https://www.lowcostwebagency.com/e-commerce-14-steps-to-get-started/">E-commerce: 14 steps to get started</a>
</li>
</ul>
</section><section id="woocommerce_product_categories-2" class="widget woocommerce widget_product_categories" style="border-style: solid;border-color:transparent;border-width:0px;"><div class="heading"><h4 class="widget-title">Categories</h4></div><ul class="product-categories"><li class="cat-item cat-item-648"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/audit-analytics/">Audit & Analytics</a></li>
<li class="cat-item cat-item-598"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/design/banners/">Banners</a></li>
<li class="cat-item cat-item-652"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/content-marketing/blog-post-writing/">Blog - Post Writing</a></li>
<li class="cat-item cat-item-665"><a href="https://www.lowcostwebagency.com/low-cost/printing/brochure/">Brochure</a></li>
<li class="cat-item cat-item-667"><a href="https://www.lowcostwebagency.com/low-cost/printing/business-cards/">Business Cards</a></li>
<li class="cat-item cat-item-669"><a href="https://www.lowcostwebagency.com/low-cost/printing/business-stationaries/">Business Stationaries</a></li>
<li class="cat-item cat-item-674"><a href="https://www.lowcostwebagency.com/low-cost/printing/business-stationaries/certificates/">Certificates</a></li>
<li class="cat-item cat-item-622"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/website-page/coding-debugging/">Coding & Debugging</a></li>
<li class="cat-item cat-item-809"><a href="https://www.lowcostwebagency.com/low-cost/composite-products/">Composite Products</a></li>
<li class="cat-item cat-item-645"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/content-marketing/">Content Marketing</a></li>
<li class="cat-item cat-item-621"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/website-page/crm/">CRM</a></li>
<li class="cat-item cat-item-664"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/sem/custom-plan/">Custom Plan</a></li>
<li class="cat-item cat-item-589"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/design/">Design</a></li>
<li class="cat-item cat-item-611"><a href="https://www.lowcostwebagency.com/low-cost/digital-signature-2/">Digital Signature</a></li>
<li class="cat-item cat-item-582"><a href="https://www.lowcostwebagency.com/low-cost/hosting-and-domain/domains/">Domains</a></li>
<li class="cat-item cat-item-620"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/website-page/ecommerce-website/">Ecommerce Website</a></li>
<li class="cat-item cat-item-646"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/email-marketing/">Email Marketing</a></li>
<li class="cat-item cat-item-670"><a href="https://www.lowcostwebagency.com/low-cost/printing/business-stationaries/envelopes/">Envelopes</a></li>
<li class="cat-item cat-item-662"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/sem/fb-campaign/">Facebook Campaign</a></li>
<li class="cat-item cat-item-666"><a href="https://www.lowcostwebagency.com/low-cost/printing/flyers-leaflets/">Flyers / Leaflets</a></li>
<li class="cat-item cat-item-661"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/sem/google-adwords-campaign/">Google Adwords Campaign</a></li>
<li class="cat-item cat-item-657"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/audit-analytics/google-analytics/">Google Analytics</a></li>
<li class="cat-item cat-item-581"><a href="https://www.lowcostwebagency.com/low-cost/hosting-and-domain/hosting/">Hosting</a></li>
<li class="cat-item cat-item-578"><a href="https://www.lowcostwebagency.com/low-cost/hosting-and-domain/">Hosting & Domains</a></li>
<li class="cat-item cat-item-618"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/website-page/html-static-design/">HTML & Static Design</a></li>
<li class="cat-item cat-item-602"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/design/images-edition/">Images & Docs Edition</a></li>
<li class="cat-item cat-item-673"><a href="https://www.lowcostwebagency.com/low-cost/printing/business-stationaries/invoices/">Invoices</a></li>
<li class="cat-item cat-item-659"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/audit-analytics/keywords-research/">Keywords Research</a></li>
<li class="cat-item cat-item-671"><a href="https://www.lowcostwebagency.com/low-cost/printing/business-stationaries/letterheads/">Letterheads</a></li>
<li class="cat-item cat-item-663"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/sem/linkedin-campaign/">LinkedIn Campaign</a></li>
<li class="cat-item cat-item-593"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/design/logo-design/">Logo Design</a></li>
<li class="cat-item cat-item-668"><a href="https://www.lowcostwebagency.com/low-cost/printing/poster/">Poster</a></li>
<li class="cat-item cat-item-653"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/content-marketing/press-release/">Press Release</a></li>
<li class="cat-item cat-item-579"><a href="https://www.lowcostwebagency.com/low-cost/printing/">Printing</a></li>
<li class="cat-item cat-item-654"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/content-marketing/proof-reading/">Proofreading</a></li>
<li class="cat-item cat-item-656"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/content-marketing/resume-cover-letter-bio/">Resume - Cover Letter - Linkedin Bio</a></li>
<li class="cat-item cat-item-583"><a href="https://www.lowcostwebagency.com/low-cost/security/">Security</a></li>
<li class="cat-item cat-item-584"><a href="https://www.lowcostwebagency.com/low-cost/security/security-monitor-malware-removal/">Security Monitor & Malware Removal</a></li>
<li class="cat-item cat-item-649"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/sem/">SEM</a></li>
<li class="cat-item cat-item-658"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/audit-analytics/seo-audit/">SEO Audit</a></li>
<li class="cat-item cat-item-604"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/design/slideshow-design/">Slideshow Design</a></li>
<li class="cat-item cat-item-650"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/social-media-marketing/social-media-account-management/">Social Media Account Management</a></li>
<li class="cat-item cat-item-644"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/social-media-marketing/">Social Media Marketing</a></li>
<li class="cat-item cat-item-651"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/social-media-marketing/social-media-promotion/">Social Media Promotion</a></li>
<li class="cat-item cat-item-655"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/content-marketing/translation/">Translation</a></li>
<li class="cat-item cat-item-1193"><a href="https://www.lowcostwebagency.com/low-cost/uncategorized/">Uncategorized</a></li>
<li class="cat-item cat-item-605"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/design/video-edition/">Video Edition</a></li>
<li class="cat-item cat-item-567"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/">Web Design</a></li>
<li class="cat-item cat-item-576"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/">Web Marketing</a></li>
<li class="cat-item cat-item-660"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/audit-analytics/web-marketing-strategy/">Web Marketing Strategy</a></li>
<li class="cat-item cat-item-590"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/website-page/">Website & Page</a></li>
<li class="cat-item cat-item-586"><a href="https://www.lowcostwebagency.com/low-cost/security/website-backup/">Website Backup</a></li>
<li class="cat-item cat-item-619"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/website-page/dynamic-website-cms/">Wordpress | Joomla | Drupal - CMS Website</a></li>
</ul></section><section id="text-7" class="widget widget_text"> <div class="textwidget"><div class="fusion-image-element" style="text-align:center;--awb-liftup-border-radius:0px;--awb-caption-title-font-family:var(--h2_typography-font-family);--awb-caption-title-font-weight:var(--h2_typography-font-weight);--awb-caption-title-font-style:var(--h2_typography-font-style);--awb-caption-title-size:var(--h2_typography-font-size);--awb-caption-title-transform:var(--h2_typography-text-transform);--awb-caption-title-line-height:var(--h2_typography-line-height);--awb-caption-title-letter-spacing:var(--h2_typography-letter-spacing);"><div class="awb-image-frame awb-image-frame-1 imageframe-liftup"><span class="fusion-imageframe imageframe-none imageframe-1"><a class="fusion-no-lightbox" href="http://avada.theme-fusion.com/classic-shop/women/" target="_self"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" decoding="async" data-src="http://avada.theme-fusion.com/classic-shop/wp-content/uploads/sites/48/2015/12/promotion_women_img.jpg" alt class="img-responsive"/></a></span></div></div></div>
</section> </div>
</aside>
</div> <!-- fusion-row -->
</main> <!-- #main -->
<div class="fusion-footer">
<footer class="fusion-footer-widget-area fusion-widget-area">
<div class="fusion-row">
<div class="fusion-columns fusion-columns-5 fusion-widget-area">
<div class="fusion-column col-lg-2 col-md-2 col-sm-2">
<section id="pyre_tabs-widget-2" class="fusion-footer-widget-column widget fusion-tabs-widget" style="border-style: solid;border-color:transparent;border-width:0px;"> <div class="fusion-tabs-widget-wrapper fusion-tabs-widget-2 fusion-tabs-clean fusion-tabs-image-circle tab-holder">
<nav class="fusion-tabs-nav">
<ul class="tabset tabs">
<li class="active"><a href="#" data-link="fusion-tab-popular">Popular</a></li>
<li><a href="#" data-link="fusion-tab-recent">Recent</a></li>
</ul>
</nav>
<div class="fusion-tabs-widget-content tab-box tabs-container">
<div class="fusion-tab-popular fusion-tab-content tab tab_content" data-name="fusion-tab-popular">
<ul class="fusion-tabs-widget-items news-list">
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/10-popular-wordpress-themes/" aria-label="10 Popular WordPress Themes"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2025/01/10-popular-theme-wordpress-2-66x66.webp" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="10 popular wordpress themes" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2025/01/10-popular-theme-wordpress-2-66x66.webp 66w, https://www.lowcostwebagency.com/wp-content/uploads/2025/01/10-popular-theme-wordpress-2-100x100.webp 100w, https://www.lowcostwebagency.com/wp-content/uploads/2025/01/10-popular-theme-wordpress-2-150x150.webp 150w" data-sizes="(max-width: 66px) 100vw, 66px" title="10 Popular WordPress Themes"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/10-popular-wordpress-themes/">10 Popular WordPress Themes</a>
<div class="fusion-meta">
January 2nd, 2025 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/wpml-for-mutilingual-websites/" aria-label="Does WPML is the best WordPress plugin for multilingual websites?"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2022/06/WPML-Image-Redesign1200-600-66x66.png" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="WPML Image Redesign lcwa" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2022/06/WPML-Image-Redesign1200-600-66x66.png 66w, https://www.lowcostwebagency.com/wp-content/uploads/2022/06/WPML-Image-Redesign1200-600-100x100.png 100w, https://www.lowcostwebagency.com/wp-content/uploads/2022/06/WPML-Image-Redesign1200-600-150x150.png 150w" data-sizes="(max-width: 66px) 100vw, 66px" title="Does WPML is the best WordPress plugin for multilingual websites?"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/wpml-for-mutilingual-websites/">Does WPML is the best WordPress plugin for multilingual websites?</a>
<div class="fusion-meta">
July 27th, 2025 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/23-powerful-seo-tools-small-medium-businesses/" aria-label="23 powerful SEO tools for small and medium businesses"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2022/11/Best-SEO-plugins-for-WP-66x66.png" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="Best SEO plugins for WP" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2022/11/Best-SEO-plugins-for-WP-66x66.png 66w, https://www.lowcostwebagency.com/wp-content/uploads/2022/11/Best-SEO-plugins-for-WP-100x100.webp 100w, https://www.lowcostwebagency.com/wp-content/uploads/2022/11/Best-SEO-plugins-for-WP-150x150.png 150w" data-sizes="(max-width: 66px) 100vw, 66px" title="23 powerful SEO tools for small and medium businesses"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/23-powerful-seo-tools-small-medium-businesses/">23 powerful SEO tools for small and medium businesses</a>
<div class="fusion-meta">
February 18th, 2025 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/5-best-wordpress-themes-from-themeforest/" aria-label="5 best WordPress themes from ThemeForest"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2022/12/Best-WP-theme-66x66.png" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="Best WordPress themes from themeforest" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2022/12/Best-WP-theme-66x66.png 66w, https://www.lowcostwebagency.com/wp-content/uploads/2022/12/Best-WP-theme-100x100.webp 100w, https://www.lowcostwebagency.com/wp-content/uploads/2022/12/Best-WP-theme-150x150.png 150w" data-sizes="(max-width: 66px) 100vw, 66px" title="5 best WordPress themes from ThemeForest"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/5-best-wordpress-themes-from-themeforest/">5 best WordPress themes from ThemeForest</a>
<div class="fusion-meta">
April 15th, 2025 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/rank-math-or-yoast-seo/" aria-label="Rank Math or Yoast SEO? Which WordPress plugin for the SEO of your website?"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2022/05/Image-Rank-Math-ou-Yoast-SEO-Quel-plugin-Worpress-choisir-pour-le-SEO-de-votre-site-Web-2-66x66.png" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="Rank Math or Yoast SEO Which Worpress plugin to choose for your website SEO" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2022/05/Image-Rank-Math-ou-Yoast-SEO-Quel-plugin-Worpress-choisir-pour-le-SEO-de-votre-site-Web-2-66x66.png 66w, https://www.lowcostwebagency.com/wp-content/uploads/2022/05/Image-Rank-Math-ou-Yoast-SEO-Quel-plugin-Worpress-choisir-pour-le-SEO-de-votre-site-Web-2-100x100.webp 100w, https://www.lowcostwebagency.com/wp-content/uploads/2022/05/Image-Rank-Math-ou-Yoast-SEO-Quel-plugin-Worpress-choisir-pour-le-SEO-de-votre-site-Web-2-150x150.png 150w, https://www.lowcostwebagency.com/wp-content/uploads/2022/05/Image-Rank-Math-ou-Yoast-SEO-Quel-plugin-Worpress-choisir-pour-le-SEO-de-votre-site-Web-2-200x200.png 200w" data-sizes="(max-width: 66px) 100vw, 66px" title="Rank Math or Yoast SEO? Which Wordpress plugin for the SEO of your website?"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/rank-math-or-yoast-seo/">Rank Math or Yoast SEO? Which WordPress plugin for the SEO of your website?</a>
<div class="fusion-meta">
October 15th, 2024 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/shortage-of-it-profiles-ukraine-and-russia/" aria-label="Shortage of IT profiles | War between Ukraine and Russia | Low Cost Web Agency helps you!"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2022/04/shortage-contact-us-low-cost-web-agency-66x66.png" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="shortage contact us" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2022/04/shortage-contact-us-low-cost-web-agency-66x66.png 66w, https://www.lowcostwebagency.com/wp-content/uploads/2022/04/shortage-contact-us-low-cost-web-agency-100x100.png 100w, https://www.lowcostwebagency.com/wp-content/uploads/2022/04/shortage-contact-us-low-cost-web-agency-150x150.png 150w" data-sizes="(max-width: 66px) 100vw, 66px" title="Shortage of IT profiles | War between Ukraine and Russia | Low Cost Web Agency helps you!"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/shortage-of-it-profiles-ukraine-and-russia/">Shortage of IT profiles | War between Ukraine and Russia | Low Cost Web Agency helps you!</a>
<div class="fusion-meta">
April 9th, 2025 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/why-your-business-needs-a-website/" aria-label="Why do you need a website for your business?"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2025/06/why-your-business-needs-a-website-2026-66x66.webp" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="A futuristic holographic display showing AI and business growth, illustrating why your business needs a website in 2026." decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2025/06/why-your-business-needs-a-website-2026-66x66.webp 66w, https://www.lowcostwebagency.com/wp-content/uploads/2025/06/why-your-business-needs-a-website-2026-scaled-100x100.webp 100w, https://www.lowcostwebagency.com/wp-content/uploads/2025/06/why-your-business-needs-a-website-2026-150x150.webp 150w" data-sizes="(max-width: 66px) 100vw, 66px" title="Why do you need a website for your business?"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/why-your-business-needs-a-website/">Why do you need a website for your business?</a>
<div class="fusion-meta">
June 22nd, 2025 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/seo-tips-for-google/" aria-label="Seo tips for Google"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2017/12/Google-SEO-700x441-1-66x66.jpg" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="Google Seo" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2017/12/Google-SEO-700x441-1-66x66.jpg 66w, https://www.lowcostwebagency.com/wp-content/uploads/2017/12/Google-SEO-700x441-1-100x100.jpg 100w, https://www.lowcostwebagency.com/wp-content/uploads/2017/12/Google-SEO-700x441-1-150x150.jpg 150w" data-sizes="(max-width: 66px) 100vw, 66px" title="Seo tips for Google"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/seo-tips-for-google/">Seo tips for Google</a>
<div class="fusion-meta">
February 13th, 2025 </div>
</div>
</li>
</ul>
</div>
<div class="fusion-tab-recent fusion-tab-content tab tab_content" data-name="fusion-tab-recent" style="display: none;">
<ul class="fusion-tabs-widget-items news-list">
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/ai-writing-instantly-boost-your/" aria-label="Ai-powered content magic: instantly boost your website’s visibility with automated copywriting wizards"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-content-magic-instantly-boost-66x66.webp" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="AI-driven copywriter wizard increases site visibility rapidly" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-content-magic-instantly-boost-66x66.webp 66w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-content-magic-instantly-boost-150x150.webp 150w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-content-magic-instantly-boost-200x200.webp 200w" data-sizes="(max-width: 66px) 100vw, 66px" title="Ai-powered content magic: instantly boost your website's visibility with automated copywriting wizards"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/ai-writing-instantly-boost-your/">Ai-powered content magic: instantly boost your website’s visibility with automated copywriting wizards</a>
<div class="fusion-meta">
October 11th, 2026 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/ai-crafted-meta-descriptions-for-instant/" aria-label="Ai-crafted meta descriptors: the secret sauce for instant visibility boost"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-meta-descriptors-the-secret-66x66.webp" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="AI-generated metadata for enhanced online visibility" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-meta-descriptors-the-secret-66x66.webp 66w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-meta-descriptors-the-secret-100x100.webp 100w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-meta-descriptors-the-secret-150x150.webp 150w" data-sizes="(max-width: 66px) 100vw, 66px" title="Ai-crafted meta descriptors: the secret sauce for instant visibility boost"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/ai-crafted-meta-descriptions-for-instant/">Ai-crafted meta descriptors: the secret sauce for instant visibility boost</a>
<div class="fusion-meta">
October 10th, 2026 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/ai-content-mastery-future-of-seo/" aria-label="Ai-crafted content: the future of seo and web design mastery"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-content-the-future-of-66x66.webp" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="AI-generated content for SEO and web design success" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-content-the-future-of-66x66.webp 66w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-content-the-future-of-150x150.webp 150w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aicrafted-content-the-future-of-200x200.webp 200w" data-sizes="(max-width: 66px) 100vw, 66px" title="Ai-crafted content: the future of seo and web design mastery"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/ai-content-mastery-future-of-seo/">Ai-crafted content: the future of seo and web design mastery</a>
<div class="fusion-meta">
October 9th, 2026 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/ai-design-smart-layouts-that/" aria-label="Revolutionizing web design: ai-powered layouts that convert visits into sales"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-web-design-aipowered-layouts-66x66.webp" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="AI-driven web layouts increasing conversions and sales" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-web-design-aipowered-layouts-66x66.webp 66w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-web-design-aipowered-layouts-150x150.webp 150w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-web-design-aipowered-layouts-200x200.webp 200w" data-sizes="(max-width: 66px) 100vw, 66px" title="Revolutionizing web design: ai-powered layouts that convert visits into sales"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/ai-design-smart-layouts-that/">Revolutionizing web design: ai-powered layouts that convert visits into sales</a>
<div class="fusion-meta">
October 9th, 2026 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/revolutionize-your-website-with-ai/" aria-label="Revolutionizing your website with ai-powered content optimization techniques"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-your-website-with-aipowered-content-optimization-techniques-66x66.webp" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="AI-driven content优化提升网站效率示意图" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-your-website-with-aipowered-content-optimization-techniques-66x66.webp 66w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-your-website-with-aipowered-content-optimization-techniques-100x100.webp 100w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/revolutionizing-your-website-with-aipowered-content-optimization-techniques-150x150.webp 150w" data-sizes="(max-width: 66px) 100vw, 66px" title="Revolutionizing your website with ai-powered content optimization techniques"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/revolutionize-your-website-with-ai/">Revolutionizing your website with ai-powered content optimization techniques</a>
<div class="fusion-meta">
October 9th, 2026 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/aipowered-seo-automating-keyword-optimization-for-maximum-visibility/" aria-label="Ai-powered seo: automating keyword optimization for maximum visibility"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-seo-automating-keyword-optimization-for-maximum-visibility-66x66.webp" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="AI-driven SEO tool optimizing keywords for better visibility" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-seo-automating-keyword-optimization-for-maximum-visibility-66x66.webp 66w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-seo-automating-keyword-optimization-for-maximum-visibility-150x150.webp 150w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/aipowered-seo-automating-keyword-optimization-for-maximum-visibility-200x200.webp 200w" data-sizes="(max-width: 66px) 100vw, 66px" title="Ai-powered seo: automating keyword optimization for maximum visibility"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/aipowered-seo-automating-keyword-optimization-for-maximum-visibility/">Ai-powered seo: automating keyword optimization for maximum visibility</a>
<div class="fusion-meta">
October 8th, 2026 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/how-ai-is-transforming-content/" aria-label="How AI is transforming content creation across industries"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/how-ai-is-transforming-content-creation-across-industries-66x66.webp" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="AI-driven content creation across industries illustrated" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/how-ai-is-transforming-content-creation-across-industries-66x66.webp 66w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/how-ai-is-transforming-content-creation-across-industries-150x150.webp 150w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/how-ai-is-transforming-content-creation-across-industries-200x200.webp 200w" data-sizes="(max-width: 66px) 100vw, 66px" title="How AI is transforming content creation across industries"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/how-ai-is-transforming-content/">How AI is transforming content creation across industries</a>
<div class="fusion-meta">
October 8th, 2026 </div>
</div>
</li>
<li>
<div class="image">
<a href="https://www.lowcostwebagency.com/new-bmw-ix5-electric-tech/" aria-label="Bmw’s new ix5 puts electric driving at the forefront against chinese rivals"><img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" width="66" height="66" data-src="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/bmws-new-ix5-puts-electric-driving-at-the-forefront-against-chinese-rivals-66x66.webp" class="attachment-recent-works-thumbnail size-recent-works-thumbnail wp-post-image" alt="BMW ix5 electric vehicle technology comparison" decoding="async" data-srcset="https://www.lowcostwebagency.com/wp-content/uploads/2026/10/bmws-new-ix5-puts-electric-driving-at-the-forefront-against-chinese-rivals-66x66.webp 66w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/bmws-new-ix5-puts-electric-driving-at-the-forefront-against-chinese-rivals-100x100.webp 100w, https://www.lowcostwebagency.com/wp-content/uploads/2026/10/bmws-new-ix5-puts-electric-driving-at-the-forefront-against-chinese-rivals-150x150.webp 150w" data-sizes="(max-width: 66px) 100vw, 66px" title="Bmw’s new ix5 puts electric driving at the forefront against chinese rivals"></a>
</div>
<div class="post-holder">
<a href="https://www.lowcostwebagency.com/new-bmw-ix5-electric-tech/">Bmw’s new ix5 puts electric driving at the forefront against chinese rivals</a>
<div class="fusion-meta">
October 8th, 2026 </div>
</div>
</li>
</ul>
</div>
</div>
</div>
<div style="clear:both;"></div></section> </div>
<div class="fusion-column col-lg-2 col-md-2 col-sm-2">
<section id="nav_menu-2" class="fusion-footer-widget-column widget widget_nav_menu" style="border-style: solid;border-color:transparent;border-width:0px;"><h4 class="widget-title">BUY ONLINE</h4><div class="menu-seo-menu-container"><ul id="menu-seo-menu" class="menu"><li id="menu-item-29890" class="menu-item menu-item-type-taxonomy menu-item-object-product_cat menu-item-29890"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/website-page/" title="Explore our Website Design, Ecommerce, and Blog creation services">Website Design | Ecommerce | Blog…</a></li>
<li id="menu-item-29891" class="menu-item menu-item-type-taxonomy menu-item-object-product_cat menu-item-29891"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/design/" title="Discover our Visual Design services for Logos, Banners, and more">Visual Design | Logo | Banners…</a></li>
<li id="menu-item-29892" class="menu-item menu-item-type-taxonomy menu-item-object-product_cat menu-item-29892"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/" title="Boost your visibility with our Web Marketing, SEO, and Advertising solutions">Web Marketing | SEO | Advertisement</a></li>
<li id="menu-item-29894" class="menu-item menu-item-type-taxonomy menu-item-object-product_cat menu-item-29894"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/content-marketing/" title="Professional Content Writing, Translations, Press Releases, and CV services">Post Writings | Translations | Press Releases | Cv/Bio</a></li>
<li id="menu-item-29903" class="menu-item menu-item-type-taxonomy menu-item-object-product_cat menu-item-29903"><a href="https://www.lowcostwebagency.com/low-cost/security/" title="Protect your online business with our expert Website Security solutions">Website Security</a></li>
<li id="menu-item-43732" class="menu-item menu-item-type-taxonomy menu-item-object-product_cat menu-item-43732"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/audit-analytics/web-marketing-strategy/" title="Develop a winning Web Marketing Strategy to grow your brand">Web Marketing Strategy</a></li>
<li id="menu-item-43734" class="menu-item menu-item-type-taxonomy menu-item-object-product_cat menu-item-43734"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/email-marketing/" title="Engage your audience with effective Email Marketing campaigns">Email Marketing</a></li>
<li id="menu-item-43735" class="menu-item menu-item-type-taxonomy menu-item-object-product_cat menu-item-43735"><a href="https://www.lowcostwebagency.com/low-cost/web-marketing/social-media-marketing/" title="Grow your online community with our Social Media Marketing services">Social Media Marketing</a></li>
<li id="menu-item-43736" class="menu-item menu-item-type-taxonomy menu-item-object-product_cat menu-item-43736"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/website-page/coding-debugging/" title="Expert Coding and Debugging services to keep your website running smoothly">Coding & Debugging</a></li>
<li id="menu-item-43737" class="menu-item menu-item-type-taxonomy menu-item-object-product_cat menu-item-43737"><a href="https://www.lowcostwebagency.com/low-cost/webdesign/website-page/ecommerce-website/" title="Build a high-performing Ecommerce Website for your online store">Ecommerce Website</a></li>
</ul></div><div style="clear:both;"></div></section> </div>
<div class="fusion-column col-lg-2 col-md-2 col-sm-2">
<section id="nav_menu-3" class="fusion-footer-widget-column widget widget_nav_menu"><h4 class="widget-title">CHECK OUR DIFFERENCE</h4><div class="menu-check-our-difference-container"><ul id="menu-check-our-difference" class="menu"><li id="menu-item-29898" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-29898"><a href="https://www.lowcostwebagency.com/faqs/behind-low-cost-web-agency/">Who is Low Cost Web Agency?</a></li>
<li id="menu-item-29899" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-29899"><a href="https://www.lowcostwebagency.com/faqs/best-price-guarantee-really-works/">Best Price Guarantee</a></li>
<li id="menu-item-29900" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-29900"><a href="https://www.lowcostwebagency.com/faqs/may-know-included-lifetime-guarantee/">Lifetime Guarantee for Website design</a></li>
<li id="menu-item-29901" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-29901"><a href="https://www.lowcostwebagency.com/faqs/prices-includes-taxes-hidden-fees/">No hidden fees</a></li>
<li id="menu-item-29902" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-29902"><a href="https://www.lowcostwebagency.com/faqs/will-finished-product/">You have the Full ownership</a></li>
<li id="menu-item-30385" class="menu-item menu-item-type-post_type menu-item-object-page menu-item-30385"><a href="https://www.lowcostwebagency.com/portfolio/">Portfolio & Testimonials</a></li>
<li id="menu-item-43772" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-43772"><a href="https://www.lowcostwebagency.com/faqs/can-see-example-website-templates/">Can I see example of website templates?</a></li>
<li id="menu-item-43773" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-43773"><a href="https://www.lowcostwebagency.com/faqs/wordpress-vs-joomla-vs-drupal-which-cms-better/">WordPress Vs. Joomla Vs. Drupal? Which CMS is better?</a></li>
<li id="menu-item-43774" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-43774"><a href="https://www.lowcostwebagency.com/faqs/best-price-guarantee-really-works/">Best Price Guarantee… Really? How it works?</a></li>
<li id="menu-item-43775" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-43775"><a href="https://www.lowcostwebagency.com/faqs/may-know-included-lifetime-guarantee/">May I know what is included in your Lifetime Guarantee?</a></li>
</ul></div><div style="clear:both;"></div></section> </div>
<div class="fusion-column col-lg-2 col-md-2 col-sm-2">
<section id="nav_menu-4" class="fusion-footer-widget-column widget widget_nav_menu"><h4 class="widget-title">INFORMATIONS / FAQS</h4><div class="menu-info-menu-container"><ul id="menu-info-menu" class="menu"><li id="menu-item-29907" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-29907"><a href="https://www.lowcostwebagency.com/faqs/terms-conditions/">Our Terms & Conditions</a></li>
<li id="menu-item-29909" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-29909"><a href="https://www.lowcostwebagency.com/faqs/how-and-when-i-pay-for-your-services/">Payment Terms</a></li>
<li id="menu-item-32430" class="menu-item menu-item-type-post_type menu-item-object-page menu-item-32430"><a href="https://www.lowcostwebagency.com/terms-use/">Terms of Use</a></li>
<li id="menu-item-29911" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-29911"><a href="https://www.lowcostwebagency.com/faqs/fair-use-policy-hosting-services/">Hosting fair use policy</a></li>
<li id="menu-item-43776" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-43776"><a href="https://www.lowcostwebagency.com/faqs/use-premium-templates/">Do you use Premium Templates?</a></li>
<li id="menu-item-43777" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-43777"><a href="https://www.lowcostwebagency.com/faqs/much-content-will-add-website-articles-post-products-pictures/">How much content you will add in my website? Articles, Post, Products, Pictures?</a></li>
<li id="menu-item-43779" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-43779"><a href="https://www.lowcostwebagency.com/faqs/dedicated-ip-need/">What is a Dedicated IP? Do I need it?</a></li>
<li id="menu-item-43780" class="menu-item menu-item-type-post_type menu-item-object-ufaq menu-item-43780"><a href="https://www.lowcostwebagency.com/faqs/kind-assistance-maintenance-guarantee-give-hosting-services/">What kind of assistance, maintenance and guarantee you give with your hosting services?</a></li>
<li id="menu-item-29912" class="menu-item menu-item-type-post_type menu-item-object-page menu-item-29912"><a href="https://www.lowcostwebagency.com/contact-us/">Contact us</a></li>
</ul></div><div style="clear:both;"></div></section> </div>
<div class="fusion-column fusion-column-last col-lg-2 col-md-2 col-sm-2">
<section id="custom_html-3" class="widget_text fusion-footer-widget-column widget widget_custom_html" style="border-style: solid;border-color:transparent;border-width:0px;"><h4 class="widget-title">GET A FREE QUOTE WITHIN 24H</h4><div class="textwidget custom-html-widget"><div class="footer-form-intro" style="margin-bottom:20px;font-size:14px;line-height:1.6;color:#dddddd;">
<p>Ready to elevate your digital presence? Share your project details below. Our team combines high-quality web solutions with smart pricing to help your business grow. We will get back to you within 24 hours.</p>
<p style="margin-top:10px;font-size:13px;">
<span style="color:#aaaaaa;">Urgent inquiry?</span>
<a href="https://wa.me/919786495150?text=Hello%20Alex,%20I%20would%20like%20to%20discuss%20a%20project..." target="_blank" rel="noopener noreferrer" style="color:#25D366;font-weight:bold;text-decoration:none;margin-left:5px;">
Message us on WhatsApp
</a>
</p>
</div>
<div class="wpcf7 no-js" id="wpcf7-f49833-o1" lang="en-US" dir="ltr" data-wpcf7-id="49833">
<div class="screen-reader-response"><p role="status" aria-live="polite" aria-atomic="true"></p> <ul></ul></div>
<form action="/ai-content-mastery-future-of-seo/#wpcf7-f49833-o1" method="post" class="wpcf7-form init" aria-label="Contact form" novalidate="novalidate" data-status="init">
<fieldset class="hidden-fields-container"><input type="hidden" name="_wpcf7" value="49833" /><input type="hidden" name="_wpcf7_version" value="6.1.7" /><input type="hidden" name="_wpcf7_locale" value="en_US" /><input type="hidden" name="_wpcf7_unit_tag" value="wpcf7-f49833-o1" /><input type="hidden" name="_wpcf7_container_post" value="0" /><input type="hidden" name="_wpcf7_posted_data_hash" value="" /><input type="hidden" name="_wpcf7cf_hidden_group_fields" value="[]" /><input type="hidden" name="_wpcf7cf_hidden_groups" value="[]" /><input type="hidden" name="_wpcf7cf_visible_groups" value="[]" /><input type="hidden" name="_wpcf7cf_repeaters" value="[]" /><input type="hidden" name="_wpcf7cf_steps" value="{}" /><input type="hidden" name="_wpcf7cf_options" value="{"form_id":49833,"conditions":[],"settings":{"animation":"yes","animation_intime":200,"animation_outtime":200,"conditions_ui":"normal","notice_dismissed":false,"repeater_remove_button":"bottom","notice_dismissed_rollback-cf7-5.8.1":true,"notice_dismissed_update-cf7-6.2":true}}" />
</fieldset>
<div class="wpcf7-turnstile cf-turnstile" data-sitekey="0x4AAAAAADHHp2OLRckyMy7w" data-response-field-name="_wpcf7_turnstile_response"></div>
<div class="footer-contact-form">
<p><span class="wpcf7-form-control-wrap" data-name="your-name"><input size="40" maxlength="400" class="wpcf7-form-control wpcf7-text wpcf7-validates-as-required" aria-required="true" aria-invalid="false" placeholder="*Full Name" value="" type="text" name="your-name" /></span><br />
<span class="wpcf7-form-control-wrap" data-name="your-email"><input size="40" maxlength="400" class="wpcf7-form-control wpcf7-email wpcf7-validates-as-required wpcf7-text wpcf7-validates-as-email" aria-required="true" aria-invalid="false" placeholder="*Email Address" value="" type="email" name="your-email" /></span><br />
<span class="wpcf7-form-control-wrap" data-name="tel-837"><input size="40" maxlength="400" class="wpcf7-form-control wpcf7-tel wpcf7-validates-as-required wpcf7-text wpcf7-validates-as-tel" aria-required="true" aria-invalid="false" placeholder="*Phone (ex: +33 6... / +91...)" value="" type="tel" name="tel-837" /></span><br />
<span class="wpcf7-form-control-wrap" data-name="your-message"><textarea cols="40" rows="2" maxlength="2000" class="wpcf7-form-control wpcf7-textarea" aria-invalid="false" placeholder="Your Project Details..." name="your-message"></textarea></span><br />
<div class="cf7-cf-turnstile" style="margin-top: 0px; margin-bottom: -15px;"> <div id="cf-turnstile-cf7-1037331612" class="cf-turnstile" data-sitekey="0x4AAAAAADHHp2OLRckyMy7w" data-theme="auto" data-language="auto" data-size="flexible" data-retry="auto" data-retry-interval="1000" data-refresh-expired="auto" data-refresh-timeout="auto" data-action="contact-form-7" data-callback="turnstileCF7Callback" data-appearance="always"></div> <style>.wpcf7-submit { pointer-events: none; opacity: 0.5; }</style> <br class="cf-turnstile-br cf-turnstile-br-cf7-1037331612"> </div><br/><input class="wpcf7-form-control wpcf7-submit has-spinner" type="submit" value="Get a Quote" />
</p>
</div><p style="display: none !important;" class="akismet-fields-container" data-prefix="_wpcf7_ak_"><label>Δ<textarea name="_wpcf7_ak_hp_textarea" cols="45" rows="8" maxlength="100"></textarea></label><input type="hidden" id="ak_js_1" name="_wpcf7_ak_js" value="92"/><script src="data:text/javascript;base64,ZG9jdW1lbnQuZ2V0RWxlbWVudEJ5SWQoImFrX2pzXzEiKS5zZXRBdHRyaWJ1dGUoInZhbHVlIiwobmV3IERhdGUoKSkuZ2V0VGltZSgpKQ==" defer></script>
</p><div class="fusion-alert alert custom alert-custom fusion-alert-center wpcf7-response-output awb-alert-native-link-color alert-dismissable awb-alert-close-boxed" style="--awb-border-size:1px;--awb-border-top-left-radius:0px;--awb-border-top-right-radius:0px;--awb-border-bottom-left-radius:0px;--awb-border-bottom-right-radius:0px;" role="alert"><div class="fusion-alert-content-wrapper"><span class="fusion-alert-content"></span></div><button type="button" class="close toggle-alert" data-dismiss="alert" aria-label="Close">×</button></div>
</form>
</div>
</div><div style="clear:both;"></div></section> </div>
<div class="fusion-clearfix"></div>
</div> <!-- fusion-columns -->
</div> <!-- fusion-row -->
</footer> <!-- fusion-footer-widget-area -->
<footer id="footer" class="fusion-footer-copyright-area fusion-footer-copyright-center">
<div class="fusion-row">
<div class="fusion-copyright-content">
<div class="fusion-copyright-notice">
<div>
We accept all major credit cards : <img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" data-src="/wp-content/uploads/2017/09/paypal_accept.png" width="271" height="27" />
<div style="margin-top: 1%;">
<a href='https://www.lowcostwebagency.com' target='_blank'>
<img data-lazyloaded="1" src="data:image/gif;base64,R0lGODlhAQABAIAAAAAAAP///yH5BAEAAAAALAAAAAABAAEAAAIBRAA7" data-src="/wp-content/uploads/2016/10/footerlcwalogo.png" style="width: 17px;" width="22" height="25" /> Low Cost Web Agency Pvt. Ltd.
</a>
© Copyright 2026 | All Rights Reserved |
<a href="/terms-use" target="_blank">Terms of Use | </a>
<a href=' https://www.icann.org/en/registrars/registrantrights-responsibilities-en.htm ' target='_blank'> ICANN ➔
<a href=' https://www.icann.org/resources/pages/benefits-2013-09-16-en ' target='_blank'> Terms
</div> </div>
</div>
<div class="fusion-social-links-footer">
<div class="fusion-social-networks"><div class="fusion-social-networks-wrapper"><a class="fusion-social-network-icon fusion-tooltip fusion-facebook awb-icon-facebook" style data-placement="top" data-title="Facebook" data-toggle="tooltip" title="Facebook" href="https://www.facebook.com/lowcostwebagency" target="_blank" rel="noreferrer nofollow"><span class="screen-reader-text">Facebook</span></a><a class="fusion-social-network-icon fusion-tooltip fusion-linkedin awb-icon-linkedin" style data-placement="top" data-title="LinkedIn" data-toggle="tooltip" title="LinkedIn" href="http://www.linkedin.com/company/low-cost-web-agency-ltd-" target="_blank" rel="noopener noreferrer nofollow"><span class="screen-reader-text">LinkedIn</span></a><a class="fusion-social-network-icon fusion-tooltip fusion-twitter awb-icon-twitter" style data-placement="top" data-title="X" data-toggle="tooltip" title="X" href="https://twitter.com/LOWCOSTCONCEPT" target="_blank" rel="noopener noreferrer nofollow"><span class="screen-reader-text">X</span></a><a class="fusion-social-network-icon fusion-tooltip fusion-youtube awb-icon-youtube" style data-placement="top" data-title="YouTube" data-toggle="tooltip" title="YouTube" href="https://www.youtube.com/user/easyrome73" target="_blank" rel="noopener noreferrer nofollow"><span class="screen-reader-text">YouTube</span></a></div></div></div>
</div> <!-- fusion-fusion-copyright-content -->
</div> <!-- fusion-row -->
</footer> <!-- #footer -->
</div> <!-- fusion-footer -->
</div> <!-- wrapper -->
</div> <!-- #boxed-wrapper -->
<a class="fusion-one-page-text-link fusion-page-load-link" tabindex="-1" href="#" aria-hidden="true">Page load link</a>
<div class="avada-footer-scripts">
<script type="speculationrules">
{"prefetch":[{"source":"document","where":{"and":[{"href_matches":"/*"},{"not":{"href_matches":["/wp-*.php","/wp-admin/*","/wp-content/uploads/*","/wp-content/*","/wp-content/plugins/*","/wp-content/themes/Avada-Child-Theme/*","/wp-content/themes/Avada/*","/*\\?(.+)"]}},{"not":{"selector_matches":"a[rel~=\"nofollow\"]"}},{"not":{"selector_matches":".no-prefetch, .no-prefetch a"}}]},"eagerness":"conservative"}]}
</script>
<script type="text/javascript" src="data:text/javascript;base64,alF1ZXJ5KGRvY3VtZW50KS5yZWFkeShmdW5jdGlvbigpe2Z1bmN0aW9uIHdjX3F2X2dldFdpZHRoKCl7eFdpZHRoPW51bGw7aWYod2luZG93LnNjcmVlbiE9bnVsbCkKeFdpZHRoPXdpbmRvdy5zY3JlZW4uYXZhaWxXaWR0aDtpZih3aW5kb3cuaW5uZXJXaWR0aCE9bnVsbCkKeFdpZHRoPXdpbmRvdy5pbm5lcldpZHRoO2lmKGRvY3VtZW50LmJvZHkhPW51bGwpCnhXaWR0aD1kb2N1bWVudC5ib2R5LmNsaWVudFdpZHRoO3JldHVybiB4V2lkdGh9CmZ1bmN0aW9uIHdjX3F2X2dldF9jdXN0b21fdGVtcGxhdGUocHJvZHVjdF9pZCxleHRyYV9wYXJhbWV0ZXJzPScnKXt2YXIgaXNfc2hvcD0nbm8nO3ZhciBpc19jYXRlZ29yeT0nbm8nO3ZhciBvcmRlcmJ5PWpRdWVyeSgnLndvb2NvbW1lcmNlLW9yZGVyaW5nJykuZmluZCgnc2VsZWN0W25hbWU9b3JkZXJieV0nKS52YWwoKTt2YXIgdXJsPScvd3AtYWRtaW4vYWRtaW4tYWpheC5waHAnKyc/YWN0aW9uPXF1aWNrX3ZpZXdfY3VzdG9tX3RlbXBsYXRlX2xvYWQmcHJvZHVjdF9pZD0nK3Byb2R1Y3RfaWQrJyZpc19zaG9wPScraXNfc2hvcCsnJmlzX2NhdGVnb3J5PScraXNfY2F0ZWdvcnkrJyZvcmRlcmJ5PScrb3JkZXJieSsnJnNlY3VyaXR5PWYwNTg2ZThhZjUnO2lmKCcnIT09ZXh0cmFfcGFyYW1ldGVycyl7dXJsKz1leHRyYV9wYXJhbWV0ZXJzfQpyZXR1cm4gdXJsfQpqUXVlcnkoZG9jdW1lbnQpLm9uKCdxdWlja192aWV3X2Nsb3NlX3BvcHVwJyxmdW5jdGlvbigpe2lmKGpRdWVyeSgnZGl2LnBwX292ZXJsYXknKS5sZW5ndGg+MCl7alF1ZXJ5LnByZXR0eVBob3RvLmNsb3NlKCl9fSk7alF1ZXJ5KCIuaW5pdF9wcmV0dHlwaG90byIpLnByZXR0eVBob3RvKHthbmltYXRpb25fc3BlZWQ6MCxzb2NpYWxfdG9vbHM6ITEsdGhlbWU6J3BwX3dvb2NvbW1lcmNlJyxob3Jpem9udGFsX3BhZGRpbmc6MjAsb3BhY2l0eTowLjgsYWpheGNhbGxiYWNrOmZ1bmN0aW9uKCl7alF1ZXJ5KGRvY3VtZW50KS5maW5kKCcucHBfY29udGVudCcpLmFwcGVuZCgnPGRpdiBjbGFzcz0icXVpY2tfdmlld19wb3B1cF9sb2FkaW5nIj48L2Rpdj4nKTtqUXVlcnkoJy5xdWlja192aWV3X3BvcHVwX2xvYWRpbmcnKS5zaG93KCk7alF1ZXJ5KCcucHBfbG9hZGVySWNvbicpLnNob3coKX0sY2hhbmdlcGljdHVyZWNhbGxiYWNrOmZ1bmN0aW9uKCl7dmFyIHBvcHVwX2NvbnRhaW5lcj1qUXVlcnkoJy5xdWlja192aWV3X3BvcHVwX2NvbnRhaW5lcicpO3ZhciBwcm9kdWN0X2lkPXBvcHVwX2NvbnRhaW5lci5kYXRhKCdwcm9kdWN0X2lkJyk7dmFyIG9yZGVyYnk9cG9wdXBfY29udGFpbmVyLmRhdGEoJ29yZGVyYnknKTt2YXIgaXNfc2hvcD1wb3B1cF9jb250YWluZXIuZGF0YSgnaXNfc2hvcCcpO3ZhciBpc19jYXRlZ29yeT1wb3B1cF9jb250YWluZXIuZGF0YSgnaXNfY2F0ZWdvcnknKTt2YXIgcXZfZGF0YT17YWN0aW9uOiJxdWlja192aWV3X3ByZXR0eXBob3RvX2N1c3RvbV90ZW1wbGF0ZV9sb2FkIixwcm9kdWN0X2lkOnByb2R1Y3RfaWQsb3JkZXJieTpvcmRlcmJ5LGlzX3Nob3A6aXNfc2hvcCxpc19jYXRlZ29yeTppc19jYXRlZ29yeSxzZWN1cml0eTonNjNlZTM1NjI0OCd9O2pRdWVyeS5wb3N0KCcvd3AtYWRtaW4vYWRtaW4tYWpheC5waHAnLHF2X2RhdGEsZnVuY3Rpb24ocmVzcG9uc3ZlKXtwb3B1cF9jb250YWluZXIuaHRtbChyZXNwb25zdmUpO2pRdWVyeSgnLnF1aWNrX3ZpZXdfcG9wdXBfbG9hZGluZycpLmhpZGUoKTtqUXVlcnkoJy5wcF9sb2FkZXJJY29uJykuaGlkZSgpfSl9fSk7alF1ZXJ5KGRvY3VtZW50KS5vbigiY2xpY2siLCIucXVpY2tfdmlld191bHRpbWF0ZV9jbGljay5wcmV0dHlwaG90byIsZnVuY3Rpb24oKXt2YXIgcHJvZHVjdF9pZD1qUXVlcnkodGhpcykuYXR0cignaWQnKTt2YXIgcHJvZHVjdF91cmw9alF1ZXJ5KHRoaXMpLmF0dHIoJ2RhdGEtbGluaycpO3ZhciB1cmw9d2NfcXZfZ2V0X2N1c3RvbV90ZW1wbGF0ZShwcm9kdWN0X2lkLCcmYWpheD10cnVlJyk7dmFyIHBvcHVwX3RhbGw9MzAwO3ZhciBwb3B1cF93aWRlPTgwMDtpZih3Y19xdl9nZXRXaWR0aCgpPD02MDApe3BvcHVwX3dpZGU9JzkwJSc7cG9wdXBfdGFsbD0nOTAlJ30KalF1ZXJ5LnByZXR0eVBob3RvLm9wZW4odXJsKycmd2lkdGg9Jytwb3B1cF93aWRlKycmaGVpZ2h0PScrcG9wdXBfdGFsbCwnJywnJyk7cmV0dXJuITF9KX0p" defer></script>
<style type="text/css">
#cboxOverlay{ background-color: #666666 !important ; }
body .pp_overlay { background-color: #666666 !important ; }
</style>
<style type="text/css">
.quick_view_ultimate_content_under{text-align:center;clear:both;display:block;width:100%;padding:10px 0px;}
.quick_view_ultimate_content_under .quick_view_ultimate_under_link{
font:bold 12px/1.4em Arial, sans-serif !important;color:#000000 !important; text-align:center !important;
}
.quick_view_ultimate_content_under .quick_view_ultimate_under_link:hover{
color:#999999 !important;
}
.quick_view_ultimate_content_under .quick_view_ultimate_under_button{
font:bold 12px/1.4em Arial, sans-serif !important;color:#FFFFFF !important; border: 1px solid #000000 !important;border-radius: 3px 3px 3px 3px !important;-moz-border-radius: 3px 3px 3px 3px !important;-webkit-border-radius: 3px 3px 3px 3px !important; text-align:center !important;
padding: 7px 8px !important;
background: #000000 !important;
background: -webkit-gradient(linear, left top, left bottom, from(#000000), to(#000000)) !important;
background: -webkit-linear-gradient(#000000, #000000) !important;
background: -moz-linear-gradient(center top, #000000 0%, #000000 100%) !important;
background: -moz-gradient(center top, #000000 0%, #000000 100%) !important;
}
</style>
<style type="text/css">
.quick_view_ultimate_container{text-align:center;clear:both;display:block;width:100%;}
.quick_view_ultimate_container span{
font:normal 14px/1.4em Arial, sans-serif !important;color:#FFFFFF !important; text-align:center !important;
padding: 7px 17px !important;
}
.product_hover .quick_view_ultimate_container span.quick_view_ultimate_button{
color:#FFFFFF;
border: 1px solid #FFFFFF !important;border-radius: 3px 3px 3px 3px !important;-moz-border-radius: 3px 3px 3px 3px !important;-webkit-border-radius: 3px 3px 3px 3px !important; background: #999999;
background: -webkit-gradient(linear, left top, left bottom, from(#999999), to(#999999));
background: -webkit-linear-gradient(#999999, #999999);
background: -moz-linear-gradient(center top, #999999 0%, #999999 100%);
background: -moz-gradient(center top, #999999 0%, #999999 100%);
box-shadow: none !important ;-moz-box-shadow: none !important ;-webkit-box-shadow: none !important ; opacity:0.5;
filter:alpha(opacity=50);
}
</style>
<span class="awb-cart-count-data" data-cart-count="0" hidden></span><span class="awb-cart-count-live screen-reader-text" role="status" aria-live="polite" aria-atomic="true" data-singular="%s item in cart" data-plural="%s items in cart"></span><div class="woocommerce-cart-tab-container woocommerce-cart-tab-container--right"> <div class="woocommerce-cart-tab woocommerce-cart-tab--empty">
<svg xmlns="http://www.w3.org/2000/svg" viewbox="0 0 86 104.5" class="woocommerce-cart-tab__icon">
<path class="woocommerce-cart-tab__icon-bag" d="M67.2,26.7C64.6,11.5,54.8,0.2,43.1,0.2C31.4,0.2,21.6,11.5,19,26.7H0.1v77.6h86V26.7H67.2z M43.1,4.2 c9.6,0,17.7,9.6,20,22.6H23C25.4,13.8,33.5,4.2,43.1,4.2z M82.1,100.4h-78V30.7h14.4c-0.1,1.3-0.2,2.6-0.2,3.9c0,1.1,0,2.2,0.1,3.3 c-0.8,0.6-1.4,1.6-1.4,2.8c0,1.9,1.6,3.5,3.5,3.5s3.5-1.6,3.5-3.5c0-1.2-0.6-2.3-1.6-2.9c-0.1-1-0.1-2-0.1-3.1 c0-1.3,0.1-2.6,0.2-3.9h41.2c0.1,1.3,0.2,2.6,0.2,3.9c0,1,0,2.1-0.1,3.1c-1,0.6-1.6,1.7-1.6,2.9c0,1.9,1.6,3.5,3.5,3.5 c1.9,0,3.5-1.6,3.5-3.5c0-1.1-0.5-2.1-1.4-2.8c0.1-1.1,0.1-2.2,0.1-3.3c0-1.3-0.1-2.6-0.2-3.9h14.4V100.4z"/>
</svg>
<span class="woocommerce-cart-tab__contents">0</span>
<script type="text/javascript" src="data:text/javascript;base64,alF1ZXJ5KCcud29vY29tbWVyY2UtY2FydC10YWInKS5jbGljayhmdW5jdGlvbigpe2pRdWVyeSgnLndvb2NvbW1lcmNlLWNhcnQtdGFiLWNvbnRhaW5lcicpLnRvZ2dsZUNsYXNzKCd3b29jb21tZXJjZS1jYXJ0LXRhYi1jb250YWluZXItLXZpc2libGUnKTtqUXVlcnkoJ2JvZHknKS50b2dnbGVDbGFzcygnd29vY29tbWVyY2UtY2FydC10YWItaXMtdmlzaWJsZScpfSk=" defer></script>
</div>
<div class="widget woocommerce widget_shopping_cart"><h2 class="widgettitle">Your Cart</h2><div class="widget_shopping_cart_content"></div></div></div><!-- PayPal Checkout: Gateway not available for block theme injection --><div class='mwai-chatbot-container' data-params='{"aiName":"AI: ","userName":"User: ","guestName":"Guest:","textSend":"Send","textClear":"Clear","imageUpload":false,"fileUpload":false,"multiUpload":false,"maxUploads":1,"fileUploads":0,"mode":"chat","textInputPlaceholder":"Type your message...","textEmptyHint":"","textInputMaxLength":512,"textCompliance":"","startSentence":"Hi! How can I help you?","localMemory":true,"themeId":"chatgpt","window":true,"icon":"","iconText":"","iconTextDelay":1,"iconTextDuration":0,"iconTextOnce":"session","iconAlt":"AI Engine Chatbot","iconPosition":"bottom-right","centerOpen":false,"width":"","openDelay":"","iconBubble":false,"windowAnimation":"zoom","fullscreen":false,"copyButton":false,"pdfButton":false,"headerSubtitle":"Discuss with","containerType":"standard","headerType":"standard","messagesType":"standard","inputType":"standard","footerType":"standard"}' data-system='{"botId":"default","customId":null,"userData":null,"sessionId":null,"restNonce":null,"contextId":50331,"pluginUrl":"https:\/\/www.lowcostwebagency.com\/wp-content\/plugins\/ai-engine","restUrl":"https:\/\/www.lowcostwebagency.com\/wp-json","stream":true,"debugMode":false,"eventLogs":false,"speech_recognition":false,"speech_synthesis":false,"typewriter":false,"crossSite":false,"texts":{"Ask me anything!":"Ask me anything!","Jump to the latest message":"Jump to the latest message","Try again":"Try again","Conversation cleared.":"Conversation cleared.","Undo":"Undo","Done!":"Done!","New Chat":"New Chat","No messages yet":"No messages yet","Rename":"Rename","Delete":"Delete","Your text was cut at %d characters.":"Your text was cut at %d characters.","Hold to Talk":"Hold to Talk","Release to Send":"Release to Send","Press Space to talk":"Press Space to talk","Start session to upload images":"Start session to upload images","Usage limit exceeded":"Usage limit exceeded","Connection failed":"Connection failed","Connection failed. Please check your network and try again.":"Connection failed. Please check your network and try again.","Connection lost. Reconnecting...":"Connection lost. Reconnecting...","Connection lost while uploading image. Please try again.":"Connection lost while uploading image. Please try again.","Connection timeout: The server took too long to respond.":"Connection timeout: The server took too long to respond.","Could not start realtime session.":"Could not start realtime session.","An error occurred while starting the realtime session.":"An error occurred while starting the realtime session.","An error occurred while processing your request. Please try again.":"An error occurred while processing your request. Please try again.","An error occurred while committing the stats.":"An error occurred while committing the stats.","An error occurred while committing the discussion.":"An error occurred while committing the discussion.","An error occurred while executing the function.":"An error occurred while executing the function.","Authentication failed: Your session has expired. Please refresh the page.":"Authentication failed: Your session has expired. Please refresh the page.","Error uploading image. Please try again.":"Error uploading image. Please try again.","Failed to access microphone: ":"Failed to access microphone: ","Failed to access microphone. Please ensure microphone permissions are granted and try again.":"Failed to access microphone. Please ensure microphone permissions are granted and try again.","Failed to establish connection with OpenAI servers. Please try again.":"Failed to establish connection with OpenAI servers. Please try again.","Failed to read image file.":"Failed to read image file.","Failed to send image. Please try again.":"Failed to send image. Please try again.","Failed to upload image.":"Failed to upload image.","Image file size must be less than 20MB.":"Image file size must be less than 20MB.","Internal server error: An unexpected error occurred. Please try again.":"Internal server error: An unexpected error occurred. Please try again.","Invalid API key: Please check your OpenAI API key in settings.":"Invalid API key: Please check your OpenAI API key in settings.","Invalid request: The message format was not recognized by the server.":"Invalid request: The message format was not recognized by the server.","MediaDevices API not available. Please ensure you are using HTTPS and a modern browser.":"MediaDevices API not available. Please ensure you are using HTTPS and a modern browser.","Model overloaded: The AI model is currently experiencing high demand.":"Model overloaded: The AI model is currently experiencing high demand.","Network error: Failed to establish connection to the AI service.":"Network error: Failed to establish connection to the AI service.","Please select an image file.":"Please select an image file.","Please start a session before uploading images.":"Please start a session before uploading images.","Quota exceeded: You have reached your usage limit for this period.":"Quota exceeded: You have reached your usage limit for this period.","Rate limit exceeded: Too many requests. Please try again later.":"Rate limit exceeded: Too many requests. Please try again later.","Service unavailable: The AI service is temporarily down for maintenance.":"Service unavailable: The AI service is temporarily down for maintenance."},"actions":[],"blocks":[],"shortcuts":[]}' data-theme='{"type":"internal","name":"ChatGPT","themeId":"chatgpt","settings":{"headerButtonsColor":"#434D58"},"style":"","cssUrl":"https:\/\/www.lowcostwebagency.com\/wp-content\/plugins\/ai-engine\/themes\/chatgpt.css"}'></div> <script type='text/javascript' src="data:text/javascript;base64,KGZ1bmN0aW9uKCl7dmFyIGM9ZG9jdW1lbnQuYm9keS5jbGFzc05hbWU7Yz1jLnJlcGxhY2UoL3dvb2NvbW1lcmNlLW5vLWpzLywnd29vY29tbWVyY2UtanMnKTtkb2N1bWVudC5ib2R5LmNsYXNzTmFtZT1jfSkoKQ==" defer></script>
<script type="text/javascript" id="flying-scripts" src="data:text/javascript;base64,Y29uc3QgbG9hZFNjcmlwdHNUaW1lcj1zZXRUaW1lb3V0KGxvYWRTY3JpcHRzLDUqMTAwMCk7Y29uc3QgdXNlckludGVyYWN0aW9uRXZlbnRzPVsnY2xpY2snLCdtb3VzZW1vdmUnLCdrZXlkb3duJywndG91Y2hzdGFydCcsJ3RvdWNobW92ZScsJ3doZWVsJ107dXNlckludGVyYWN0aW9uRXZlbnRzLmZvckVhY2goZnVuY3Rpb24oZXZlbnQpe3dpbmRvdy5hZGRFdmVudExpc3RlbmVyKGV2ZW50LHRyaWdnZXJTY3JpcHRMb2FkZXIse3Bhc3NpdmU6ITB9KX0pO2Z1bmN0aW9uIHRyaWdnZXJTY3JpcHRMb2FkZXIoKXtsb2FkU2NyaXB0cygpO2NsZWFyVGltZW91dChsb2FkU2NyaXB0c1RpbWVyKTt1c2VySW50ZXJhY3Rpb25FdmVudHMuZm9yRWFjaChmdW5jdGlvbihldmVudCl7d2luZG93LnJlbW92ZUV2ZW50TGlzdGVuZXIoZXZlbnQsdHJpZ2dlclNjcmlwdExvYWRlcix7cGFzc2l2ZTohMH0pfSl9CmZ1bmN0aW9uIGxvYWRTY3JpcHRzKCl7ZG9jdW1lbnQucXVlcnlTZWxlY3RvckFsbCgic2NyaXB0W2RhdGEtdHlwZT0nbGF6eSddIikuZm9yRWFjaChmdW5jdGlvbihlbGVtKXtlbGVtLnNldEF0dHJpYnV0ZSgic3JjIixlbGVtLmdldEF0dHJpYnV0ZSgiZGF0YS1zcmMiKSl9KX0=" defer></script>
<script id="wcml-mc-scripts-js-extra" src="data:text/javascript;base64,dmFyIHdjbWxfbWNfc2V0dGluZ3M9eyJ3Y21sX3NwaW5uZXIiOiJodHRwczovL3d3dy5sb3djb3N0d2ViYWdlbmN5LmNvbS93cC1jb250ZW50L3BsdWdpbnMvc2l0ZXByZXNzLW11bHRpbGluZ3VhbC1jbXMvcmVzL2ltZy9hamF4LWxvYWRlci5naWYiLCJjdXJyZW50X2N1cnJlbmN5Ijp7ImNvZGUiOiJVU0QiLCJzeW1ib2wiOiImIzM2OyJ9LCJjYWNoZV9lbmFibGVkIjoiIn0=" defer></script>
<script data-optimized="1" data-wp-strategy="defer" defer id="wcml-mc-scripts-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/864c22c53c3a1db500aef6628fdb72a7.js?ver=711be"></script>
<script id="thickbox-js-extra" src="data:text/javascript;base64,dmFyIHRoaWNrYm94TDEwbj17Im5leHQiOiJOZXh0IFx1MDAzRSIsInByZXYiOiJcdTAwM0MgUHJldiIsImltYWdlIjoiSW1hZ2UiLCJvZiI6Im9mIiwiY2xvc2UiOiJDbG9zZSIsIm5vaWZyYW1lcyI6IlRoaXMgZmVhdHVyZSByZXF1aXJlcyBpbmxpbmUgZnJhbWVzLiBZb3UgaGF2ZSBpZnJhbWVzIGRpc2FibGVkIG9yIHlvdXIgYnJvd3NlciBkb2VzIG5vdCBzdXBwb3J0IHRoZW0uIiwibG9hZGluZ0FuaW1hdGlvbiI6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tL3dwLWluY2x1ZGVzL2pzL3RoaWNrYm94L2xvYWRpbmdBbmltYXRpb24uZ2lmIn0=" defer></script>
<script data-optimized="1" id="thickbox-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/7cd7b7f36836d52fd3e67198c204f882.js?ver=0cf4c" defer data-deferred="1"></script>
<script id="jquery-ui-core-js-before" src="data:text/javascript;base64,alF1ZXJ5LnVpQmFja0NvbXBhdD0hMA==" defer></script>
<script data-optimized="1" id="jquery-ui-core-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/7551c43cec1dfc51a17d7b78e3d79886.js?ver=74224" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-ui-tooltip-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/e81c4a7c39e0bc5ce67f8e99aea2af2e.js?ver=2de31" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-ui-mouse-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/4b979d0f99246060f63dc04090111a34.js?ver=305a0" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-ui-slider-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/1197abdc32ab83a69b14eec5b79e1f06.js?ver=5d95a" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-ui-datepicker-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/54a1a0f32168d1bef8faf19365f3581c.js?ver=cfbb8" defer data-deferred="1"></script>
<script id="jquery-ui-datepicker-js-after" src="data:text/javascript;base64,alF1ZXJ5KGZ1bmN0aW9uKGpRdWVyeSl7alF1ZXJ5LmRhdGVwaWNrZXIuc2V0RGVmYXVsdHMoeyJjbG9zZVRleHQiOiJDbG9zZSIsImN1cnJlbnRUZXh0IjoiVG9kYXkiLCJtb250aE5hbWVzIjpbIkphbnVhcnkiLCJGZWJydWFyeSIsIk1hcmNoIiwiQXByaWwiLCJNYXkiLCJKdW5lIiwiSnVseSIsIkF1Z3VzdCIsIlNlcHRlbWJlciIsIk9jdG9iZXIiLCJOb3ZlbWJlciIsIkRlY2VtYmVyIl0sIm1vbnRoTmFtZXNTaG9ydCI6WyJKYW4iLCJGZWIiLCJNYXIiLCJBcHIiLCJNYXkiLCJKdW4iLCJKdWwiLCJBdWciLCJTZXAiLCJPY3QiLCJOb3YiLCJEZWMiXSwibmV4dFRleHQiOiJOZXh0IiwicHJldlRleHQiOiJQcmV2aW91cyIsImRheU5hbWVzIjpbIlN1bmRheSIsIk1vbmRheSIsIlR1ZXNkYXkiLCJXZWRuZXNkYXkiLCJUaHVyc2RheSIsIkZyaWRheSIsIlNhdHVyZGF5Il0sImRheU5hbWVzU2hvcnQiOlsiU3VuIiwiTW9uIiwiVHVlIiwiV2VkIiwiVGh1IiwiRnJpIiwiU2F0Il0sImRheU5hbWVzTWluIjpbIlMiLCJNIiwiVCIsIlciLCJUIiwiRiIsIlMiXSwiZGF0ZUZvcm1hdCI6ImQgTSB5eSIsImZpcnN0RGF5IjoxLCJpc1JUTCI6ITF9KX0p" defer></script>
<script data-optimized="1" id="jquery-effects-core-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/d07791d93d8c6407cc425a952409b3be.js?ver=83a64" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-ui-menu-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/0690d10a10618ef2ef4020a1ee5bff47.js?ver=9a037" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-dom-ready-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/6492f64af2f74486bf7a70afc2260607.js?ver=27c8e" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-hooks-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/f84e88a6ddd53ef5cc5b24773a501bd0.js?ver=b5e9f" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-i18n-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/4b114ee18e22025b760f414c5b31b64a.js?ver=841dd" defer data-deferred="1"></script>
<script id="wp-i18n-js-after" src="data:text/javascript;base64,d3AuaTE4bi5zZXRMb2NhbGVEYXRhKHsndGV4dCBkaXJlY3Rpb25cdTAwMDRsdHInOlsnbHRyJ119KQ==" defer></script>
<script data-optimized="1" id="wp-a11y-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/82bff17ae976a1ca7cc0d1e3f9aff27c.js?ver=b069c" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-ui-autocomplete-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/df9349a78f452c6d7473faa72ead1e9b.js?ver=6717a" defer data-deferred="1"></script>
<script data-optimized="1" id="lfb_frontend-libs-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/dd3890664793f9ff51c7a20d2cd52a25.js?ver=76f2d" defer data-deferred="1"></script>
<script data-optimized="1" id="touchpunch-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/2acae1a02a1f6fbcca72af8a5610fed0.js?ver=c7dd6" defer data-deferred="1"></script>
<script id="lfb_frontend-js-extra" src="data:text/javascript;base64,dmFyIGxmYl9mb3Jtcz1beyJjdXJyZW50UmVmIjowLCJyZWZWYXJOYW1lIjoicmVmIiwiaG9tZVVybCI6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tIiwiYWpheHVybCI6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tL3dwLWFkbWluL2FkbWluLWFqYXgucGhwIiwiaW5pdGlhbFByaWNlIjoiMCIsIm1heF9wcmljZSI6IjAiLCJwZXJjZW50VG9QYXkiOiIxMDAiLCJmaXhlZFRvUGF5IjoiMTAwIiwicGF5TW9kZSI6IiIsImN1cnJlbmN5IjoiJCIsImN1cnJlbmN5UG9zaXRpb24iOiJsZWZ0IiwiaW50cm9fZW5hYmxlZCI6IjEiLCJzYXZlX3RvX2NhcnQiOiIwIiwic2F2ZV90b19jYXJ0X2VkZCI6IjAiLCJjb2xvckEiOiIjZjA3NjFmIiwiYW5pbWF0aW9uc1NwZWVkIjoiMC4zIiwiZW1haWxfdG9Vc2VyIjoiMSIsInNob3dTdGVwcyI6IjIiLCJmb3JtSUQiOiI4IiwiZ3Jhdml0eUZvcm1JRCI6IjAiLCJzaG93SW5pdGlhbFByaWNlIjoiMSIsImRpc2FibGVUaXBNb2JpbGUiOiIwIiwibGVnYWxOb3RpY2VFbmFibGUiOiIwIiwibGlua3MiOlt7ImlkIjoiOTU0NyIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjY0IiwiZGVzdGluYXRpb25JRCI6IjY2IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiNjRfNTIxXCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU0OCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjY0IiwiZGVzdGluYXRpb25JRCI6IjcwIiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiNjRfNTIwXCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU0OSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjY0IiwiZGVzdGluYXRpb25JRCI6Ijg3IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiNjRfNTI2XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU1MCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjY0IiwiZGVzdGluYXRpb25JRCI6IjY5IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiNjRfNTIzXCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU1MSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjY0IiwiZGVzdGluYXRpb25JRCI6IjY4IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiNjRfNTIyXCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU1MiIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjY0IiwiZGVzdGluYXRpb25JRCI6IjY1IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiNjRfNjE1XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU1MyIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjY2IiwiZGVzdGluYXRpb25JRCI6Ijk0IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU1NCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6Ijk0IiwiZGVzdGluYXRpb25JRCI6Ijg2IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU1NSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6Ijg2IiwiZGVzdGluYXRpb25JRCI6IjkxIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU1NiIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjcwIiwiZGVzdGluYXRpb25JRCI6Ijc3IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU1NyIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6Ijc3IiwiZGVzdGluYXRpb25JRCI6IjkyIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU1OCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6Ijg3IiwiZGVzdGluYXRpb25JRCI6Ijg4IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU1OSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6Ijg4IiwiZGVzdGluYXRpb25JRCI6IjcxIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU2MCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjczIiwiZGVzdGluYXRpb25JRCI6Ijg5IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU2MSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjY5IiwiZGVzdGluYXRpb25JRCI6IjczIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU2MiIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjY5IiwiZGVzdGluYXRpb25JRCI6IjE3OSIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjY5XzQ0MFwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk1NjMiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiI2OCIsImRlc3RpbmF0aW9uSUQiOiI5MCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk1NjQiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiI2NSIsImRlc3RpbmF0aW9uSUQiOiI5MyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk1NjUiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNzkiLCJkZXN0aW5hdGlvbklEIjoiOTEiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCI2OV80NDBcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTY2IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiOTMiLCJkZXN0aW5hdGlvbklEIjoiOTEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTY3IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiOTAiLCJkZXN0aW5hdGlvbklEIjoiOTEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTY4IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiODkiLCJkZXN0aW5hdGlvbklEIjoiOTEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTY5IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiNzEiLCJkZXN0aW5hdGlvbklEIjoiOTEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTcwIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiOTIiLCJkZXN0aW5hdGlvbklEIjoiOTEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTcxIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiOTEiLCJkZXN0aW5hdGlvbklEIjoiOTUiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCI5MV83MzhcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTcyIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiOTEiLCJkZXN0aW5hdGlvbklEIjoiOTgiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCI5MV83MDhcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTczIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiOTEiLCJkZXN0aW5hdGlvbklEIjoiMTAxIiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiOTFfNzAxXCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU3NCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjkxIiwiZGVzdGluYXRpb25JRCI6IjEwNCIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjkxXzcwMlwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk1NzUiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiI5MSIsImRlc3RpbmF0aW9uSUQiOiIxMDciLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCI5MV83MDNcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTc2IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiOTEiLCJkZXN0aW5hdGlvbklEIjoiMTA5IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiOTFfNzA1XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU3NyIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6Ijk1IiwiZGVzdGluYXRpb25JRCI6Ijk2IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU3OCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6Ijk2IiwiZGVzdGluYXRpb25JRCI6Ijk3IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU3OSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6Ijk4IiwiZGVzdGluYXRpb25JRCI6Ijk5IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU4MCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6Ijk5IiwiZGVzdGluYXRpb25JRCI6IjEwMCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk1ODEiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMDEiLCJkZXN0aW5hdGlvbklEIjoiMTAyIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU4MiIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEwMiIsImRlc3RpbmF0aW9uSUQiOiIxMDMiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTgzIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTA0IiwiZGVzdGluYXRpb25JRCI6IjEwNSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk1ODQiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMDUiLCJkZXN0aW5hdGlvbklEIjoiMTA2IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU4NSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEwNyIsImRlc3RpbmF0aW9uSUQiOiIxMDgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTg2IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTA5IiwiZGVzdGluYXRpb25JRCI6IjExMCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk1ODciLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMDQiLCJkZXN0aW5hdGlvbklEIjoiMTgwIiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMTA0Xzg1N1wiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk1ODgiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiI5NyIsImRlc3RpbmF0aW9uSUQiOiIxMTEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTg5IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTAwIiwiZGVzdGluYXRpb25JRCI6IjExMSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk1OTAiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMDMiLCJkZXN0aW5hdGlvbklEIjoiMTExIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU5MSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEwNiIsImRlc3RpbmF0aW9uSUQiOiIxMTEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTkyIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTA4IiwiZGVzdGluYXRpb25JRCI6IjExMSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk1OTMiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMTAiLCJkZXN0aW5hdGlvbklEIjoiMTExIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTU5NCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE4MCIsImRlc3RpbmF0aW9uSUQiOiIxMTEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTk1IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTExIiwiZGVzdGluYXRpb25JRCI6IjEyNyIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjExMV85MDFcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTk2IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTExIiwiZGVzdGluYXRpb25JRCI6IjEyNCIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjExMV84OTlcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTk3IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTExIiwiZGVzdGluYXRpb25JRCI6IjEyMSIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjExMV84OTJcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTk4IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTExIiwiZGVzdGluYXRpb25JRCI6IjExOCIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjExMV84OTNcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NTk5IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTExIiwiZGVzdGluYXRpb25JRCI6IjExNSIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjExMV84OTRcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjAwIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTExIiwiZGVzdGluYXRpb25JRCI6IjExMyIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjExMV84OTZcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjAyIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTEzIiwiZGVzdGluYXRpb25JRCI6IjExMiIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2MDMiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMTUiLCJkZXN0aW5hdGlvbklEIjoiMTE0IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYwNCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjExOCIsImRlc3RpbmF0aW9uSUQiOiIxODEiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxMThfOTM3XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYwNSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjExOCIsImRlc3RpbmF0aW9uSUQiOiIxMTciLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjA2IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTE3IiwiZGVzdGluYXRpb25JRCI6IjExNiIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2MDciLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMjEiLCJkZXN0aW5hdGlvbklEIjoiMTIwIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYwOCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEyMCIsImRlc3RpbmF0aW9uSUQiOiIxMTkiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjA5IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTI0IiwiZGVzdGluYXRpb25JRCI6IjEyMyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2MTAiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMjMiLCJkZXN0aW5hdGlvbklEIjoiMTIyIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYxMiIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEyNiIsImRlc3RpbmF0aW9uSUQiOiIxMjciLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxMjdfMTAwMVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9LHtcImludGVyYWN0aW9uXCI6XCIxMjdfMTAwMlwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiT1IifSx7ImlkIjoiOTYxMyIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEyNiIsImRlc3RpbmF0aW9uSUQiOiIxMjUiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjE0IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTI1IiwiZGVzdGluYXRpb25JRCI6IjEyOCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2MTUiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMjIiLCJkZXN0aW5hdGlvbklEIjoiMTI4IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYxNiIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjExOSIsImRlc3RpbmF0aW9uSUQiOiIxMjgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjE3IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTE2IiwiZGVzdGluYXRpb25JRCI6IjEyOCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2MTgiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMTQiLCJkZXN0aW5hdGlvbklEIjoiMTI4IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYxOSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjExMiIsImRlc3RpbmF0aW9uSUQiOiIxMjgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjIwIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTI4IiwiZGVzdGluYXRpb25JRCI6IjEyOSIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjEyOF8xMDE0XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYyMSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEyOCIsImRlc3RpbmF0aW9uSUQiOiIxMzQiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxMjhfMTAxMlwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2MjIiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMjgiLCJkZXN0aW5hdGlvbklEIjoiMTM3IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMTI4XzEwMDVcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjIzIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTI4IiwiZGVzdGluYXRpb25JRCI6IjE0MCIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjEyOF8xMDA2XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYyNCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEyOCIsImRlc3RpbmF0aW9uSUQiOiIxNDIiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxMjhfMTAwN1wiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2MjUiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMjgiLCJkZXN0aW5hdGlvbklEIjoiMTQ0IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMTI4XzEwMDlcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjI2IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTQwIiwiZGVzdGluYXRpb25JRCI6IjE4MiIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjE0MF8xMDk0XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYyNyIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEyOSIsImRlc3RpbmF0aW9uSUQiOiIxMzAiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjI4IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTM0IiwiZGVzdGluYXRpb25JRCI6IjEzMyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2MjkiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMzciLCJkZXN0aW5hdGlvbklEIjoiMTM2IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYzMCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE0MCIsImRlc3RpbmF0aW9uSUQiOiIxMzkiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjMxIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTQyIiwiZGVzdGluYXRpb25JRCI6IjE0MSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2MzIiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNDQiLCJkZXN0aW5hdGlvbklEIjoiMTQzIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYzMyIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEzMCIsImRlc3RpbmF0aW9uSUQiOiIxMzEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjM0IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTMzIiwiZGVzdGluYXRpb25JRCI6IjEzMiIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2MzUiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMzYiLCJkZXN0aW5hdGlvbklEIjoiMTM1IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYzNiIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEzOSIsImRlc3RpbmF0aW9uSUQiOiIxMzgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjM3IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTMxIiwiZGVzdGluYXRpb25JRCI6IjE2MSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2MzgiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxMzIiLCJkZXN0aW5hdGlvbklEIjoiMTYxIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTYzOSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEzNSIsImRlc3RpbmF0aW9uSUQiOiIxNjEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjQwIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTM4IiwiZGVzdGluYXRpb25JRCI6IjE2MSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NDEiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNDEiLCJkZXN0aW5hdGlvbklEIjoiMTYxIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY0MiIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE0MyIsImRlc3RpbmF0aW9uSUQiOiIxNjEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjQzIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTgxIiwiZGVzdGluYXRpb25JRCI6IjEyOCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NDQiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxODIiLCJkZXN0aW5hdGlvbklEIjoiMTYxIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY0NSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE1NiIsImRlc3RpbmF0aW9uSUQiOiIxODMiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxNTZfMTE5NlwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NDYiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNjAiLCJkZXN0aW5hdGlvbklEIjoiMTU5IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY0NyIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE1OCIsImRlc3RpbmF0aW9uSUQiOiIxNTciLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjQ4IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTU2IiwiZGVzdGluYXRpb25JRCI6IjE1NSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NDkiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNTUiLCJkZXN0aW5hdGlvbklEIjoiMTU0IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY1MCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE1MyIsImRlc3RpbmF0aW9uSUQiOiIxNTIiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjUxIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTUyIiwiZGVzdGluYXRpb25JRCI6IjE1MSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NTIiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNTAiLCJkZXN0aW5hdGlvbklEIjoiMTQ5IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY1MyIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE0OSIsImRlc3RpbmF0aW9uSUQiOiIxNDgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjU0IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTYxIiwiZGVzdGluYXRpb25JRCI6IjE1MCIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjE2MV8xMjI3XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY1NSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE0NSIsImRlc3RpbmF0aW9uSUQiOiIxNDYiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjU2IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTQ2IiwiZGVzdGluYXRpb25JRCI6IjE0NyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NTciLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNjEiLCJkZXN0aW5hdGlvbklEIjoiMTQ1IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMTYxXzEyMjlcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjU4IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTYxIiwiZGVzdGluYXRpb25JRCI6IjE1MyIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjE2MV8xMjIwXCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY1OSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE2MSIsImRlc3RpbmF0aW9uSUQiOiIxNTYiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxNjFfMTIyMVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NjAiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNjEiLCJkZXN0aW5hdGlvbklEIjoiMTU4IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMTYxXzEyMjJcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjYxIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTYxIiwiZGVzdGluYXRpb25JRCI6IjE2MCIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjE2MV8xMjI0XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY2MiIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE0NyIsImRlc3RpbmF0aW9uSUQiOiIxNzgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjYzIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTQ4IiwiZGVzdGluYXRpb25JRCI6IjE3OCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NjQiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNTEiLCJkZXN0aW5hdGlvbklEIjoiMTc4IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY2NSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE1NCIsImRlc3RpbmF0aW9uSUQiOiIxNzgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjY2IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTU3IiwiZGVzdGluYXRpb25JRCI6IjE3OCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NjciLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNTkiLCJkZXN0aW5hdGlvbklEIjoiMTc4IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY2OCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE4MyIsImRlc3RpbmF0aW9uSUQiOiIxNzgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjY5IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTc4IiwiZGVzdGluYXRpb25JRCI6IjE2MiIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjE3OF8xMzQyXCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY3MCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE3OCIsImRlc3RpbmF0aW9uSUQiOiIxNjUiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxNzhfMTM0MFwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NzEiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNzgiLCJkZXN0aW5hdGlvbklEIjoiMTY4IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMTc4XzEzMzNcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjcyIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTc4IiwiZGVzdGluYXRpb25JRCI6IjE3MSIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjE3OF8xMzM0XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY3MyIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE3OCIsImRlc3RpbmF0aW9uSUQiOiIxNzQiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxNzhfMTMzNVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NzQiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNzgiLCJkZXN0aW5hdGlvbklEIjoiMTc2IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMTc4XzEzMzdcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5Njc1IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTYyIiwiZGVzdGluYXRpb25JRCI6IjE2MyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NzYiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNjMiLCJkZXN0aW5hdGlvbklEIjoiMTY0IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY3NyIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE2NSIsImRlc3RpbmF0aW9uSUQiOiIxNjYiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5Njc4IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTY2IiwiZGVzdGluYXRpb25JRCI6IjE2NyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2NzkiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNjgiLCJkZXN0aW5hdGlvbklEIjoiMTY5IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY4MCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE2OSIsImRlc3RpbmF0aW9uSUQiOiIxNzAiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjgxIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTcxIiwiZGVzdGluYXRpb25JRCI6IjE3MiIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2ODIiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNzIiLCJkZXN0aW5hdGlvbklEIjoiMTczIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY4MyIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE3NCIsImRlc3RpbmF0aW9uSUQiOiIxNzUiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5Njg0IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTc2IiwiZGVzdGluYXRpb25JRCI6IjE3NyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2ODUiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNzEiLCJkZXN0aW5hdGlvbklEIjoiMTg0IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY4NiIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE4NCIsImRlc3RpbmF0aW9uSUQiOiI2MyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2ODciLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNzciLCJkZXN0aW5hdGlvbklEIjoiNjMiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5Njg4IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTc1IiwiZGVzdGluYXRpb25JRCI6IjYzIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY4OSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE3MyIsImRlc3RpbmF0aW9uSUQiOiI2MyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2OTAiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNzAiLCJkZXN0aW5hdGlvbklEIjoiNjMiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NjkxIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTY3IiwiZGVzdGluYXRpb25JRCI6IjYzIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTY5MiIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE2NCIsImRlc3RpbmF0aW9uSUQiOiI2MyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2OTMiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiI2MyIsImRlc3RpbmF0aW9uSUQiOiI1OSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2OTQiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiI1OSIsImRlc3RpbmF0aW9uSUQiOiI2MSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2OTUiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiI2MSIsImRlc3RpbmF0aW9uSUQiOiI2MiIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk2OTYiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiI5MSIsImRlc3RpbmF0aW9uSUQiOiIxODAiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCI5MV83MDZcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifSx7XCJpbnRlcmFjdGlvblwiOlwiOTFfNzA0XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiJPUiJ9LHsiaWQiOiI5Njk3IiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTExIiwiZGVzdGluYXRpb25JRCI6IjE4MSIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjExMV84OTdcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifSx7XCJpbnRlcmFjdGlvblwiOlwiMTExXzg5NVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiT1IifSx7ImlkIjoiOTY5OCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjEyOCIsImRlc3RpbmF0aW9uSUQiOiIxODIiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxMjhfMTAxMFwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9LHtcImludGVyYWN0aW9uXCI6XCIxMjhfMTAwOFwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiT1IifSx7ImlkIjoiOTY5OSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE2MSIsImRlc3RpbmF0aW9uSUQiOiIxODMiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxNjFfMTIyNVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9LHtcImludGVyYWN0aW9uXCI6XCIxNjFfMTIyM1wiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiT1IifSx7ImlkIjoiOTcwMCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE3OCIsImRlc3RpbmF0aW9uSUQiOiIxODQiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxNzhfMTMzOFwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9LHtcImludGVyYWN0aW9uXCI6XCIxNzhfMTMzNlwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiT1IifSx7ImlkIjoiOTcwMSIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjE3OCIsImRlc3RpbmF0aW9uSUQiOiI2MyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MDIiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiIxNjEiLCJkZXN0aW5hdGlvbklEIjoiNjMiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzAzIiwiZm9ybUlEIjoiOCIsIm9yaWdpbklEIjoiMTI4IiwiZGVzdGluYXRpb25JRCI6IjYzIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTcwNCIsImZvcm1JRCI6IjgiLCJvcmlnaW5JRCI6IjExMSIsImRlc3RpbmF0aW9uSUQiOiI2MyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MDUiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiI5MSIsImRlc3RpbmF0aW9uSUQiOiI2MyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MDYiLCJmb3JtSUQiOiI4Iiwib3JpZ2luSUQiOiI2NCIsImRlc3RpbmF0aW9uSUQiOiI2MyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn1dLCJjbG9zZV91cmwiOiIjIiwicmVkaXJlY3Rpb25zIjpbeyJpZCI6IjEiLCJmb3JtSUQiOiI4IiwiY29uZGl0aW9ucyI6IltdIiwiY29uZGl0aW9uc09wZXJhdG9yIjoiIiwidXJsIjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vIn0seyJpZCI6IjIiLCJmb3JtSUQiOiI4IiwiY29uZGl0aW9ucyI6IltdIiwiY29uZGl0aW9uc09wZXJhdG9yIjoiIiwidXJsIjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vIn0seyJpZCI6IjMiLCJmb3JtSUQiOiI4IiwiY29uZGl0aW9ucyI6IltdIiwiY29uZGl0aW9uc09wZXJhdG9yIjoiIiwidXJsIjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vIn0seyJpZCI6IjQiLCJmb3JtSUQiOiI4IiwiY29uZGl0aW9ucyI6IltdIiwiY29uZGl0aW9uc09wZXJhdG9yIjoiIiwidXJsIjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vIn0seyJpZCI6IjUiLCJmb3JtSUQiOiI4IiwiY29uZGl0aW9ucyI6IltdIiwiY29uZGl0aW9uc09wZXJhdG9yIjoiIiwidXJsIjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vIn0seyJpZCI6IjYiLCJmb3JtSUQiOiI4IiwiY29uZGl0aW9ucyI6IltdIiwiY29uZGl0aW9uc09wZXJhdG9yIjoiIiwidXJsIjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vIn1dLCJ1c2VSZWRpcmVjdGlvbkNvbmRpdGlvbnMiOiIwIiwidXNlUGRmIjoxLCJ0eHRfeWVzIjoiWWVzIiwidHh0X25vIjoiTm8iLCJ0eHRfbGFzdEJ0biI6IlN1Ym1pdCIsInR4dF9idG5TdGVwIjoiTmV4dCAiLCJkYXRlRm9ybWF0IjoiZCBNIHl5eXkiLCJkYXRlUGlja2VyTGFuZ3VhZ2UiOiIiLCJ0aG91c2FuZHNTZXBhcmF0b3IiOiIiLCJkZWNpbWFsc1NlcGFyYXRvciI6Ii4iLCJtaWxsaW9uU2VwYXJhdG9yIjoiIiwiYmlsbGlvbnNTZXBhcmF0b3IiOiIiLCJzdW1tYXJ5X2hpZGVRdCI6IjEiLCJzdW1tYXJ5X2hpZGVaZXJvIjoiMSIsInN1bW1hcnlfaGlkZVplcm9RdCI6IjEiLCJzdW1tYXJ5X2hpZGVQcmljZXMiOiIxIiwic3VtbWFyeV9oaWRlWmVyb0RlY2ltYWxzIjoiMSIsImdyb3VwQXV0b0NsaWNrIjoiMSIsImZpbGVzVXBsb2FkX3RleHQiOiJEcm9wIGZpbGVzIGhlcmUgdG8gdXBsb2FkIiwiZmlsZXNVcGxvYWRTaXplX3RleHQiOiJGaWxlIGlzIHRvbyBiaWcgKG1heCBzaXplOiB7e21heEZpbGVzaXplfX1NQikiLCJmaWxlc1VwbG9hZFR5cGVfdGV4dCI6IkludmFsaWQgZmlsZSB0eXBlIiwiZmlsZXNVcGxvYWRMaW1pdF90ZXh0IjoiWW91IGNhbiBub3QgdXBsb2FkIGFueSBtb3JlIGZpbGVzIiwic2VuZENvbnRhY3RBU0FQIjoiMSIsInNob3dUb3RhbEJvdHRvbSI6IjAiLCJzdHJpcGVQdWJLZXkiOiIiLCJzY3JvbGxUb3BNYXJnaW4iOiIwIiwic2Nyb2xsVG9wTWFyZ2luTW9iaWxlIjoiMCIsInJlZGlyZWN0aW9uRGVsYXkiOiIwIiwiZ21hcF9rZXkiOiIiLCJ0eHREaXN0YW5jZUVycm9yIjoiQ2FsY3VsYXRpbmcgdGhlIGRpc3RhbmNlIGNvdWxkIG5vdCBiZSBwZXJmb3JtZWQsIHBsZWFzZSB2ZXJpZnkgdGhlIGlucHV0IGFkZHJlc3NlcyIsImNhcHRjaGFVcmwiOiJodHRwczovL3d3dy5sb3djb3N0d2ViYWdlbmN5LmNvbS93cC1jb250ZW50L3BsdWdpbnMvV1BfRXN0aW1hdGlvbl9Gb3JtL2luY2x1ZGVzL2NhcHRjaGEvZ2V0X2NhcHRjaGEucGhwIiwic3VtbWFyeV9ub0RlY2ltYWxzIjoiMSIsInNjcm9sbFRvcFBhZ2UiOiIxIiwiZGlzYWJsZURyb3Bkb3ducyI6IjEiLCJpbWdJY29uU3R5bGUiOiJ6b29tIiwic3VtbWFyeV9oaWRlRmluYWxTdGVwIjoiMSIsInRpbWVNb2RlQU0iOiIwIiwiZW5hYmxlU2hpbmVGeEJ0biI6IjEiLCJzdW1tYXJ5X3Nob3dBbGxQcmljZXNFbWFpbCI6IjAiLCJpbWdUaXRsZXNTdHlsZSI6IiIsImxhc3RTIjoiMTY2NjA5MzEyNTI0MSIsImVtcHR5V29vQ2FydCI6IjAiLCJzZW5kVXJsVmFyaWFibGVzIjoiMCIsInNlbmRWYXJpYWJsZXNNZXRob2QiOiIiLCJlbmFibGVaYXBpZXIiOiIwIiwiemFwaWVyV2ViSG9vayI6IiIsInN1bW1hcnlfc2hvd0Rlc2NyaXB0aW9ucyI6IjEiLCJpbWdQcmV2aWV3IjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vd3AtY29udGVudC9wbHVnaW5zL1dQX0VzdGltYXRpb25fRm9ybS9hc3NldHMvaW1nL2ZpbGUtMy0xMjgucG5nIiwicHJvZ3Jlc3NCYXJQcmljZVR5cGUiOiIiLCJyYXpvcnBheV9wdWJsaXNoS2V5IjoiIiwicmF6b3JwYXlfbG9nb0ltZyI6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tL3dwLWNvbnRlbnQvdXBsb2Fkcy8yMDIyLzEwL2NyZWRpdENhcmRAMngucG5nIiwidmFyaWFibGVzIjpbXSwidXNlRW1haWxWZXJpZmljYXRpb24iOiIwIiwidHh0X2VtYWlsQWN0aXZhdGlvbkNvZGUiOiJGaWxsIHlvdXIgdmVyaWZpY2F0aW9uIGNvZGUgaGVyZSIsInR4dF9lbWFpbEFjdGl2YXRpb25JbmZvIjoiQSB1bmlxdWUgdmVyaWZpY2F0aW9uIGNvZGUgaGFzIGp1c3QgYmVlbiBzZW50IHRvIHlvdSBieSBlbWFpbCwgcGxlYXNlIGNvcHkgaXQgaW4gdGhlIGZpZWxkIGJlbG93IHRvIHZhbGlkYXRlIHlvdXIgZW1haWwgYWRkcmVzcy4iLCJ1c2VDYXB0Y2hhIjoiMCIsInJlY2FwdGNoYTNLZXkiOiIiLCJkaXN0YW5jZXNNb2RlIjoicm91dGUiLCJlbmFibGVDdXN0b21lckFjY291bnQiOiIwIiwidHh0Q3VzdG9tZXJzRGF0YUZvcmdvdFBhc3NTZW50IjoiIiwidHh0Q3VzdG9tZXJzRGF0YUZvcmdvdFBhc3NMaW5rIjoiIiwiZW1haWxDdXN0b21lckxpbmtzIjoiMSIsImVuYWJsZVBkZkRvd25sb2FkIjoiMSIsInVzZVNpZ25hdHVyZSI6IjAiLCJ1c2VWQVQiOiIwIiwidmF0QW1vdW50IjoiMjAiLCJ2YXRMYWJlbCI6IlZBVCIsImF1dG9jbG9zZURhdGVwaWNrZXIiOiIwIiwiZmxvYXRTdW1tYXJ5X3Nob3dJbmZvIjoiMSIsImhpZGVGaW5hbGJ0biI6IjAiLCJjYXJ0UGFnZSI6IiIsImRpc2FibGVTY3JvbGwiOiIwIn0seyJjdXJyZW50UmVmIjowLCJyZWZWYXJOYW1lIjoicmVmIiwiaG9tZVVybCI6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tIiwiYWpheHVybCI6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tL3dwLWFkbWluL2FkbWluLWFqYXgucGhwIiwiaW5pdGlhbFByaWNlIjoiMCIsIm1heF9wcmljZSI6IjAiLCJwZXJjZW50VG9QYXkiOiIxMDAiLCJmaXhlZFRvUGF5IjoiMTAwIiwicGF5TW9kZSI6IiIsImN1cnJlbmN5IjoiJCIsImN1cnJlbmN5UG9zaXRpb24iOiJsZWZ0IiwiaW50cm9fZW5hYmxlZCI6IjEiLCJzYXZlX3RvX2NhcnQiOiIwIiwic2F2ZV90b19jYXJ0X2VkZCI6IjAiLCJjb2xvckEiOiIjZjA3NjFmIiwiYW5pbWF0aW9uc1NwZWVkIjoiMC4zIiwiZW1haWxfdG9Vc2VyIjoiMSIsInNob3dTdGVwcyI6IjIiLCJmb3JtSUQiOiI5IiwiZ3Jhdml0eUZvcm1JRCI6IjAiLCJzaG93SW5pdGlhbFByaWNlIjoiMSIsImRpc2FibGVUaXBNb2JpbGUiOiIwIiwibGVnYWxOb3RpY2VFbmFibGUiOiIwIiwibGlua3MiOlt7ImlkIjoiOTcwNyIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjE4OSIsImRlc3RpbmF0aW9uSUQiOiIxOTEiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxODlfMTQ0OVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MDgiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIxODkiLCJkZXN0aW5hdGlvbklEIjoiMTk0IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMTg5XzE0NDhcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzA5IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMTg5IiwiZGVzdGluYXRpb25JRCI6IjE5OSIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjE4OV8xNDUyXCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTcxMCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjE4OSIsImRlc3RpbmF0aW9uSUQiOiIxOTMiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxODlfMTQ1MVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MTEiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIxODkiLCJkZXN0aW5hdGlvbklEIjoiMTkyIiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMTg5XzE0NTBcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzEyIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMTg5IiwiZGVzdGluYXRpb25JRCI6IjE5MCIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjE4OV8xNDUzXCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTcxMyIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjE5MSIsImRlc3RpbmF0aW9uSUQiOiIyMDYiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzE0IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjA2IiwiZGVzdGluYXRpb25JRCI6IjE5OCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MTUiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIxOTgiLCJkZXN0aW5hdGlvbklEIjoiMjAzIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTcxNiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjE5NCIsImRlc3RpbmF0aW9uSUQiOiIxOTciLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzE3IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMTk3IiwiZGVzdGluYXRpb25JRCI6IjIwNCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MTgiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIxOTkiLCJkZXN0aW5hdGlvbklEIjoiMjAwIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTcxOSIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIwMCIsImRlc3RpbmF0aW9uSUQiOiIxOTUiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzIwIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMTk2IiwiZGVzdGluYXRpb25JRCI6IjIwMSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MjEiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIxOTMiLCJkZXN0aW5hdGlvbklEIjoiMTk2IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTcyMiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjE5MyIsImRlc3RpbmF0aW9uSUQiOiIyOTEiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIxOTNfMTQ3NlwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MjMiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIxOTIiLCJkZXN0aW5hdGlvbklEIjoiMjAyIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTcyNCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjE5MCIsImRlc3RpbmF0aW9uSUQiOiIyMDUiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzI1IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjkxIiwiZGVzdGluYXRpb25JRCI6IjIwMyIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjE5M18xNDc2XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTcyNiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIwNSIsImRlc3RpbmF0aW9uSUQiOiIyMDMiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzI3IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjAyIiwiZGVzdGluYXRpb25JRCI6IjIwMyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MjgiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMDEiLCJkZXN0aW5hdGlvbklEIjoiMjAzIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTcyOSIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjE5NSIsImRlc3RpbmF0aW9uSUQiOiIyMDMiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzMwIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjA0IiwiZGVzdGluYXRpb25JRCI6IjIwMyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MzEiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMDMiLCJkZXN0aW5hdGlvbklEIjoiMjA3IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjAzXzE1NDZcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzMyIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjAzIiwiZGVzdGluYXRpb25JRCI6IjIxMCIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjIwM18xNTQ0XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTczMyIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIwMyIsImRlc3RpbmF0aW9uSUQiOiIyMTMiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIyMDNfMTUzN1wiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MzQiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMDMiLCJkZXN0aW5hdGlvbklEIjoiMjE2IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjAzXzE1MzhcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzM1IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjAzIiwiZGVzdGluYXRpb25JRCI6IjIxOSIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjIwM18xNTM5XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTczNiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIwMyIsImRlc3RpbmF0aW9uSUQiOiIyMjEiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIyMDNfMTU0MVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3MzciLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMDciLCJkZXN0aW5hdGlvbklEIjoiMjA4IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTczOCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIwOCIsImRlc3RpbmF0aW9uSUQiOiIyMDkiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzM5IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjEwIiwiZGVzdGluYXRpb25JRCI6IjIxMSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NDAiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMTEiLCJkZXN0aW5hdGlvbklEIjoiMjEyIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc0MSIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIxMyIsImRlc3RpbmF0aW9uSUQiOiIyMTQiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzQyIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjE0IiwiZGVzdGluYXRpb25JRCI6IjIxNSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NDMiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMTYiLCJkZXN0aW5hdGlvbklEIjoiMjE3IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc0NCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIxNyIsImRlc3RpbmF0aW9uSUQiOiIyMTgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzQ1IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjE5IiwiZGVzdGluYXRpb25JRCI6IjIyMCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NDYiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMjEiLCJkZXN0aW5hdGlvbklEIjoiMjIyIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc0NyIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIxNiIsImRlc3RpbmF0aW9uSUQiOiIyOTIiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIyMTZfMTYyNlwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NDgiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMDkiLCJkZXN0aW5hdGlvbklEIjoiMjIzIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc0OSIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIxMiIsImRlc3RpbmF0aW9uSUQiOiIyMjMiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzUwIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjE1IiwiZGVzdGluYXRpb25JRCI6IjIyMyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NTEiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMTgiLCJkZXN0aW5hdGlvbklEIjoiMjIzIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc1MiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIyMCIsImRlc3RpbmF0aW9uSUQiOiIyMjMiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzUzIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjIyIiwiZGVzdGluYXRpb25JRCI6IjIyMyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NTQiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyOTIiLCJkZXN0aW5hdGlvbklEIjoiMjIzIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc1NSIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIyMyIsImRlc3RpbmF0aW9uSUQiOiIyMzkiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIyMjNfMTY2M1wiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NTYiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMjMiLCJkZXN0aW5hdGlvbklEIjoiMjM2IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjIzXzE2NjFcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzU3IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjIzIiwiZGVzdGluYXRpb25JRCI6IjIzMyIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjIyM18xNjU0XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc1OCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIyMyIsImRlc3RpbmF0aW9uSUQiOiIyMzAiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIyMjNfMTY1NVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NTkiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMjMiLCJkZXN0aW5hdGlvbklEIjoiMjI3IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjIzXzE2NTZcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzYwIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjIzIiwiZGVzdGluYXRpb25JRCI6IjIyNSIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjIyM18xNjU4XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc2MSIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIyNSIsImRlc3RpbmF0aW9uSUQiOiIyMjQiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzYyIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjI3IiwiZGVzdGluYXRpb25JRCI6IjIyNiIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NjMiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMzAiLCJkZXN0aW5hdGlvbklEIjoiMjkzIiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjMwXzE2OTRcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzY0IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjMwIiwiZGVzdGluYXRpb25JRCI6IjIyOSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NjUiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMjkiLCJkZXN0aW5hdGlvbklEIjoiMjI4IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc2NiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIzMyIsImRlc3RpbmF0aW9uSUQiOiIyMzIiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzY3IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjMyIiwiZGVzdGluYXRpb25JRCI6IjIzMSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NjgiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMzYiLCJkZXN0aW5hdGlvbklEIjoiMjM1IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc2OSIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIzNSIsImRlc3RpbmF0aW9uSUQiOiIyMzQiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzcwIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjM4IiwiZGVzdGluYXRpb25JRCI6IjIzOSIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjIzOV8xNzU3XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn0se1wiaW50ZXJhY3Rpb25cIjpcIjIzOV8xNzU4XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiJPUiJ9LHsiaWQiOiI5NzcxIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjM4IiwiZGVzdGluYXRpb25JRCI6IjIzNyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NzIiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMzciLCJkZXN0aW5hdGlvbklEIjoiMjQwIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc3MyIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIzNCIsImRlc3RpbmF0aW9uSUQiOiIyNDAiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5Nzc0IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjMxIiwiZGVzdGluYXRpb25JRCI6IjI0MCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NzUiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMjgiLCJkZXN0aW5hdGlvbklEIjoiMjQwIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc3NiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIyNiIsImRlc3RpbmF0aW9uSUQiOiIyNDAiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5Nzc3IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjI0IiwiZGVzdGluYXRpb25JRCI6IjI0MCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3NzgiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNDAiLCJkZXN0aW5hdGlvbklEIjoiMjQxIiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjQwXzE3NzBcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5Nzc5IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjQwIiwiZGVzdGluYXRpb25JRCI6IjI0NiIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjI0MF8xNzY4XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc4MCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI0MCIsImRlc3RpbmF0aW9uSUQiOiIyNDkiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIyNDBfMTc2MVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3ODEiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNDAiLCJkZXN0aW5hdGlvbklEIjoiMjUyIiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjQwXzE3NjJcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzgyIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjQwIiwiZGVzdGluYXRpb25JRCI6IjI1NCIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjI0MF8xNzYzXCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc4MyIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI0MCIsImRlc3RpbmF0aW9uSUQiOiIyNTYiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIyNDBfMTc2NVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3ODQiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNTIiLCJkZXN0aW5hdGlvbklEIjoiMjk0IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjUyXzE4NDVcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5Nzg1IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjQxIiwiZGVzdGluYXRpb25JRCI6IjI0MiIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3ODYiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNDYiLCJkZXN0aW5hdGlvbklEIjoiMjQ1IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc4NyIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI0OSIsImRlc3RpbmF0aW9uSUQiOiIyNDgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5Nzg4IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjUyIiwiZGVzdGluYXRpb25JRCI6IjI1MSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3ODkiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNTQiLCJkZXN0aW5hdGlvbklEIjoiMjUzIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc5MCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI1NiIsImRlc3RpbmF0aW9uSUQiOiIyNTUiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5NzkxIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjQyIiwiZGVzdGluYXRpb25JRCI6IjI0MyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3OTIiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNDUiLCJkZXN0aW5hdGlvbklEIjoiMjQ0IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc5MyIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI0OCIsImRlc3RpbmF0aW9uSUQiOiIyNDciLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5Nzk0IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjUxIiwiZGVzdGluYXRpb25JRCI6IjI1MCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3OTUiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNDMiLCJkZXN0aW5hdGlvbklEIjoiMjczIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc5NiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI0NCIsImRlc3RpbmF0aW9uSUQiOiIyNzMiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5Nzk3IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjQ3IiwiZGVzdGluYXRpb25JRCI6IjI3MyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk3OTgiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNTAiLCJkZXN0aW5hdGlvbklEIjoiMjczIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTc5OSIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI1MyIsImRlc3RpbmF0aW9uSUQiOiIyNzMiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODAwIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjU1IiwiZGVzdGluYXRpb25JRCI6IjI3MyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MDEiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyOTMiLCJkZXN0aW5hdGlvbklEIjoiMjQwIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTgwMiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI5NCIsImRlc3RpbmF0aW9uSUQiOiIyNzMiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODAzIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjY4IiwiZGVzdGluYXRpb25JRCI6IjI5NSIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjI2OF8xOTQxXCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTgwNCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI3MiIsImRlc3RpbmF0aW9uSUQiOiIyNzEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODA1IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjcwIiwiZGVzdGluYXRpb25JRCI6IjI2OSIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MDYiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNjgiLCJkZXN0aW5hdGlvbklEIjoiMjY3IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTgwNyIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI2NyIsImRlc3RpbmF0aW9uSUQiOiIyNjYiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODA4IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjY1IiwiZGVzdGluYXRpb25JRCI6IjI2NCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MDkiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNjQiLCJkZXN0aW5hdGlvbklEIjoiMjYzIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTgxMCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI2MiIsImRlc3RpbmF0aW9uSUQiOiIyNjEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODExIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjYxIiwiZGVzdGluYXRpb25JRCI6IjI2MCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MTIiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNzMiLCJkZXN0aW5hdGlvbklEIjoiMjYyIiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjczXzE5NzBcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODEzIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjU3IiwiZGVzdGluYXRpb25JRCI6IjI1OCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MTQiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNTgiLCJkZXN0aW5hdGlvbklEIjoiMjU5IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTgxNSIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI3MyIsImRlc3RpbmF0aW9uSUQiOiIyNTciLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIyNzNfMTk3MlwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MTYiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNzMiLCJkZXN0aW5hdGlvbklEIjoiMjY1IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjczXzE5NjNcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODE3IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjczIiwiZGVzdGluYXRpb25JRCI6IjI2OCIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjI3M18xOTY0XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTgxOCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI3MyIsImRlc3RpbmF0aW9uSUQiOiIyNzAiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIyNzNfMTk2NVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MTkiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNzMiLCJkZXN0aW5hdGlvbklEIjoiMjcyIiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjczXzE5NjdcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODIwIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjU5IiwiZGVzdGluYXRpb25JRCI6IjI5MCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MjEiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNjAiLCJkZXN0aW5hdGlvbklEIjoiMjkwIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTgyMiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI2MyIsImRlc3RpbmF0aW9uSUQiOiIyOTAiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODIzIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjY2IiwiZGVzdGluYXRpb25JRCI6IjI5MCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MjQiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNjkiLCJkZXN0aW5hdGlvbklEIjoiMjkwIiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTgyNSIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI3MSIsImRlc3RpbmF0aW9uSUQiOiIyOTAiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODI2IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjk1IiwiZGVzdGluYXRpb25JRCI6IjI5MCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MjciLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyOTAiLCJkZXN0aW5hdGlvbklEIjoiMjc0IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjkwXzIwNzhcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODI4IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjkwIiwiZGVzdGluYXRpb25JRCI6IjI3NyIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjI5MF8yMDc2XCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTgyOSIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI5MCIsImRlc3RpbmF0aW9uSUQiOiIyODAiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIyOTBfMjA2OVwiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MzAiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyOTAiLCJkZXN0aW5hdGlvbklEIjoiMjgzIiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjkwXzIwNzBcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODMxIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjkwIiwiZGVzdGluYXRpb25JRCI6IjI4NiIsImNvbmRpdGlvbnMiOiJbe1wiaW50ZXJhY3Rpb25cIjpcIjI5MF8yMDcxXCIsXCJhY3Rpb25cIjpcImNsaWNrZWRcIn1dIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTgzMiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI5MCIsImRlc3RpbmF0aW9uSUQiOiIyODgiLCJjb25kaXRpb25zIjoiW3tcImludGVyYWN0aW9uXCI6XCIyOTBfMjA3M1wiLFwiYWN0aW9uXCI6XCJjbGlja2VkXCJ9XSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MzMiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNzQiLCJkZXN0aW5hdGlvbklEIjoiMjc1IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTgzNCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI3NSIsImRlc3RpbmF0aW9uSUQiOiIyNzYiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODM1IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjc3IiwiZGVzdGluYXRpb25JRCI6IjI3OCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MzYiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNzgiLCJkZXN0aW5hdGlvbklEIjoiMjc5IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTgzNyIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI4MCIsImRlc3RpbmF0aW9uSUQiOiIyODEiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODM4IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjgxIiwiZGVzdGluYXRpb25JRCI6IjI4MiIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4MzkiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyODMiLCJkZXN0aW5hdGlvbklEIjoiMjg0IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTg0MCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI4NCIsImRlc3RpbmF0aW9uSUQiOiIyODUiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODQxIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjg2IiwiZGVzdGluYXRpb25JRCI6IjI4NyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4NDIiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyODgiLCJkZXN0aW5hdGlvbklEIjoiMjg5IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTg0MyIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI4MyIsImRlc3RpbmF0aW9uSUQiOiIyOTYiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODQ0IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjk2IiwiZGVzdGluYXRpb25JRCI6IjE4OCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4NDUiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyODkiLCJkZXN0aW5hdGlvbklEIjoiMTg4IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTg0NiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI4NyIsImRlc3RpbmF0aW9uSUQiOiIxODgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODQ3IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjg1IiwiZGVzdGluYXRpb25JRCI6IjE4OCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4NDgiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyODIiLCJkZXN0aW5hdGlvbklEIjoiMTg4IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTg0OSIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI3OSIsImRlc3RpbmF0aW9uSUQiOiIxODgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODUwIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjc2IiwiZGVzdGluYXRpb25JRCI6IjE4OCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4NTEiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIxODgiLCJkZXN0aW5hdGlvbklEIjoiMTg1IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTg1MiIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjE4NSIsImRlc3RpbmF0aW9uSUQiOiIxODYiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODUzIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMTg2IiwiZGVzdGluYXRpb25JRCI6IjE4NyIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4NTQiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMDMiLCJkZXN0aW5hdGlvbklEIjoiMjkyIiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjAzXzE1NDJcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifSx7XCJpbnRlcmFjdGlvblwiOlwiMjAzXzE1NDBcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6Ik9SIn0seyJpZCI6Ijk4NTUiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMjMiLCJkZXN0aW5hdGlvbklEIjoiMjkzIiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjIzXzE2NTlcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifSx7XCJpbnRlcmFjdGlvblwiOlwiMjIzXzE2NTdcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6Ik9SIn0seyJpZCI6Ijk4NTYiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNDAiLCJkZXN0aW5hdGlvbklEIjoiMjk0IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjQwXzE3NjZcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifSx7XCJpbnRlcmFjdGlvblwiOlwiMjQwXzE3NjRcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6Ik9SIn0seyJpZCI6Ijk4NTciLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyNzMiLCJkZXN0aW5hdGlvbklEIjoiMjk1IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjczXzE5NjhcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifSx7XCJpbnRlcmFjdGlvblwiOlwiMjczXzE5NjZcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6Ik9SIn0seyJpZCI6Ijk4NTgiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyOTAiLCJkZXN0aW5hdGlvbklEIjoiMjk2IiwiY29uZGl0aW9ucyI6Ilt7XCJpbnRlcmFjdGlvblwiOlwiMjkwXzIwNzRcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifSx7XCJpbnRlcmFjdGlvblwiOlwiMjkwXzIwNzJcIixcImFjdGlvblwiOlwiY2xpY2tlZFwifV0iLCJvcGVyYXRvciI6Ik9SIn0seyJpZCI6Ijk4NTkiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyOTAiLCJkZXN0aW5hdGlvbklEIjoiMTg4IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTg2MCIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjI3MyIsImRlc3RpbmF0aW9uSUQiOiIxODgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODYxIiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMjQwIiwiZGVzdGluYXRpb25JRCI6IjE4OCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn0seyJpZCI6Ijk4NjIiLCJmb3JtSUQiOiI5Iiwib3JpZ2luSUQiOiIyMjMiLCJkZXN0aW5hdGlvbklEIjoiMTg4IiwiY29uZGl0aW9ucyI6IltdIiwib3BlcmF0b3IiOiIifSx7ImlkIjoiOTg2MyIsImZvcm1JRCI6IjkiLCJvcmlnaW5JRCI6IjIwMyIsImRlc3RpbmF0aW9uSUQiOiIxODgiLCJjb25kaXRpb25zIjoiW10iLCJvcGVyYXRvciI6IiJ9LHsiaWQiOiI5ODY0IiwiZm9ybUlEIjoiOSIsIm9yaWdpbklEIjoiMTg5IiwiZGVzdGluYXRpb25JRCI6IjE4OCIsImNvbmRpdGlvbnMiOiJbXSIsIm9wZXJhdG9yIjoiIn1dLCJjbG9zZV91cmwiOiIjIiwicmVkaXJlY3Rpb25zIjpbeyJpZCI6IjciLCJmb3JtSUQiOiI5IiwiY29uZGl0aW9ucyI6IltdIiwiY29uZGl0aW9uc09wZXJhdG9yIjoiIiwidXJsIjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vIn0seyJpZCI6IjgiLCJmb3JtSUQiOiI5IiwiY29uZGl0aW9ucyI6IltdIiwiY29uZGl0aW9uc09wZXJhdG9yIjoiIiwidXJsIjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vIn0seyJpZCI6IjkiLCJmb3JtSUQiOiI5IiwiY29uZGl0aW9ucyI6IltdIiwiY29uZGl0aW9uc09wZXJhdG9yIjoiIiwidXJsIjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vIn0seyJpZCI6IjEwIiwiZm9ybUlEIjoiOSIsImNvbmRpdGlvbnMiOiJbXSIsImNvbmRpdGlvbnNPcGVyYXRvciI6IiIsInVybCI6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tLyJ9LHsiaWQiOiIxMSIsImZvcm1JRCI6IjkiLCJjb25kaXRpb25zIjoiW10iLCJjb25kaXRpb25zT3BlcmF0b3IiOiIiLCJ1cmwiOiJodHRwczovL3d3dy5sb3djb3N0d2ViYWdlbmN5LmNvbS8ifSx7ImlkIjoiMTIiLCJmb3JtSUQiOiI5IiwiY29uZGl0aW9ucyI6IltdIiwiY29uZGl0aW9uc09wZXJhdG9yIjoiIiwidXJsIjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vIn1dLCJ1c2VSZWRpcmVjdGlvbkNvbmRpdGlvbnMiOiIwIiwidXNlUGRmIjoxLCJ0eHRfeWVzIjoiWWVzIiwidHh0X25vIjoiTm8iLCJ0eHRfbGFzdEJ0biI6IlN1Ym1pdCIsInR4dF9idG5TdGVwIjoiTmV4dCAiLCJkYXRlRm9ybWF0IjoiZCBNIHl5eXkiLCJkYXRlUGlja2VyTGFuZ3VhZ2UiOiIiLCJ0aG91c2FuZHNTZXBhcmF0b3IiOiIiLCJkZWNpbWFsc1NlcGFyYXRvciI6Ii4iLCJtaWxsaW9uU2VwYXJhdG9yIjoiIiwiYmlsbGlvbnNTZXBhcmF0b3IiOiIiLCJzdW1tYXJ5X2hpZGVRdCI6IjEiLCJzdW1tYXJ5X2hpZGVaZXJvIjoiMSIsInN1bW1hcnlfaGlkZVplcm9RdCI6IjEiLCJzdW1tYXJ5X2hpZGVQcmljZXMiOiIxIiwic3VtbWFyeV9oaWRlWmVyb0RlY2ltYWxzIjoiMSIsImdyb3VwQXV0b0NsaWNrIjoiMSIsImZpbGVzVXBsb2FkX3RleHQiOiJEcm9wIGZpbGVzIGhlcmUgdG8gdXBsb2FkIiwiZmlsZXNVcGxvYWRTaXplX3RleHQiOiJGaWxlIGlzIHRvbyBiaWcgKG1heCBzaXplOiB7e21heEZpbGVzaXplfX1NQikiLCJmaWxlc1VwbG9hZFR5cGVfdGV4dCI6IkludmFsaWQgZmlsZSB0eXBlIiwiZmlsZXNVcGxvYWRMaW1pdF90ZXh0IjoiWW91IGNhbiBub3QgdXBsb2FkIGFueSBtb3JlIGZpbGVzIiwic2VuZENvbnRhY3RBU0FQIjoiMSIsInNob3dUb3RhbEJvdHRvbSI6IjAiLCJzdHJpcGVQdWJLZXkiOiIiLCJzY3JvbGxUb3BNYXJnaW4iOiIwIiwic2Nyb2xsVG9wTWFyZ2luTW9iaWxlIjoiMCIsInJlZGlyZWN0aW9uRGVsYXkiOiIwIiwiZ21hcF9rZXkiOiIiLCJ0eHREaXN0YW5jZUVycm9yIjoiQ2FsY3VsYXRpbmcgdGhlIGRpc3RhbmNlIGNvdWxkIG5vdCBiZSBwZXJmb3JtZWQsIHBsZWFzZSB2ZXJpZnkgdGhlIGlucHV0IGFkZHJlc3NlcyIsImNhcHRjaGFVcmwiOiJodHRwczovL3d3dy5sb3djb3N0d2ViYWdlbmN5LmNvbS93cC1jb250ZW50L3BsdWdpbnMvV1BfRXN0aW1hdGlvbl9Gb3JtL2luY2x1ZGVzL2NhcHRjaGEvZ2V0X2NhcHRjaGEucGhwIiwic3VtbWFyeV9ub0RlY2ltYWxzIjoiMSIsInNjcm9sbFRvcFBhZ2UiOiIwIiwiZGlzYWJsZURyb3Bkb3ducyI6IjEiLCJpbWdJY29uU3R5bGUiOiJ6b29tIiwic3VtbWFyeV9oaWRlRmluYWxTdGVwIjoiMSIsInRpbWVNb2RlQU0iOiIwIiwiZW5hYmxlU2hpbmVGeEJ0biI6IjEiLCJzdW1tYXJ5X3Nob3dBbGxQcmljZXNFbWFpbCI6IjAiLCJpbWdUaXRsZXNTdHlsZSI6IiIsImxhc3RTIjoiMTY2NTQ3Nzg4Mzk5MyIsImVtcHR5V29vQ2FydCI6IjAiLCJzZW5kVXJsVmFyaWFibGVzIjoiMCIsInNlbmRWYXJpYWJsZXNNZXRob2QiOiIiLCJlbmFibGVaYXBpZXIiOiIwIiwiemFwaWVyV2ViSG9vayI6IiIsInN1bW1hcnlfc2hvd0Rlc2NyaXB0aW9ucyI6IjEiLCJpbWdQcmV2aWV3IjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vd3AtY29udGVudC9wbHVnaW5zL1dQX0VzdGltYXRpb25fRm9ybS9hc3NldHMvaW1nL2ZpbGUtMy0xMjgucG5nIiwicHJvZ3Jlc3NCYXJQcmljZVR5cGUiOiIiLCJyYXpvcnBheV9wdWJsaXNoS2V5IjoiIiwicmF6b3JwYXlfbG9nb0ltZyI6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tL3dwLWNvbnRlbnQvdXBsb2Fkcy8yMDIyLzEwL2NyZWRpdENhcmRAMngucG5nIiwidmFyaWFibGVzIjpbXSwidXNlRW1haWxWZXJpZmljYXRpb24iOiIwIiwidHh0X2VtYWlsQWN0aXZhdGlvbkNvZGUiOiJGaWxsIHlvdXIgdmVyaWZpYXRpb24gY29kZSBoZXJlIiwidHh0X2VtYWlsQWN0aXZhdGlvbkluZm8iOiJBIHVuaXF1ZSB2ZXJpZmljYXRpb24gY29kZSBoYXMganVzdCBiZWVuIHNlbnQgdG8geW91IGJ5IGVtYWlsLCBwbGVhc2UgY29weSBpdCBpbiB0aGUgZmllbGQgYmVsb3cgdG8gdmFsaWRhdGUgeW91ciBlbWFpbCBhZGRyZXNzLiIsInVzZUNhcHRjaGEiOiIwIiwicmVjYXB0Y2hhM0tleSI6IiIsImRpc3RhbmNlc01vZGUiOiJyb3V0ZSIsImVuYWJsZUN1c3RvbWVyQWNjb3VudCI6IjAiLCJ0eHRDdXN0b21lcnNEYXRhRm9yZ290UGFzc1NlbnQiOiIiLCJ0eHRDdXN0b21lcnNEYXRhRm9yZ290UGFzc0xpbmsiOiIiLCJlbWFpbEN1c3RvbWVyTGlua3MiOiIxIiwiZW5hYmxlUGRmRG93bmxvYWQiOiIxIiwidXNlU2lnbmF0dXJlIjoiMCIsInVzZVZBVCI6IjAiLCJ2YXRBbW91bnQiOiIyMCIsInZhdExhYmVsIjoiVkFUIiwiYXV0b2Nsb3NlRGF0ZXBpY2tlciI6IjAiLCJmbG9hdFN1bW1hcnlfc2hvd0luZm8iOiIxIiwiaGlkZUZpbmFsYnRuIjoiMCIsImNhcnRQYWdlIjoiIiwiZGlzYWJsZVNjcm9sbCI6IjAifV0=" defer></script>
<script data-optimized="1" id="lfb_frontend-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/5c752d5e3cc9177fc9f2089b272f6953.js?ver=e2f1b" defer data-deferred="1"></script>
<script id="wc-cashfree-checkout-js-js" defer data-deferred="1" data-type="lazy" data-src="https://sdk.cashfree.com/js/v3/cashfree.js?ver=4.8.1"></script>
<script data-optimized="1" id="wc-cashfree-checkout-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/5f4daa15f48fb910879c5b1559eb3ddf.js?ver=39a39" defer data-deferred="1"></script>
<script data-optimized="1" id="swv-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/5c4746a16ccf2a303e2c2c557c3c7f76.js?ver=9d723"></script>
<script id="contact-form-7-js-before" src="data:text/javascript;base64,dmFyIHdwY2Y3PXsiYXBpIjp7InJvb3QiOiJodHRwczpcL1wvd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tXC93cC1qc29uXC8iLCJuYW1lc3BhY2UiOiJjb250YWN0LWZvcm0tN1wvdjEifSwiY2FjaGVkIjoxfQ==" defer></script>
<script data-optimized="1" id="contact-form-7-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/cd0cd797ad2fba059531badb3e355fa3.js?ver=00ef2"></script>
<script data-optimized="1" id="nbcpf-intlTelInput-script-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/330de25c30a33ebaf65f95c4ad2085f1.js?ver=4f662"></script>
<script id="nbcpf-countryFlag-script-js-extra" src="data:text/javascript;base64,dmFyIG5iY3BmPXsiYWpheHVybCI6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tL3dwLWFkbWluL2FkbWluLWFqYXgucGhwIn0=" defer></script>
<script data-optimized="1" id="nbcpf-countryFlag-script-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/993b5808baa02386ce86789f7da94679.js?ver=2db17"></script>
<script id="nbcpf-countryFlag-script-js-after" src="data:text/javascript;base64,KGZ1bmN0aW9uKCQpeyQoZnVuY3Rpb24oKXskKCIud3BjZjctY291bnRyeXRleHQiKS5jb3VudHJ5U2VsZWN0KHt9KTskKCIud3BjZjctcGhvbmV0ZXh0IikuaW50bFRlbElucHV0KHthdXRvSGlkZURpYWxDb2RlOiEwLGF1dG9QbGFjZWhvbGRlcjohMCxuYXRpb25hbE1vZGU6ITEsc2VwYXJhdGVEaWFsQ29kZTohMCxoaWRkZW5JbnB1dDoiZnVsbF9udW1iZXIiLH0pOyQoIi53cGNmNy1waG9uZXRleHQiKS5lYWNoKGZ1bmN0aW9uKCl7dmFyIGhpZGRlbklucHV0PSQodGhpcykuYXR0cignbmFtZScpO3ZhciBkaWFsX2NvZGU9JCh0aGlzKS5zaWJsaW5ncygiLmZsYWctY29udGFpbmVyIikuZmluZCgiLnNlbGVjdGVkLWZsYWcgLnNlbGVjdGVkLWRpYWwtY29kZSIpLnRleHQoKTskKCJpbnB1dFtuYW1lPSIraGlkZGVuSW5wdXQrIi1jb3VudHJ5LWNvZGVdIikudmFsKGRpYWxfY29kZSl9KTskKCIud3BjZjctcGhvbmV0ZXh0Iikub24oImNvdW50cnljaGFuZ2UiLGZ1bmN0aW9uKCl7dmFyIGhpZGRlbklucHV0PSQodGhpcykuYXR0cigibmFtZSIpO3ZhciBkaWFsX2NvZGU9JCh0aGlzKS5zaWJsaW5ncygiLmZsYWctY29udGFpbmVyIikuZmluZCgiLnNlbGVjdGVkLWZsYWcgLnNlbGVjdGVkLWRpYWwtY29kZSIpLnRleHQoKTskKCJpbnB1dFtuYW1lPSIraGlkZGVuSW5wdXQrIi1jb3VudHJ5LWNvZGVdIikudmFsKGRpYWxfY29kZSl9KTt2YXIgaXNNb2JpbGU9L0FuZHJvaWQuK01vYmlsZXx3ZWJPU3xpUGhvbmV8aVBvZHxCbGFja0JlcnJ5fElFTW9iaWxlfE9wZXJhIE1pbmkvaS50ZXN0KG5hdmlnYXRvci51c2VyQWdlbnQpOyQoIi53cGNmNy1waG9uZXRleHQiKS5vbigia2V5dXAiLGZ1bmN0aW9uKCl7dmFyIGRpYWxfY29kZT0kKHRoaXMpLnNpYmxpbmdzKCIuZmxhZy1jb250YWluZXIiKS5maW5kKCIuc2VsZWN0ZWQtZmxhZyAuc2VsZWN0ZWQtZGlhbC1jb2RlIikudGV4dCgpO3ZhciB2YWx1ZT0kKHRoaXMpLnZhbCgpO2lmKHZhbHVlPT0iKyIpCiQodGhpcykudmFsKCIiKTtlbHNlIGlmKHZhbHVlLmluZGV4T2YoIisiKT09Ii0xIikKJCh0aGlzKS52YWwoZGlhbF9jb2RlK3ZhbHVlKTtlbHNlIGlmKHZhbHVlLmluZGV4T2YoIisiKT4wKQokKHRoaXMpLnZhbChkaWFsX2NvZGUrdmFsdWUuc3Vic3RyaW5nKGRpYWxfY29kZS5sZW5ndGgpKTt9KTskKCIud3BjZjctY291bnRyeXRleHQiKS5vbigia2V5dXAiLGZ1bmN0aW9uKCl7dmFyIGNvdW50cnlfbmFtZT0kKHRoaXMpLnNpYmxpbmdzKCIuZmxhZy1kcm9wZG93biIpLmZpbmQoIi5jb3VudHJ5LWxpc3QgbGkuYWN0aXZlIHNwYW4uY291bnRyeS1uYW1lIikudGV4dCgpO2lmKGNvdW50cnlfbmFtZT09IiIpCnZhciBjb3VudHJ5X25hbWU9JCh0aGlzKS5zaWJsaW5ncygiLmZsYWctZHJvcGRvd24iKS5maW5kKCIuY291bnRyeS1saXN0IGxpLmhpZ2hsaWdodCBzcGFuLmNvdW50cnktbmFtZSIpLnRleHQoKTt2YXIgdmFsdWU9JCh0aGlzKS52YWwoKTskKHRoaXMpLnZhbChjb3VudHJ5X25hbWUrdmFsdWUuc3Vic3RyaW5nKGNvdW50cnlfbmFtZS5sZW5ndGgpKX0pfSl9KShqUXVlcnkp" defer></script>
<script id="eafl-public-js-extra" src="data:text/javascript;base64,dmFyIGVhZmxfcHVibGljPXsiaG9tZV91cmwiOiJodHRwczovL3d3dy5sb3djb3N0d2ViYWdlbmN5LmNvbS8iLCJhamF4X3VybCI6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tL3dwLWFkbWluL2FkbWluLWFqYXgucGhwIiwibm9uY2UiOiI1NTA0NTc5ZmNiIn0=" defer></script>
<script data-optimized="1" id="eafl-public-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/72af9615f1bafb83a19f2c55bcb11008.js?ver=19bb9" defer data-deferred="1"></script>
<script data-optimized="1" id="underscore-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/656105ac6520e78e77d412aa1c9fdf5b.js?ver=0c53b" defer data-deferred="1"></script>
<script id="paypalplus-woocommerce-front-js-extra" src="data:text/javascript;base64,dmFyIHBwcEZyb250RGF0YUNvbGxlY3Rpb249eyJwYWdlaW5mbyI6eyJpc0NoZWNrb3V0IjohMSwiaXNDaGVja291dFBheVBhZ2UiOiExfSwiaXNDb25mbGljdFZlcnNpb24iOiIxIn0=" defer></script>
<script data-optimized="1" id="paypalplus-woocommerce-front-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/4d1068c96f7149addfc7f137ec517523.js?ver=85722" defer data-deferred="1"></script>
<script data-wp-strategy="async" id="cloudflare-turnstile-js" src="https://challenges.cloudflare.com/turnstile/v0/api.js"></script>
<script id="cloudflare-turnstile-js-after">
document.addEventListener( 'wpcf7submit', e => turnstile.reset() );
//# sourceURL=cloudflare-turnstile-js-after
</script>
<script id="daim-track-internal-links-js-before" src="data:text/javascript;base64,d2luZG93LkRBSU1fUEFSQU1FVEVSUz17YWpheF91cmw6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tL3dwLWFkbWluL2FkbWluLWFqYXgucGhwIixub25jZToiMjJlNzk3YmQ3YyJ9" defer></script>
<script data-optimized="1" id="daim-track-internal-links-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/6d01a6d028937b48180b1df8c62a5866.js?ver=90e80" defer data-deferred="1"></script>
<script data-optimized="1" data-wp-strategy="async" fetchpriority="low" id="comment-reply-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/30a5403410fa872b31989258af99a153.js?ver=1837e" defer data-deferred="1"></script>
<script id="cart-widget-js-extra" src="data:text/javascript;base64,dmFyIGFjdGlvbnM9eyJjdXJyZW50X2xhbmd1YWdlIjoiZW4iLCJmb3JjZV9yZXNldCI6IjAifQ==" defer></script>
<script data-optimized="1" data-wp-strategy="defer" defer id="cart-widget-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/b32ffb8fe1ef1b215581be0b17529bf4.js?ver=188b1"></script>
<script data-optimized="1" id="page-links-to-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/931848cb939a1246e892f804bed5222f.js?ver=abe0c" defer data-deferred="1"></script>
<script data-optimized="1" id="sourcebuster-js-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/33af9a69764a66dda4604a4bf93d71c5.js?ver=780b6" defer data-deferred="1"></script>
<script id="wc-order-attribution-js-extra" src="data:text/javascript;base64,dmFyIHdjX29yZGVyX2F0dHJpYnV0aW9uPXsicGFyYW1zIjp7ImxpZmV0aW1lIjoxLjBlLTUsInNlc3Npb24iOjMwLCJiYXNlNjQiOiExLCJhamF4dXJsIjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vd3AtYWRtaW4vYWRtaW4tYWpheC5waHAiLCJwcmVmaXgiOiJ3Y19vcmRlcl9hdHRyaWJ1dGlvbl8iLCJhbGxvd1RyYWNraW5nIjohMH0sImZpZWxkcyI6eyJzb3VyY2VfdHlwZSI6ImN1cnJlbnQudHlwIiwicmVmZXJyZXIiOiJjdXJyZW50X2FkZC5yZiIsInV0bV9jYW1wYWlnbiI6ImN1cnJlbnQuY21wIiwidXRtX3NvdXJjZSI6ImN1cnJlbnQuc3JjIiwidXRtX21lZGl1bSI6ImN1cnJlbnQubWRtIiwidXRtX2NvbnRlbnQiOiJjdXJyZW50LmNudCIsInV0bV9pZCI6ImN1cnJlbnQuaWQiLCJ1dG1fdGVybSI6ImN1cnJlbnQudHJtIiwidXRtX3NvdXJjZV9wbGF0Zm9ybSI6ImN1cnJlbnQucGx0IiwidXRtX2NyZWF0aXZlX2Zvcm1hdCI6ImN1cnJlbnQuZm10IiwidXRtX21hcmtldGluZ190YWN0aWMiOiJjdXJyZW50LnRjdCIsInNlc3Npb25fZW50cnkiOiJjdXJyZW50X2FkZC5lcCIsInNlc3Npb25fc3RhcnRfdGltZSI6ImN1cnJlbnRfYWRkLmZkIiwic2Vzc2lvbl9wYWdlcyI6InNlc3Npb24ucGdzIiwic2Vzc2lvbl9jb3VudCI6InVkYXRhLnZzdCIsInVzZXJfYWdlbnQiOiJ1ZGF0YS51YWcifX0=" defer></script>
<script id="wc-order-attribution-js" src="https://www.lowcostwebagency.com/wp-content/plugins/woocommerce/assets/js/frontend/order-attribution.min.js?ver=11.2.1" defer data-deferred="1"></script>
<script data-optimized="1" id="backbone-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/4f41f71788dbefe3fb7cf9f6b9d59b7c.js?ver=2e6ab" defer data-deferred="1"></script>
<script data-optimized="1" id="backbone.localStorage-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/66d95051c677839d60ceca75f6e17adb.js?ver=54627" defer data-deferred="1"></script>
<script data-optimized="1" id="wc-predictive-search-autocomplete-script-js" defer data-deferred="1" data-type="lazy" data-src="https://www.lowcostwebagency.com/wp-content/litespeed/js/2d67b5bd7ea86fa8800d159f92f51b16.js?ver=e81f0"></script>
<script data-optimized="1" id="wc-predictive-search-backbone-js" defer data-deferred="1" data-type="lazy" data-src="https://www.lowcostwebagency.com/wp-content/litespeed/js/28ceb0cade6f6a1c3c502d50abe6fcbb.js?ver=66e0a"></script>
<script id="wc-predictive-search-popup-backbone-js-extra" defer data-type="lazy" data-src="data:text/javascript;base64,dmFyIHdjX3BzX3ZhcnM9eyJtaW5DaGFycyI6IjEiLCJkZWxheSI6IjYwMCIsImNhY2hlX3RpbWVvdXQiOiIxIiwiaXNfZGVidWciOiJ5ZXMiLCJsZWdhY3lfYXBpX3VybCI6Ii8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tL3djLWFwaS93Y19wc19sZWdhY3lfYXBpLz9hY3Rpb249Z2V0X3Jlc3VsdF9wb3B1cCIsInNlYXJjaF9wYWdlX3VybCI6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tL3NlYXJjaC8iLCJwZXJtYWxpbmtfc3RydWN0dXJlIjoiLyVwb3N0bmFtZSUvIiwiaXNfcnRsIjoiIn0="></script>
<script data-optimized="1" id="wc-predictive-search-popup-backbone-js" defer data-deferred="1" data-type="lazy" data-src="https://www.lowcostwebagency.com/wp-content/litespeed/js/d12c9de4ced65974cbd788b88f8c2d8b.js?ver=11c6d"></script>
<script id="quick-view-popup-script-js-extra" src="data:text/javascript;base64,dmFyIHdjX3F2X3ZhcnM9eyJhamF4X3VybCI6Ii93cC1hZG1pbi9hZG1pbi1hamF4LnBocCJ9" defer></script>
<script data-optimized="1" id="quick-view-popup-script-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/f12aca297f2405c74d6f21c8f03a6504.js?ver=65ef2" defer data-deferred="1"></script>
<script id="wpcf7cf-scripts-js-extra" src="data:text/javascript;base64,dmFyIHdwY2Y3Y2ZfZ2xvYmFsX3NldHRpbmdzPXsiYWpheHVybCI6Imh0dHBzOi8vd3d3Lmxvd2Nvc3R3ZWJhZ2VuY3kuY29tL3dwLWFkbWluL2FkbWluLWFqYXgucGhwIn0=" defer></script>
<script data-optimized="1" id="wpcf7cf-scripts-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/f425293af6a8f84ad6e449675dc73a3b.js?ver=a6647" defer data-deferred="1"></script>
<script data-cfasync="false" id="cfturnstile-js-before">
(function(w,d){var q=w.cfturnstileQueue=w.cfturnstileQueue||[];if(w.cfturnstileRender)return;var ready=false,hooked=false,ticks=0,timer=null;var cbs=["callback","error-callback","expired-callback","timeout-callback","unsupported-callback","before-interactive-callback","after-interactive-callback"];function opts(e){var p={};for(var i=0;i<cbs.length;i++){(function(n){var v=e.getAttribute("data-"+n);if(!v)return;p[n]=function(){var f=w[v];if(typeof f==="function")return f.apply(w,arguments);};})(cbs[i]);}return p;}w.cfturnstileOpts=function(e){if(typeof e==="string")e=d.querySelector(e);return e&&e.getAttribute?opts(e):{};};function one(id){var n="cf-turnstile"+id,e=d.getElementById(n);if(e&&e.cfturnstileQueued){e=null;var l=d.querySelectorAll(".cf-turnstile");for(var i=0;i<l.length;i++){if(l[i].id===n&&!l[i].cfturnstileQueued){e=l[i];break;}}}if(!e)return false;if(!e.firstElementChild){try{w.turnstile.render(e,opts(e));}catch(_){return false;}}e.cfturnstileQueued=1;return true;}function drain(){if(!ready)return;for(var i=q.length-1;i>=0;i--){if(one(q[i]))q.splice(i,1);}if(q.length&&!hooked&&d.readyState==="loading"){hooked=true;d.addEventListener("DOMContentLoaded",function(){hooked=false;drain();});}}function watch(){timer=null;if(!q.length)return;if(!ready&&w.turnstile&&typeof w.turnstile.render==="function")ready=true;drain();if(q.length&&++ticks<170)timer=setTimeout(watch,ticks<20?100:2000);}w.cfturnstileRender=function(){drain();if(q.length&&!timer)timer=setTimeout(watch,100);};w.cfturnstileOnload=function(){ready=true;w.cfturnstileRender();};w.cfturnstileRender();})(window,document);
(function(w,d){if(w.cfturnstileRefresh)return;w.cfturnstileRefresh=1;var F="input[name=cf-turnstile-response]",S="form.checkout, form.woocommerce-checkout, form.wc-block-checkout__form",u=false;function go(){u=true;}w.addEventListener("pagehide",go);w.addEventListener("beforeunload",go);d.addEventListener("submit",function(e){var f=e.target,s=[];if(!f||!f.querySelectorAll)return;try{if(S&&f.matches&&f.matches(S))return;}catch(_){}f.querySelectorAll(".cf-turnstile").forEach(function(el){var i=el.querySelector(F);if(i&&i.value)s.push([el,i.value]);});if(!s.length)return;setTimeout(function(){if(u||!w.turnstile||d.querySelector("#wfls-prompt-overlay,#wfls-token,#fls_2fa_form,.fls_2fs"))return;s.forEach(function(x){var i=x[0].querySelector(F);if(i&&i.value===x[1]){try{w.turnstile.reset(x[0]);}catch(_){}}});},2000);},true);})(window,document);
//# sourceURL=cfturnstile-js-before
</script>
<script id="cfturnstile-js" src="https://challenges.cloudflare.com/turnstile/v0/api.js?render=explicit&onload=cfturnstileOnload"></script>
<script data-cfasync="false" id="cfturnstile-js-after">
function turnstileCF7Callback() {
document.querySelectorAll('.wpcf7-submit').forEach(function(el) {
el.style.pointerEvents = 'auto';
el.style.opacity = '1';
});
}
//# sourceURL=cfturnstile-js-after
</script>
<script id="cfturnstile-js-js" src="https://www.lowcostwebagency.com/wp-content/plugins/simple-cloudflare-turnstile/js/disable-submit.js?ver=5.3"></script>
<script data-optimized="1" id="react-jsx-runtime-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/09d93c2c5be72e7a3fed7907b0c459ae.js?ver=25c38" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-deprecated-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/a572d0e79161dad01d3707f87f7ba723.js?ver=37a1b" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-dom-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/98ccef882ba8a3be5661723ab8b7dd51.js?ver=3392f" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-is-shallow-equal-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/0bd3a4bc3720e0ec30ebad3d32827068.js?ver=a184e" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-keycodes-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/2927d2da040f2068c3cbd993b0f55145.js?ver=655a1" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-priority-queue-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/51bb0191b650ef22716f1eaf4c8554e7.js?ver=14b9d" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-private-apis-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/495f9a7e99b9c301e8e31f1a5dc4d250.js?ver=71beb" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-undo-manager-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/d0df5071163c01073456e9b251e45001.js?ver=4514b" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-compose-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/81117f563da4dfc95496dba8b863bca7.js?ver=36fc0" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-redux-routine-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/9e9c3f9d09f508e1cac1ecc7a68a34b7.js?ver=54a51" defer data-deferred="1"></script>
<script data-optimized="1" id="wp-data-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/415b285dcba0872c0ec639161c17c80a.js?ver=ced99" defer data-deferred="1"></script>
<script id="wp-data-js-after" src="data:text/javascript;base64,KGZ1bmN0aW9uKCl7dmFyIHVzZXJJZD0wO3ZhciBzdG9yYWdlS2V5PSJXUF9EQVRBX1VTRVJfIit1c2VySWQ7d3AuZGF0YS51c2Uod3AuZGF0YS5wbHVnaW5zLnBlcnNpc3RlbmNlLHtzdG9yYWdlS2V5OnN0b3JhZ2VLZXl9KX0pKCk=" defer></script>
<script id="cfturnstile-woo-js-js" src="https://www.lowcostwebagency.com/wp-content/plugins/simple-cloudflare-turnstile/js/integrations/woocommerce.js?ver=2.2"></script>
<script data-cfasync="false" id="cfturnstile-render-js-after">
(window.cfturnstileQueue=window.cfturnstileQueue||[]).push("-cf7-1037331612");if(window.cfturnstileRender)window.cfturnstileRender();
//# sourceURL=cfturnstile-render-js-after
</script>
<script data-optimized="1" id="gsap-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/fb56464d155d0d850b928f04635dbe45.js?ver=340a8" defer data-deferred="1"></script>
<script data-optimized="1" id="gsap-scroll-trigger-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/8a578a608a8a925086d309c93f3bc9f5.js?ver=862ad" defer data-deferred="1"></script>
<script data-optimized="1" id="awb-tabs-widget-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/ee29fb7c9a47d6c1e1f7be2d5a3c1f40.js?ver=f4c32" defer data-deferred="1"></script>
<script data-optimized="1" id="awb-vertical-menu-widget-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/07bd413d4338894ab9180be6356f7ac5.js?ver=683fd" defer data-deferred="1"></script>
<script data-optimized="1" id="cssua-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/c0c29014335ca5324de497cb5141ec7d.js?ver=5e56e" defer data-deferred="1"></script>
<script data-optimized="1" id="modernizr-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/3b045c0f957ec59627aa7d85ef01b2b3.js?ver=9171b" defer data-deferred="1"></script>
<script id="fusion-js-extra" src="data:text/javascript;base64,dmFyIGZ1c2lvbkpTVmFycz17InZpc2liaWxpdHlfc21hbGwiOiI2NDAiLCJ2aXNpYmlsaXR5X21lZGl1bSI6IjEwMjQifQ==" defer></script>
<script data-optimized="1" id="fusion-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/1eed82425cbd4ccf118f66e1ce36750e.js?ver=86d3e" defer data-deferred="1"></script>
<script data-optimized="1" id="swiper-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/3ba1f9981e2239364bb394dfd7ba96cb.js?ver=50bb6" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-request-animation-frame-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/2329bdfa0b2709536e7fee09b0aae0a3.js?ver=69a97" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-easing-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/8f2687d7e18eb14d70271cadbad42166.js?ver=042c9" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-fitvids-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/16dacc24bf6d2661745b81e6fc260541.js?ver=15fc2" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-flexslider-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/364a2eb5d2c0c69c1698b6cf523065c2.js?ver=34ca4" defer data-deferred="1"></script>
<script id="jquery-lightbox-js-extra" src="data:text/javascript;base64,dmFyIGZ1c2lvbkxpZ2h0Ym94VmlkZW9WYXJzPXsibGlnaHRib3hfdmlkZW9fd2lkdGgiOiIxMjgwIiwibGlnaHRib3hfdmlkZW9faGVpZ2h0IjoiNzIwIn0=" defer></script>
<script data-optimized="1" id="jquery-lightbox-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/12ed22fe016348b849b9978c5ff87793.js?ver=40104" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-mousewheel-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/6a1f843c9c785a2d996ae87226862921.js?ver=0850c" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-fade-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/da17fab4f6c9ef23e4430a9de3556a65.js?ver=33352" defer data-deferred="1"></script>
<script id="fusion-equal-heights-js-extra" src="data:text/javascript;base64,dmFyIGZ1c2lvbkVxdWFsSGVpZ2h0VmFycz17ImNvbnRlbnRfYnJlYWtfcG9pbnQiOiI4MDAifQ==" defer></script>
<script data-optimized="1" id="fusion-equal-heights-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/03d955b96d3f3def89ce3c76d088727e.js?ver=7a5ce" defer data-deferred="1"></script>
<script data-optimized="1" id="fusion-parallax-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/e07bcd5d79541b80af6318dc68a3d6d8.js?ver=3fd9d" defer data-deferred="1"></script>
<script id="fusion-video-general-js-extra" src="data:text/javascript;base64,dmFyIGZ1c2lvblZpZGVvR2VuZXJhbFZhcnM9eyJzdGF0dXNfdmltZW8iOiIwIiwic3RhdHVzX3l0IjoiMCJ9" defer></script>
<script data-optimized="1" id="fusion-video-general-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/61646f92dd9072f96d8be7b0509deb12.js?ver=3c4df" defer data-deferred="1"></script>
<script id="fusion-video-bg-js-extra" src="data:text/javascript;base64,dmFyIGZ1c2lvblZpZGVvQmdWYXJzPXsic3RhdHVzX3ZpbWVvIjoiMCIsInN0YXR1c195dCI6IjAiLCJ0aXRsZSI6IkJhY2tncm91bmQgdmlkZW8ifQ==" defer></script>
<script data-optimized="1" id="fusion-video-bg-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/d7aba9106308a658d02b124c3e80c575.js?ver=b2d86" defer data-deferred="1"></script>
<script id="fusion-lightbox-js-extra" src="data:text/javascript;base64,dmFyIGZ1c2lvbkxpZ2h0Ym94VmFycz17InN0YXR1c19saWdodGJveCI6IjEiLCJsaWdodGJveF9nYWxsZXJ5IjoiMSIsImxpZ2h0Ym94X3NraW4iOiJtZXRyby13aGl0ZSIsImxpZ2h0Ym94X3RpdGxlIjoiIiwibGlnaHRib3hfem9vbSI6IjEuMDAiLCJsaWdodGJveF9hcnJvd3MiOiIxIiwibGlnaHRib3hfc2xpZGVzaG93X3NwZWVkIjoiNTAwMCIsImxpZ2h0Ym94X2xvb3AiOiIwIiwibGlnaHRib3hfYXV0b3BsYXkiOiIiLCJsaWdodGJveF9vcGFjaXR5IjoiMC45NyIsImxpZ2h0Ym94X2Rlc2MiOiIiLCJsaWdodGJveF9zb2NpYWwiOiIxIiwibGlnaHRib3hfc29jaWFsX2xpbmtzIjp7ImZhY2Vib29rIjp7InNvdXJjZSI6Imh0dHBzOi8vd3d3LmZhY2Vib29rLmNvbS9zaGFyZXIucGhwP3U9e1VSTH0iLCJ0ZXh0IjoiU2hhcmUgb24gRmFjZWJvb2sifSwidHdpdHRlciI6eyJzb3VyY2UiOiJodHRwczovL3guY29tL2ludGVudC9wb3N0P3VybD17VVJMfSIsInRleHQiOiJTaGFyZSBvbiBYIn0sInJlZGRpdCI6eyJzb3VyY2UiOiJodHRwczovL3JlZGRpdC5jb20vc3VibWl0P3VybD17VVJMfSIsInRleHQiOiJTaGFyZSBvbiBSZWRkaXQifSwibGlua2VkaW4iOnsic291cmNlIjoiaHR0cHM6Ly93d3cubGlua2VkaW4uY29tL3NoYXJpbmcvc2hhcmUtb2Zmc2l0ZS8/dXJsPXtVUkx9IiwidGV4dCI6IlNoYXJlIG9uIExpbmtlZEluIn0sInR1bWJsciI6eyJzb3VyY2UiOiJodHRwczovL3d3dy50dW1ibHIuY29tL3NoYXJlL2xpbms/dXJsPXtVUkx9IiwidGV4dCI6IlNoYXJlIG9uIFR1bWJsciJ9LCJwaW50ZXJlc3QiOnsic291cmNlIjoiaHR0cHM6Ly9waW50ZXJlc3QuY29tL3Bpbi9jcmVhdGUvYnV0dG9uLz91cmw9e1VSTH0iLCJ0ZXh0IjoiU2hhcmUgb24gUGludGVyZXN0In19LCJsaWdodGJveF9kZWVwbGlua2luZyI6IjEiLCJsaWdodGJveF9wYXRoIjoiaG9yaXpvbnRhbCIsImxpZ2h0Ym94X3Bvc3RfaW1hZ2VzIjoiIiwibGlnaHRib3hfYW5pbWF0aW9uX3NwZWVkIjoiZmFzdCIsImwxMG4iOnsiY2xvc2UiOiJQcmVzcyBFc2MgdG8gY2xvc2UiLCJlbnRlckZ1bGxzY3JlZW4iOiJFbnRlciBGdWxsc2NyZWVuIChTaGlmdCtFbnRlcikiLCJleGl0RnVsbHNjcmVlbiI6IkV4aXQgRnVsbHNjcmVlbiAoU2hpZnQrRW50ZXIpIiwic2xpZGVTaG93IjoiU2xpZGVzaG93IiwibmV4dCI6Ik5leHQiLCJwcmV2aW91cyI6IlByZXZpb3VzIn19" defer></script>
<script data-optimized="1" id="fusion-lightbox-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/e05c6b1d06f825187c78b387915ad28d.js?ver=48219" defer data-deferred="1"></script>
<script data-optimized="1" id="jquery-sticky-kit-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/ab3b872e652a347008df3d19d35da2a5.js?ver=34afe" defer data-deferred="1"></script>
<script data-optimized="1" id="fusion-general-global-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/e2eb9de8358f959e1a2e711ba040ec86.js?ver=2ae7c" defer data-deferred="1"></script>
<script data-optimized="1" id="avada-woo-product-variations-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/6adb6e52684749ed6821450688ce6bf9.js?ver=91729" defer data-deferred="1"></script>
<script data-optimized="1" id="avada-general-footer-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/38b622b0a7c1cc843f3175256787cee9.js?ver=7f4d4" defer data-deferred="1"></script>
<script data-optimized="1" id="avada-quantity-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/ba8256d54aa719dc57693c04a591fe35.js?ver=52d1a" defer data-deferred="1"></script>
<script data-optimized="1" id="avada-crossfade-images-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/0333df7e7dcecf98df78d292e6a00dc6.js?ver=134a0" defer data-deferred="1"></script>
<script data-optimized="1" id="avada-select-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/eae4a86f42b893c891c99f72671a0bf6.js?ver=18e3e" defer data-deferred="1"></script>
<script id="avada-wpml-js-extra" src="data:text/javascript;base64,dmFyIGF2YWRhTGFuZ3VhZ2VWYXJzPXsibGFuZ3VhZ2VfZmxhZyI6ImVuIn0=" defer></script>
<script data-optimized="1" id="avada-wpml-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/81d87e1916421000a4d0e256c77cd38e.js?ver=95348" defer data-deferred="1"></script>
<script data-optimized="1" id="avada-contact-form-7-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/cba694cff2c7f4c72e7a2fdc693ca508.js?ver=8a835" defer data-deferred="1"></script>
<script id="avada-comments-js-extra" src="data:text/javascript;base64,dmFyIGF2YWRhQ29tbWVudFZhcnM9eyJ0aXRsZV9zdHlsZV90eXBlIjoic2luZ2xlIHNvbGlkIiwidGl0bGVfbWFyZ2luX3RvcCI6IjBweCIsInRpdGxlX21hcmdpbl9ib3R0b20iOiIzMHB4In0=" defer></script>
<script data-optimized="1" id="avada-comments-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/5f02be46bcc7d1ed62df84ed2e32fd5e.js?ver=73a10" defer data-deferred="1"></script>
<script data-optimized="1" id="fusion-alert-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/0bc6b9b681cfe56c98ac249b901f4430.js?ver=1206e" defer data-deferred="1"></script>
<script data-optimized="1" id="awb-background-slider-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/99a6608632ee6a03b2b2dde62f6c3dcf.js?ver=796b0" defer data-deferred="1"></script>
<script id="fusion-flexslider-js-extra" src="data:text/javascript;base64,dmFyIGZ1c2lvbkZsZXhTbGlkZXJWYXJzPXsic3RhdHVzX3ZpbWVvIjoiIiwic2xpZGVzaG93X2F1dG9wbGF5IjoiMSIsInNsaWRlc2hvd19zcGVlZCI6IjcwMDAiLCJwYWdpbmF0aW9uX3ZpZGVvX3NsaWRlIjoiIiwic3RhdHVzX3l0IjoiIiwiZmxleF9zbW9vdGhIZWlnaHQiOiJmYWxzZSJ9" defer></script>
<script data-optimized="1" id="fusion-flexslider-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/3cb69f26d07794a81f20521aa1ebdb1e.js?ver=c5393" defer data-deferred="1"></script>
<script id="awb-carousel-js-extra" src="data:text/javascript;base64,dmFyIGF3YkNhcm91c2VsVmFycz17InJlbGF0ZWRfcG9zdHNfc3BlZWQiOiIyNTAwIiwiY2Fyb3VzZWxfc3BlZWQiOiIyMDAwIn0=" defer></script>
<script data-optimized="1" id="awb-carousel-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/676965e40d5fda12007e19f918aa9a4d.js?ver=f35dc" defer data-deferred="1"></script>
<script id="fusion-animations-js-extra" src="data:text/javascript;base64,dmFyIGZ1c2lvbkFuaW1hdGlvbnNWYXJzPXsic3RhdHVzX2Nzc19hbmltYXRpb25zIjoiZGVza3RvcCJ9" defer></script>
<script data-optimized="1" id="fusion-animations-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/d11f745c9892989292540840a0d325d0.js?ver=65f91" defer data-deferred="1"></script>
<script id="fusion-container-js-extra" src="data:text/javascript;base64,dmFyIGZ1c2lvbkNvbnRhaW5lclZhcnM9eyJjb250ZW50X2JyZWFrX3BvaW50IjoiODAwIiwiY29udGFpbmVyX2h1bmRyZWRfcGVyY2VudF9oZWlnaHRfbW9iaWxlIjoiMCIsImlzX3N0aWNreV9oZWFkZXJfdHJhbnNwYXJlbnQiOiIxIn0=" defer></script>
<script data-optimized="1" id="fusion-container-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/aabc9cbdb5c5b18874406f0c1b1d0e57.js?ver=03ca1" defer data-deferred="1"></script>
<script id="awb-widget-areas-js-extra" src="data:text/javascript;base64,dmFyIGF2YWRhU2lkZWJhcnNWYXJzPXsiaGVhZGVyX3Bvc2l0aW9uIjoidG9wIiwiaGVhZGVyX2xheW91dCI6InYyIiwiaGVhZGVyX3N0aWNreSI6IjEiLCJoZWFkZXJfc3RpY2t5X3R5cGUyX2xheW91dCI6Im1lbnVfb25seSIsInNpZGVfaGVhZGVyX2JyZWFrX3BvaW50IjoiMTA1MCIsImhlYWRlcl9zdGlja3lfdGFibGV0IjoiIiwic3RpY2t5X2hlYWRlcl9zaHJpbmthZ2UiOiIiLCJuYXZfaGVpZ2h0IjoiMTAzIiwic2lkZWJhcl9icmVha19wb2ludCI6IjgwMCJ9" defer></script>
<script data-optimized="1" id="awb-widget-areas-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/0411623fde2fddcf5c2c8f1937a4a36f.js?ver=35745" defer data-deferred="1"></script>
<script id="avada-fade-js-extra" src="data:text/javascript;base64,dmFyIGF2YWRhRmFkZVZhcnM9eyJwYWdlX3RpdGxlX2ZhZGluZyI6IjEiLCJoZWFkZXJfcG9zaXRpb24iOiJ0b3AifQ==" defer></script>
<script data-optimized="1" id="avada-fade-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/42e2c1fb2c6fc6ae36d97cfa800797e6.js?ver=5e953" defer data-deferred="1"></script>
<script id="avada-drop-down-js-extra" src="data:text/javascript;base64,dmFyIGF2YWRhU2VsZWN0VmFycz17ImF2YWRhX2Ryb3BfZG93biI6IjEifQ==" defer></script>
<script data-optimized="1" id="avada-drop-down-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/bbf28ff16d3c5aa1d1cb7a284de6a4d2.js?ver=7506f" defer data-deferred="1"></script>
<script id="avada-to-top-js-extra" src="data:text/javascript;base64,dmFyIGF2YWRhVG9Ub3BWYXJzPXsic3RhdHVzX3RvdG9wIjoiZGVza3RvcF9hbmRfbW9iaWxlIiwidG90b3BfcG9zaXRpb24iOiJyaWdodCIsInRvdG9wX3Njcm9sbF9kb3duX29ubHkiOiIxIn0=" defer></script>
<script data-optimized="1" id="avada-to-top-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/90be7be21880207d646a43c87dbe3d94.js?ver=2a31d" defer data-deferred="1"></script>
<script id="avada-header-js-extra" src="data:text/javascript;base64,dmFyIGF2YWRhSGVhZGVyVmFycz17ImhlYWRlcl9wb3NpdGlvbiI6InRvcCIsImhlYWRlcl9zdGlja3kiOiIxIiwiaGVhZGVyX3N0aWNreV90eXBlMl9sYXlvdXQiOiJtZW51X29ubHkiLCJoZWFkZXJfc3RpY2t5X3NoYWRvdyI6IjEiLCJzaWRlX2hlYWRlcl9icmVha19wb2ludCI6IjEwNTAiLCJoZWFkZXJfc3RpY2t5X21vYmlsZSI6IiIsImhlYWRlcl9zdGlja3lfdGFibGV0IjoiIiwibW9iaWxlX21lbnVfZGVzaWduIjoibW9kZXJuIiwic3RpY2t5X2hlYWRlcl9zaHJpbmthZ2UiOiIiLCJuYXZfaGVpZ2h0IjoiMTAzIiwibmF2X2hpZ2hsaWdodF9ib3JkZXIiOiIzIiwibmF2X2hpZ2hsaWdodF9zdHlsZSI6ImJhciIsImxvZ29fbWFyZ2luX3RvcCI6IjMxcHgiLCJsb2dvX21hcmdpbl9ib3R0b20iOiIzMXB4IiwibGF5b3V0X21vZGUiOiJ3aWRlIiwiaGVhZGVyX3BhZGRpbmdfdG9wIjoiMzBweCIsImhlYWRlcl9wYWRkaW5nX2JvdHRvbSI6IjMwcHgiLCJzY3JvbGxfb2Zmc2V0IjoiZnVsbCJ9" defer></script>
<script data-optimized="1" id="avada-header-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/c5451df4cc6dffacfdedfe1cf2b473c6.js?ver=4397a" defer data-deferred="1"></script>
<script id="avada-menu-js-extra" src="data:text/javascript;base64,dmFyIGF2YWRhTWVudVZhcnM9eyJzaXRlX2xheW91dCI6IndpZGUiLCJoZWFkZXJfcG9zaXRpb24iOiJ0b3AiLCJsb2dvX2FsaWdubWVudCI6ImxlZnQiLCJoZWFkZXJfc3RpY2t5IjoiMSIsImhlYWRlcl9zdGlja3lfbW9iaWxlIjoiIiwiaGVhZGVyX3N0aWNreV90YWJsZXQiOiIiLCJzaWRlX2hlYWRlcl9icmVha19wb2ludCI6IjEwNTAiLCJtZWdhbWVudV9iYXNlX3dpZHRoIjoiY3VzdG9tX3dpZHRoIiwibW9iaWxlX21lbnVfZGVzaWduIjoibW9kZXJuIiwiZHJvcGRvd25fZ290byI6IkdvIHRvLi4uIiwibW9iaWxlX25hdl9jYXJ0IjoiU2hvcHBpbmcgQ2FydCIsIm1vYmlsZV9zdWJtZW51X29wZW4iOiJPcGVuIHN1Ym1lbnUgb2YgJXMiLCJtb2JpbGVfc3VibWVudV9jbG9zZSI6IkNsb3NlIHN1Ym1lbnUgb2YgJXMiLCJzdWJtZW51X3NsaWRlb3V0IjoiMSJ9" defer></script>
<script data-optimized="1" id="avada-menu-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/fdfdd9f54eaace3448c35d60ad80612e.js?ver=0e41f" defer data-deferred="1"></script>
<script data-optimized="1" id="awb-scrollspy-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/09043d9a3a9126fb5372d29f6a1db65a.js?ver=6c4cc" defer data-deferred="1"></script>
<script data-optimized="1" id="avada-scrollspy-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/aa9eca04f870fe01c6554bbf0749aacb.js?ver=151f2" defer data-deferred="1"></script>
<script data-optimized="1" id="avada-woo-products-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/7bd4cd15d3071a8ad2bca6f0d998e487.js?ver=c2eee" defer data-deferred="1"></script>
<script id="avada-woocommerce-js-extra" src="data:text/javascript;base64,dmFyIGF2YWRhV29vQ29tbWVyY2VWYXJzPXsib3JkZXJfYWN0aW9ucyI6IkRldGFpbHMiLCJ0aXRsZV9zdHlsZV90eXBlIjoic2luZ2xlIHNvbGlkIiwid29vY29tbWVyY2Vfc2hvcF9wYWdlX2NvbHVtbnMiOiI0Iiwid29vY29tbWVyY2VfY2hlY2tvdXRfZXJyb3IiOiJOb3QgYWxsIGZpZWxkcyBoYXZlIGJlZW4gZmlsbGVkIGluIGNvcnJlY3RseS4iLCJyZWxhdGVkX3Byb2R1Y3RzX2hlYWRpbmdfc2l6ZSI6IjIiLCJhamF4dXJsIjoiaHR0cHM6Ly93d3cubG93Y29zdHdlYmFnZW5jeS5jb20vd3AtYWRtaW4vYWRtaW4tYWpheC5waHAiLCJjYXJ0X25vbmNlIjoiZTcxYjQ3MjQxYiIsInF1aWNrX3ZpZXdfbm9uY2UiOiJlMDM5MjdlN2M5IiwicXVpY2tfdmlld19jbG9zZSI6IkNsb3NlIHByb2R1Y3QgcXVpY2sgdmlldyIsInF1aWNrX3ZpZXdfdGl0bGUiOiJUaXRsZSIsInNob3BfcGFnZV9iZ19jb2xvciI6IiNmZmZmZmYiLCJzaG9wX3BhZ2VfYmdfY29sb3JfbGlnaHRuZXNzIjoiMTAwIiwicG9zdF90aXRsZV9mb250X3NpemUiOiIyNiIsImFqYXhfdXBkYXRlX2NhcnRfdmFsdWVzIjoiMSIsIndvb19hamF4X2ZpbHRlcnMiOiJubyIsIndvb19hamF4X3NvcnRpbmciOiIwIiwid29vX2FqYXhfY2F0ZWdvcmllcyI6Im9mZiJ9" defer></script>
<script data-optimized="1" id="avada-woocommerce-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/7c22006f21326b46baf8c96d4fe176c2.js?ver=48ba2" defer data-deferred="1"></script>
<script data-optimized="1" id="avada-woo-product-images-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/e5ff1bf4d86a6642def4423c37f399b7.js?ver=25363" defer data-deferred="1"></script>
<script id="fusion-responsive-typography-js-extra" src="data:text/javascript;base64,dmFyIGZ1c2lvblR5cG9ncmFwaHlWYXJzPXsic2l0ZV93aWR0aCI6IjE0MDBweCIsInR5cG9ncmFwaHlfc2Vuc2l0aXZpdHkiOiIwLjU0IiwidHlwb2dyYXBoeV9mYWN0b3IiOiIxLjUwIiwiZWxlbWVudHMiOiJoMSwgaDIsIGgzLCBoNCwgaDUsIGg2In0=" defer></script>
<script data-optimized="1" id="fusion-responsive-typography-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/bc6178fd5c47ab54e0056a094ee994dc.js?ver=af0b6" defer data-deferred="1"></script>
<script id="fusion-scroll-to-anchor-js-extra" src="data:text/javascript;base64,dmFyIGZ1c2lvblNjcm9sbFRvQW5jaG9yVmFycz17ImNvbnRlbnRfYnJlYWtfcG9pbnQiOiI4MDAiLCJjb250YWluZXJfaHVuZHJlZF9wZXJjZW50X2hlaWdodF9tb2JpbGUiOiIwIn0=" defer></script>
<script data-optimized="1" id="fusion-scroll-to-anchor-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/a48e74a65e9c7f6d4a28126b91cd4f8f.js?ver=cc70b" defer data-deferred="1"></script>
<script id="fusion-video-js-extra" src="data:text/javascript;base64,dmFyIGZ1c2lvblZpZGVvVmFycz17InN0YXR1c192aW1lbyI6IjAifQ==" defer></script>
<script data-optimized="1" id="fusion-video-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/b9908f7f9e91fd01104dc4e6e7af8efe.js?ver=69ca8" defer data-deferred="1"></script>
<script data-optimized="1" id="fusion-column-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/e1165df2c89a619f5f6aa3bd667bde43.js?ver=435be" defer data-deferred="1"></script>
<script id="wc-cart-fragments-js-extra" src="data:text/javascript;base64,dmFyIHdjX2NhcnRfZnJhZ21lbnRzX3BhcmFtcz17ImFqYXhfdXJsIjoiL3dwLWFkbWluL2FkbWluLWFqYXgucGhwIiwid2NfYWpheF91cmwiOiIvP3djLWFqYXg9JSVlbmRwb2ludCUlIiwiY2FydF9oYXNoX2tleSI6IndjX2NhcnRfaGFzaF9mYTZiNmUyY2RhZDRmYmFiNWUyY2E3MWU5YzhiMTllYS1lbi1VU0QiLCJmcmFnbWVudF9uYW1lIjoid2NfZnJhZ21lbnRzX2ZhNmI2ZTJjZGFkNGZiYWI1ZTJjYTcxZTljOGIxOWVhLWVuLVVTRCIsInJlcXVlc3RfdGltZW91dCI6IjUwMDAifQ==" defer></script>
<script data-optimized="1" data-wp-strategy="defer" defer id="wc-cart-fragments-js" src="https://www.lowcostwebagency.com/wp-content/litespeed/js/7d81cfa231efbb9d8db5d9cc39ea7ef8.js?ver=592fb"></script>
<script type="text/javascript" src="data:text/javascript;base64,aWYodHlwZW9mIHdvb2NvbW1lcmNlX3ByaWNlX3NsaWRlcl9wYXJhbXMhPT0ndW5kZWZpbmVkJyl7d29vY29tbWVyY2VfcHJpY2Vfc2xpZGVyX3BhcmFtcy5jdXJyZW5jeV9mb3JtYXRfc3ltYm9sPXdjbWxfbWNfc2V0dGluZ3MuY3VycmVudF9jdXJyZW5jeS5zeW1ib2x9" defer></script>
</div>
<section class="to-top-container to-top-right awb-to-top-text-before" aria-labelledby="awb-to-top-label">
<a href="#" id="toTop" class="fusion-top-top-link">
<span id="awb-to-top-label" class="screen-reader-text">Go to Top</span>
</a>
</section>
<script data-no-optimize="1">window.lazyLoadOptions=Object.assign({},{threshold:300},window.lazyLoadOptions||{});!function(t,e){"object"==typeof exports&&"undefined"!=typeof module?module.exports=e():"function"==typeof define&&define.amd?define(e):(t="undefined"!=typeof globalThis?globalThis:t||self).LazyLoad=e()}(this,function(){"use strict";function e(){return(e=Object.assign||function(t){for(var e=1;e<arguments.length;e++){var n,a=arguments[e];for(n in a)Object.prototype.hasOwnProperty.call(a,n)&&(t[n]=a[n])}return t}).apply(this,arguments)}function o(t){return e({},at,t)}function l(t,e){return t.getAttribute(gt+e)}function c(t){return l(t,vt)}function s(t,e){return function(t,e,n){e=gt+e;null!==n?t.setAttribute(e,n):t.removeAttribute(e)}(t,vt,e)}function i(t){return s(t,null),0}function r(t){return null===c(t)}function u(t){return c(t)===_t}function d(t,e,n,a){t&&(void 0===a?void 0===n?t(e):t(e,n):t(e,n,a))}function f(t,e){et?t.classList.add(e):t.className+=(t.className?" ":"")+e}function _(t,e){et?t.classList.remove(e):t.className=t.className.replace(new RegExp("(^|\\s+)"+e+"(\\s+|$)")," ").replace(/^\s+/,"").replace(/\s+$/,"")}function g(t){return t.llTempImage}function v(t,e){!e||(e=e._observer)&&e.unobserve(t)}function b(t,e){t&&(t.loadingCount+=e)}function p(t,e){t&&(t.toLoadCount=e)}function n(t){for(var e,n=[],a=0;e=t.children[a];a+=1)"SOURCE"===e.tagName&&n.push(e);return n}function h(t,e){(t=t.parentNode)&&"PICTURE"===t.tagName&&n(t).forEach(e)}function a(t,e){n(t).forEach(e)}function m(t){return!!t[lt]}function E(t){return t[lt]}function I(t){return delete t[lt]}function y(e,t){var n;m(e)||(n={},t.forEach(function(t){n[t]=e.getAttribute(t)}),e[lt]=n)}function L(a,t){var o;m(a)&&(o=E(a),t.forEach(function(t){var e,n;e=a,(t=o[n=t])?e.setAttribute(n,t):e.removeAttribute(n)}))}function k(t,e,n){f(t,e.class_loading),s(t,st),n&&(b(n,1),d(e.callback_loading,t,n))}function A(t,e,n){n&&t.setAttribute(e,n)}function O(t,e){A(t,rt,l(t,e.data_sizes)),A(t,it,l(t,e.data_srcset)),A(t,ot,l(t,e.data_src))}function w(t,e,n){var a=l(t,e.data_bg_multi),o=l(t,e.data_bg_multi_hidpi);(a=nt&&o?o:a)&&(t.style.backgroundImage=a,n=n,f(t=t,(e=e).class_applied),s(t,dt),n&&(e.unobserve_completed&&v(t,e),d(e.callback_applied,t,n)))}function x(t,e){!e||0<e.loadingCount||0<e.toLoadCount||d(t.callback_finish,e)}function M(t,e,n){t.addEventListener(e,n),t.llEvLisnrs[e]=n}function N(t){return!!t.llEvLisnrs}function z(t){if(N(t)){var e,n,a=t.llEvLisnrs;for(e in a){var o=a[e];n=e,o=o,t.removeEventListener(n,o)}delete t.llEvLisnrs}}function C(t,e,n){var a;delete t.llTempImage,b(n,-1),(a=n)&&--a.toLoadCount,_(t,e.class_loading),e.unobserve_completed&&v(t,n)}function R(i,r,c){var l=g(i)||i;N(l)||function(t,e,n){N(t)||(t.llEvLisnrs={});var a="VIDEO"===t.tagName?"loadeddata":"load";M(t,a,e),M(t,"error",n)}(l,function(t){var e,n,a,o;n=r,a=c,o=u(e=i),C(e,n,a),f(e,n.class_loaded),s(e,ut),d(n.callback_loaded,e,a),o||x(n,a),z(l)},function(t){var e,n,a,o;n=r,a=c,o=u(e=i),C(e,n,a),f(e,n.class_error),s(e,ft),d(n.callback_error,e,a),o||x(n,a),z(l)})}function T(t,e,n){var a,o,i,r,c;t.llTempImage=document.createElement("IMG"),R(t,e,n),m(c=t)||(c[lt]={backgroundImage:c.style.backgroundImage}),i=n,r=l(a=t,(o=e).data_bg),c=l(a,o.data_bg_hidpi),(r=nt&&c?c:r)&&(a.style.backgroundImage='url("'.concat(r,'")'),g(a).setAttribute(ot,r),k(a,o,i)),w(t,e,n)}function G(t,e,n){var a;R(t,e,n),a=e,e=n,(t=Et[(n=t).tagName])&&(t(n,a),k(n,a,e))}function D(t,e,n){var a;a=t,(-1<It.indexOf(a.tagName)?G:T)(t,e,n)}function S(t,e,n){var a;t.setAttribute("loading","lazy"),R(t,e,n),a=e,(e=Et[(n=t).tagName])&&e(n,a),s(t,_t)}function V(t){t.removeAttribute(ot),t.removeAttribute(it),t.removeAttribute(rt)}function j(t){h(t,function(t){L(t,mt)}),L(t,mt)}function F(t){var e;(e=yt[t.tagName])?e(t):m(e=t)&&(t=E(e),e.style.backgroundImage=t.backgroundImage)}function P(t,e){var n;F(t),n=e,r(e=t)||u(e)||(_(e,n.class_entered),_(e,n.class_exited),_(e,n.class_applied),_(e,n.class_loading),_(e,n.class_loaded),_(e,n.class_error)),i(t),I(t)}function U(t,e,n,a){var o;n.cancel_on_exit&&(c(t)!==st||"IMG"===t.tagName&&(z(t),h(o=t,function(t){V(t)}),V(o),j(t),_(t,n.class_loading),b(a,-1),i(t),d(n.callback_cancel,t,e,a)))}function $(t,e,n,a){var o,i,r=(i=t,0<=bt.indexOf(c(i)));s(t,"entered"),f(t,n.class_entered),_(t,n.class_exited),o=t,i=a,n.unobserve_entered&&v(o,i),d(n.callback_enter,t,e,a),r||D(t,n,a)}function q(t){return t.use_native&&"loading"in HTMLImageElement.prototype}function H(t,o,i){t.forEach(function(t){return(a=t).isIntersecting||0<a.intersectionRatio?$(t.target,t,o,i):(e=t.target,n=t,a=o,t=i,void(r(e)||(f(e,a.class_exited),U(e,n,a,t),d(a.callback_exit,e,n,t))));var e,n,a})}function B(e,n){var t;tt&&!q(e)&&(n._observer=new IntersectionObserver(function(t){H(t,e,n)},{root:(t=e).container===document?null:t.container,rootMargin:t.thresholds||t.threshold+"px"}))}function J(t){return Array.prototype.slice.call(t)}function K(t){return t.container.querySelectorAll(t.elements_selector)}function Q(t){return c(t)===ft}function W(t,e){return e=t||K(e),J(e).filter(r)}function X(e,t){var n;(n=K(e),J(n).filter(Q)).forEach(function(t){_(t,e.class_error),i(t)}),t.update()}function t(t,e){var n,a,t=o(t);this._settings=t,this.loadingCount=0,B(t,this),n=t,a=this,Y&&window.addEventListener("online",function(){X(n,a)}),this.update(e)}var Y="undefined"!=typeof window,Z=Y&&!("onscroll"in window)||"undefined"!=typeof navigator&&/(gle|ing|ro)bot|crawl|spider/i.test(navigator.userAgent),tt=Y&&"IntersectionObserver"in window,et=Y&&"classList"in document.createElement("p"),nt=Y&&1<window.devicePixelRatio,at={elements_selector:".lazy",container:Z||Y?document:null,threshold:300,thresholds:null,data_src:"src",data_srcset:"srcset",data_sizes:"sizes",data_bg:"bg",data_bg_hidpi:"bg-hidpi",data_bg_multi:"bg-multi",data_bg_multi_hidpi:"bg-multi-hidpi",data_poster:"poster",class_applied:"applied",class_loading:"litespeed-loading",class_loaded:"litespeed-loaded",class_error:"error",class_entered:"entered",class_exited:"exited",unobserve_completed:!0,unobserve_entered:!1,cancel_on_exit:!0,callback_enter:null,callback_exit:null,callback_applied:null,callback_loading:null,callback_loaded:null,callback_error:null,callback_finish:null,callback_cancel:null,use_native:!1},ot="src",it="srcset",rt="sizes",ct="poster",lt="llOriginalAttrs",st="loading",ut="loaded",dt="applied",ft="error",_t="native",gt="data-",vt="ll-status",bt=[st,ut,dt,ft],pt=[ot],ht=[ot,ct],mt=[ot,it,rt],Et={IMG:function(t,e){h(t,function(t){y(t,mt),O(t,e)}),y(t,mt),O(t,e)},IFRAME:function(t,e){y(t,pt),A(t,ot,l(t,e.data_src))},VIDEO:function(t,e){a(t,function(t){y(t,pt),A(t,ot,l(t,e.data_src))}),y(t,ht),A(t,ct,l(t,e.data_poster)),A(t,ot,l(t,e.data_src)),t.load()}},It=["IMG","IFRAME","VIDEO"],yt={IMG:j,IFRAME:function(t){L(t,pt)},VIDEO:function(t){a(t,function(t){L(t,pt)}),L(t,ht),t.load()}},Lt=["IMG","IFRAME","VIDEO"];return t.prototype={update:function(t){var e,n,a,o=this._settings,i=W(t,o);{if(p(this,i.length),!Z&&tt)return q(o)?(e=o,n=this,i.forEach(function(t){-1!==Lt.indexOf(t.tagName)&&S(t,e,n)}),void p(n,0)):(t=this._observer,o=i,t.disconnect(),a=t,void o.forEach(function(t){a.observe(t)}));this.loadAll(i)}},destroy:function(){this._observer&&this._observer.disconnect(),K(this._settings).forEach(function(t){I(t)}),delete this._observer,delete this._settings,delete this.loadingCount,delete this.toLoadCount},loadAll:function(t){var e=this,n=this._settings;W(t,n).forEach(function(t){v(t,e),D(t,n,e)})},restoreAll:function(){var e=this._settings;K(e).forEach(function(t){P(t,e)})}},t.load=function(t,e){e=o(e);D(t,e)},t.resetStatus=function(t){i(t)},t}),function(t,e){"use strict";function n(){e.body.classList.add("litespeed_lazyloaded")}function a(){console.log("[LiteSpeed] Start Lazy Load"),o=new LazyLoad(Object.assign({},t.lazyLoadOptions||{},{elements_selector:"[data-lazyloaded]",callback_finish:n})),i=function(){o.update()},t.MutationObserver&&new MutationObserver(i).observe(e.documentElement,{childList:!0,subtree:!0,attributes:!0})}var o,i;t.addEventListener?t.addEventListener("load",a,!1):t.attachEvent("onload",a)}(window,document);</script><script>window.litespeed_ui_events=window.litespeed_ui_events||["mouseover","click","keydown","wheel","touchmove","touchstart","pointerup","pointerdown"];var urlCreator=window.URL||window.webkitURL;function litespeed_load_delayed_js_force(){console.log("[LiteSpeed] Start Load JS Delayed"),litespeed_ui_events.forEach(e=>{window.removeEventListener(e,litespeed_load_delayed_js_force,{passive:!0})}),document.querySelectorAll("iframe[data-litespeed-src]").forEach(e=>{e.setAttribute("src",e.getAttribute("data-litespeed-src"))}),"loading"==document.readyState?window.addEventListener("DOMContentLoaded",litespeed_load_delayed_js):litespeed_load_delayed_js()}litespeed_ui_events.forEach(e=>{window.addEventListener(e,litespeed_load_delayed_js_force,{passive:!0})});async function litespeed_load_delayed_js(){let t=[];for(var d in document.querySelectorAll('script[type="litespeed/javascript"]').forEach(e=>{t.push(e)}),t)await new Promise(e=>litespeed_load_one(t[d],e));document.dispatchEvent(new Event("DOMContentLiteSpeedLoaded")),window.dispatchEvent(new Event("DOMContentLiteSpeedLoaded"))}function litespeed_load_one(t,e){console.log("[LiteSpeed] Load ",t);function d(){o.src.startsWith("blob:")&&URL.revokeObjectURL(o.src),e()}var o=document.createElement("script");o.addEventListener("load",d),o.addEventListener("error",d),t.getAttributeNames().forEach(e=>{"type"!=e&&o.setAttribute("data-src"==e?"src":e,t.getAttribute(e))}),o.type="text/javascript",!o.src&&t.textContent&&(o.src=litespeed_inline2src(t.textContent)),t.after(o),t.remove()}function litespeed_inline2src(t){try{var d=urlCreator.createObjectURL(new Blob([t.replace(/^(?:<!--)?(.*?)(?:-->)?$/gm,"$1")],{type:"text/javascript"}))}catch(e){d="data:text/javascript;base64,"+btoa(t.replace(/^(?:<!--)?(.*?)(?:-->)?$/gm,"$1"))}return d}</script></body>
</html>
<!-- Page cached by LiteSpeed Cache 7.9.1 on 2026-10-12 18:30:06 -->